
WhisperDocs — RAG Agentico com LangGraph
FrancoCazal/WhisperDocs
RAG agentico full-stack com chat, WhatsApp e eval suite integrados
Ver no GitHubAgent de Retrieval-Augmented Generation (RAG) construído com LangGraph que integra busca híbrida (vector + BM25), roteamento multi-provider (Gemini + Claude via AWS Bedrock) e interface de chat em tempo real com streaming SSE. Inclui ingesta assíncrona de documentos, integração WhatsApp via Twilio, suite de avaliação com 50 queries e tracking de custo por chamada.
Instalação
npx convez-ai FrancoCazal/WhisperDocs1 comando no terminal: detecta o formato do repositório (marketplace ou plugin avulso) e instala via Claude Code. Requer Node 18+ e o Claude Code instalado.
Métricas
Casos de uso
- Construir assistentes que respondem perguntas sobre documentos proprietários
- Implementar pipelines RAG com transparência de retrieval e citações
- Entregar chatbots de suporte via WhatsApp com rastreamento de custo
- Validar qualidade de RAG com suite automática de 50 queries
Veredito

Projeto sólido de referência para RAG agentico em produção: LangGraph bem estruturado, retrieval híbrido robusto, multi-provider routing e eval suite são diferenciais reais. Stack moderno (FastAPI, pgvector, LangGraph, SSE) com decisões arquiteturais documentadas; roda localmente via Docker, sem hosted deployment.
README
A tradução para o português deste README ainda está na fila.
WhisperDocs


Agentic RAG over your own documents — chat UI, WhatsApp delivery, hybrid retrieval, multi-provider LLMs, real eval suite.
Portfolio project — runs locally via Docker. No hosted deployment. Clone, fill
.env,docker compose up.
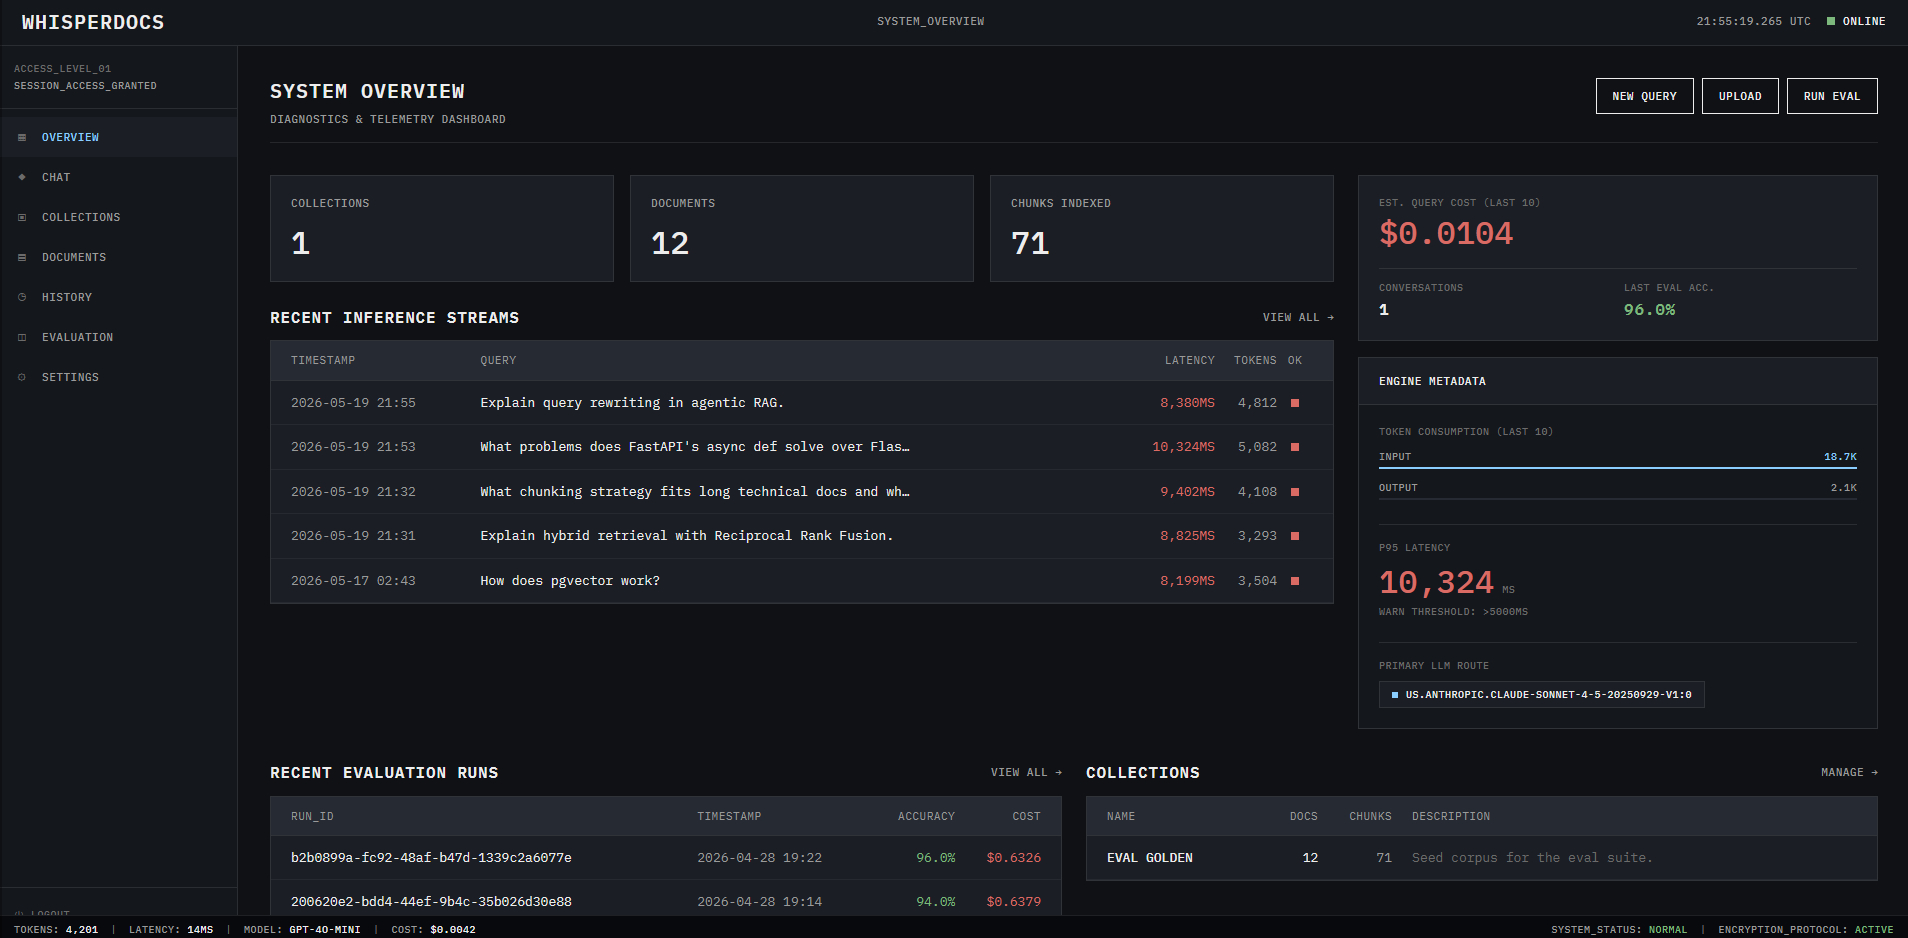
Stack · FastAPI · PostgreSQL + pgvector · LangGraph · Gemini + AWS Bedrock (Claude) · OpenAI Embeddings · Twilio · React + TanStack Router · structlog · Prometheus
See ARCHITECTURE.md for component diagrams, sequence flows, and data model. Decision records live under docs/adr/.
Highlights
- Agentic RAG with LangGraph — explicit state graph, 7 nodes (compaction, summarize, classifier, search, clarify, direct, out-of-scope). Each node testable in isolation;
AsyncPostgresSaverhandles persistence. - Hybrid retrieval — vector cosine via pgvector + BM25 via tsvector, fused with Reciprocal Rank Fusion. Optional cross-encoder rerank (
bge-reranker-base) + document-level MMR for diversity. - Multi-provider routing — Gemini 2.5 Flash for cheap hot-path nodes (classifier, query rewrite, direct answers); AWS Bedrock Claude for grounded RAG generation. Provider auto-detected from model ID.
- Token-level SSE streaming —
astream_eventsv2 + custom event dispatch. Frontend renders tokens as they arrive, with progress markers per node. - Async ingestion with progress —
IngestionJobrow + asyncio worker. Per-stage progress (extracting → chunking → embedding → persisting). Frontend bar updates over SSE. - Eval suite (50-query golden set) — LLM-as-judge for correctness + hallucination, retrieval precision/recall@k, latency p50/p95, cost USD. Diff between runs for regression detection.
- Cost tracking — per-call USD via
pricing.py, persisted onquery_logs. Single source for runner, API, dashboard. - Structured logging + metrics —
structlogJSON output, Prometheus/metrics(turn duration, tokens, retrieval relevance, errors). - WhatsApp integration — full agent pipeline over Twilio webhooks.
Screens
Multi-turn chat with grounded citations
Inline [n] citations resolve to the source documents pulled by the retrieval pipeline.
Per-turn metadata footer shows latency, input/output tokens, model, and USD cost.
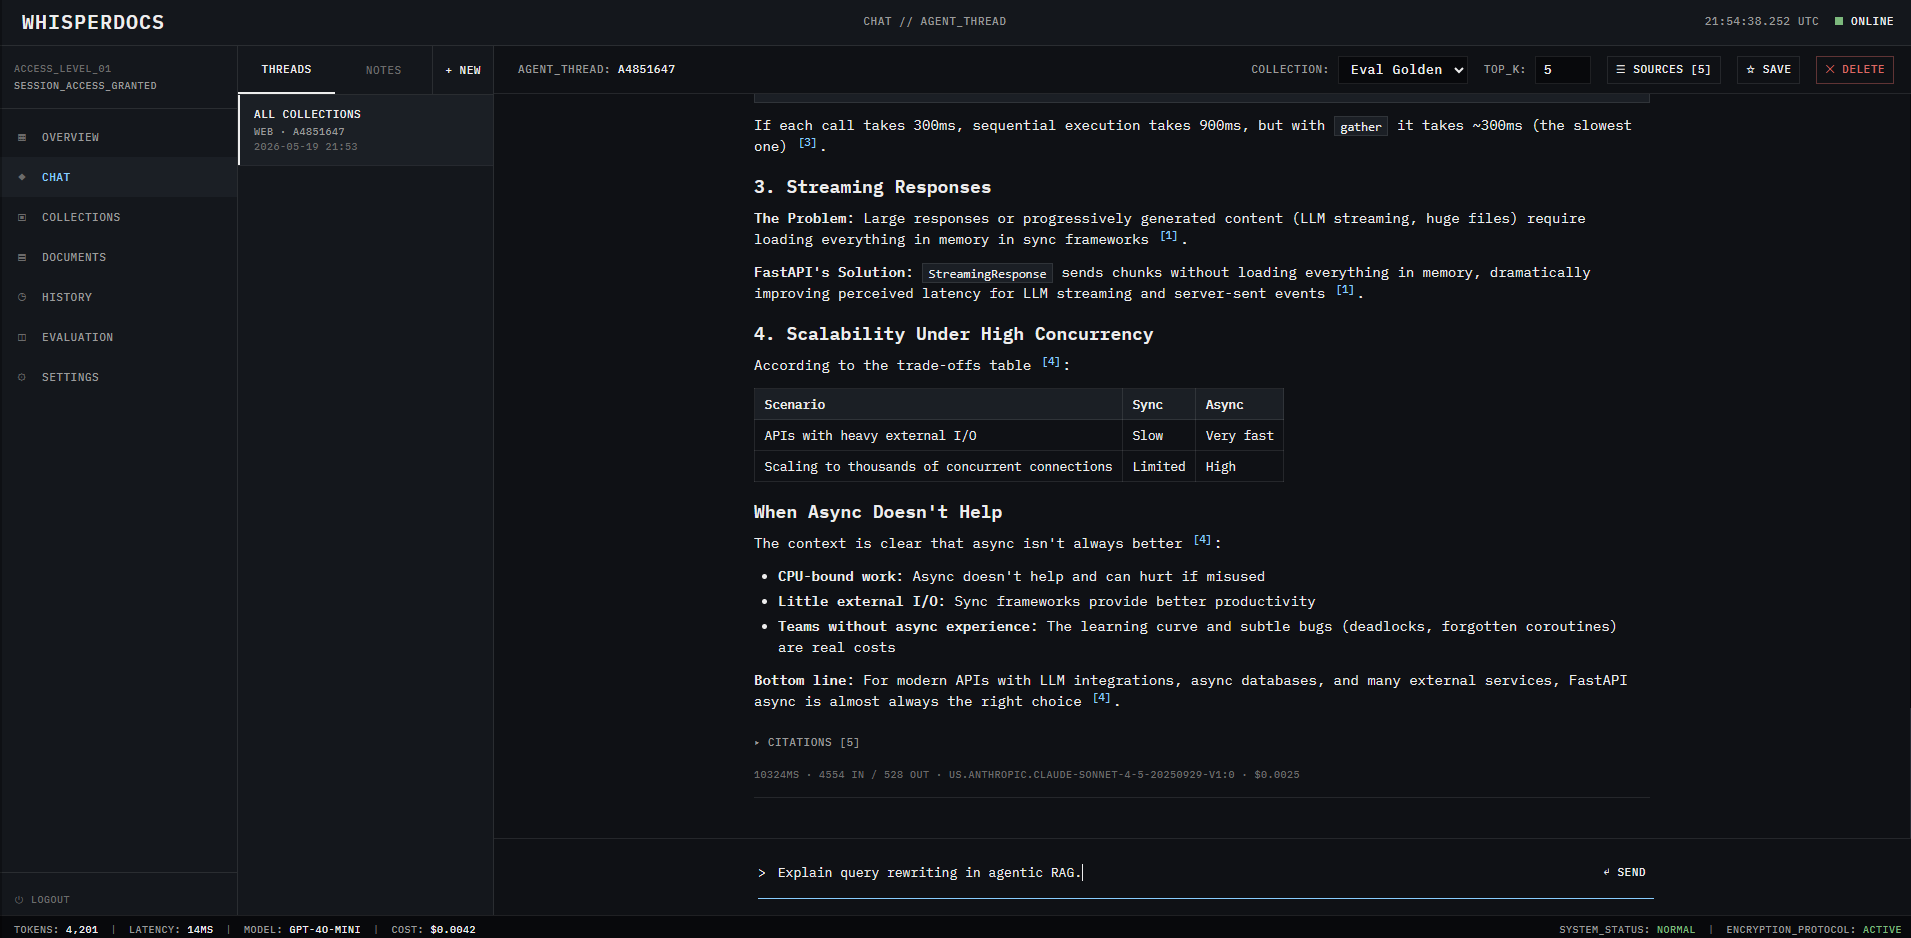
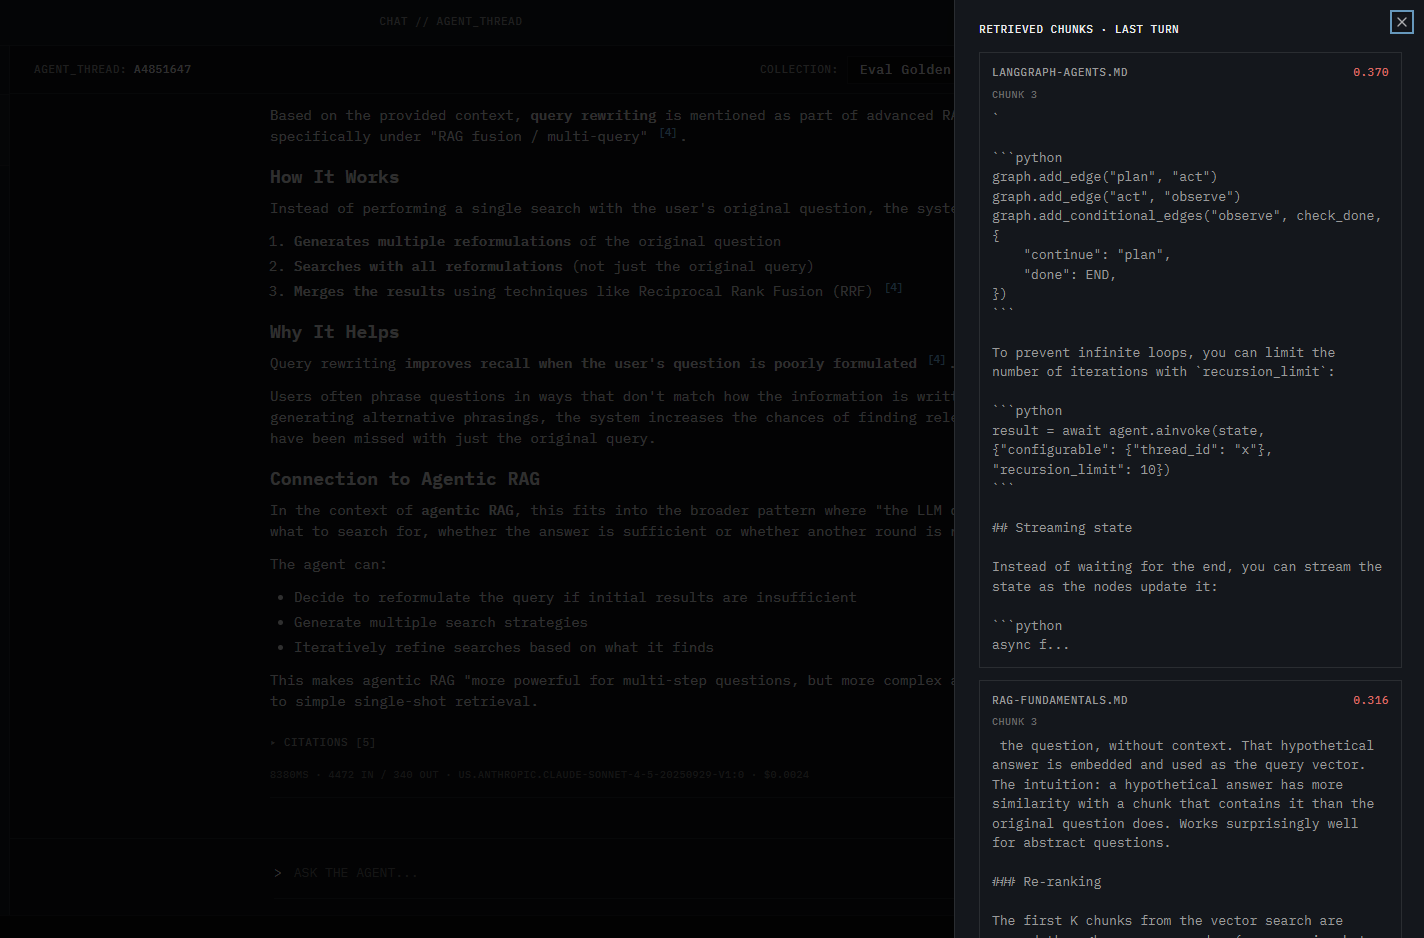
Retrieval transparency
Every turn exposes the chunks that were actually retrieved — text, source document, and RRF score after rerank/MMR. Lets you debug retrieval without leaving the chat.
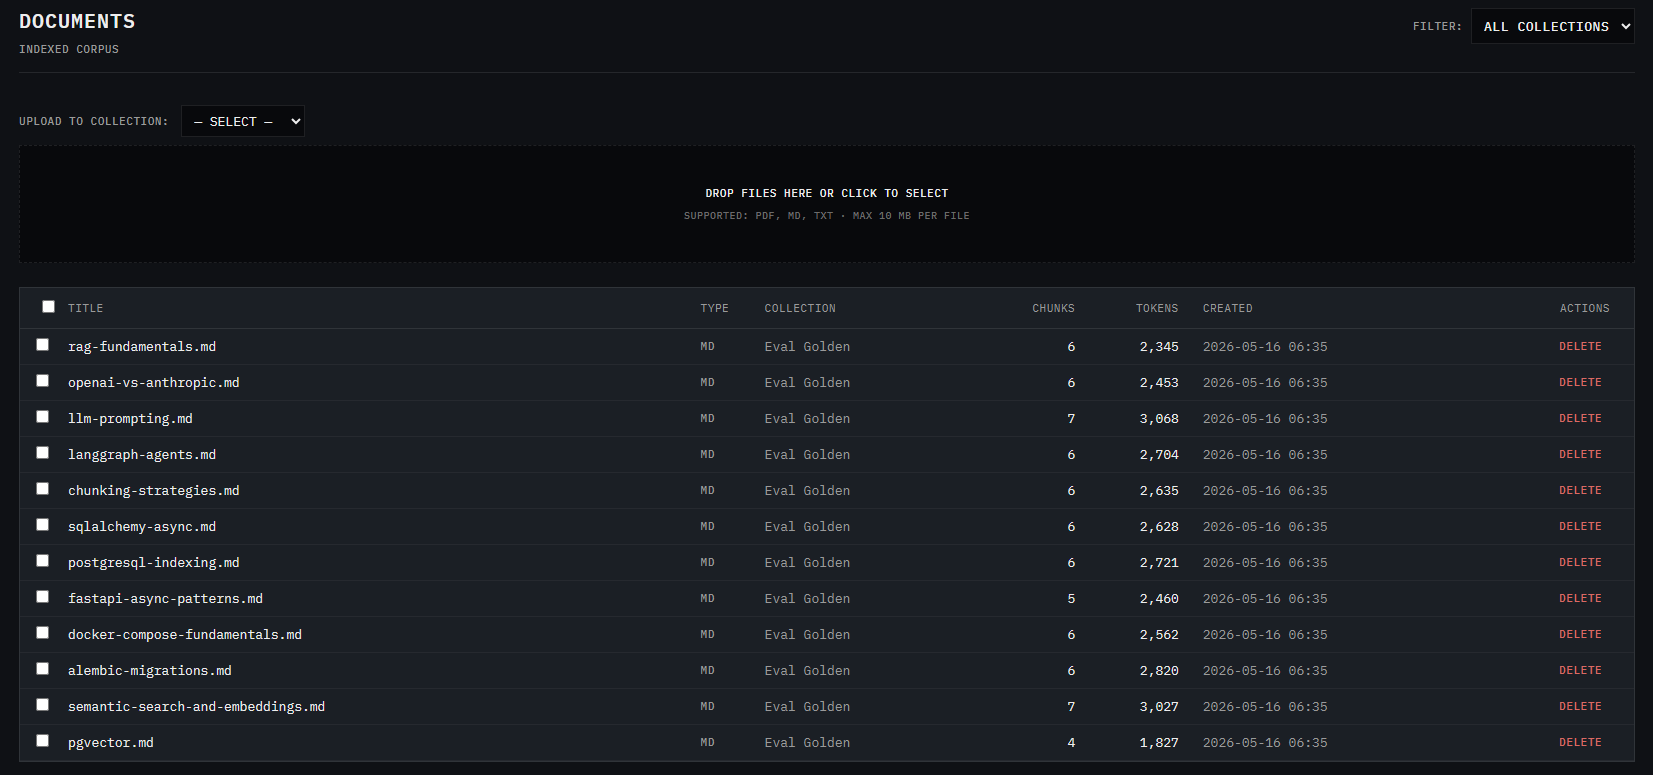
Indexed corpus
Drop PDF / MD / TXT files into any collection. Each file streams through the async ingestion pipeline; chunk and token counts are visible per document.
Quickstart
git clone <this-repo> && cd WhisperDocs
cp .env.example .env
# See "Minimum to run" below for which keys to fill.
docker compose up --build
Postgres (with pgvector) runs in the compose stack; no host install needed. DATABASE_URL already points at the in-network DB and Alembic migrations run automatically on container start.
| Service | URL |
|---|---|
| API | http://localhost:8000 |
| Swagger | http://localhost:8000/docs |
| Frontend | http://localhost:8080 |
/metrics | http://localhost:8000/api/v1/metrics |
Minimum to run
| Required | Why |
|---|---|
OPENAI_API_KEY | Embeddings (text-embedding-3-small) — no fallback. |
One generation provider: GCP_PROJECT (Vertex AI / Gemini) or AWS_ACCESS_KEY_ID + AWS_SECRET_ACCESS_KEY (Bedrock Claude) | Agent nodes route by model ID. Default config uses Gemini for hot-path nodes and Bedrock for RAG generation; override via AGENT_MODEL_* env vars to consolidate on one provider. |
Twilio, reranker, and MMR are all optional. Without Twilio the WhatsApp channel just stays inert; the chat UI works.
Gemini auth tip: Vertex AI uses Application Default Credentials. Run
gcloud auth application-default loginon the host —docker-compose.ymlmounts the resulting ADC file into the API container.
Local dev
python -m venv .venv && source .venv/bin/activate
pip install -e ".[dev]"
cp .env.example .env
alembic upgrade head
uvicorn app.main:app --reload

cd frontend && npm install && npm run dev
Environment
DATABASE_URL=postgresql+asyncpg://user:pass@localhost:5435/whisperdocs
OPENAI_API_KEY=sk-...

# Generation providers
GCP_PROJECT=...                  # Gemini via Vertex AI; auth via `gcloud auth application-default login`
GCP_LOCATION=us-central1
AWS_ACCESS_KEY_ID=...
AWS_SECRET_ACCESS_KEY=...
AWS_REGION=us-east-1

# Optional
TWILIO_ACCOUNT_SID=...           # WhatsApp
TWILIO_AUTH_TOKEN=...
RERANKER_ENABLED=false           # cross-encoder reranking (needs .[rerank])
MMR_ENABLED=false                # source diversity
AGENT_STREAMING_TOKENS=true      # token-level SSE
See .env.example for every knob.
API surface
| Method | Path | Description |
|---|---|---|
POST | /api/v1/collections | Create a collection |
GET | /api/v1/collections | List collections |
POST | /api/v1/documents/upload | Sync ingest (small docs) |
POST | /api/v1/documents/upload-batch | Sync batch ingest |
POST | /api/v1/documents/upload-async | Async ingest, returns job_id |
GET | /api/v1/documents/jobs/{job_id}/stream | SSE: ingestion progress |
POST | /api/v1/documents/bulk-delete | Delete many documents |
POST | /api/v1/documents/bulk-move | Move documents between collections |
POST | /api/v1/query | Single-turn RAG query |
GET | /api/v1/query/history | Paginated query log |
POST | /api/v1/agent/chat | Multi-turn agent chat |
POST | /api/v1/agent/chat/stream | SSE: node + token events |
GET | /api/v1/conversations | List conversations |
GET | /api/v1/conversations/{thread_id}/messages | Conversation history |
PATCH | /api/v1/conversations/{thread_id} | Update conversation (e.g. is_saved) |
DELETE | /api/v1/conversations/{thread_id} | Delete conversation |
GET | /api/v1/notes | List saved notes |
DELETE | /api/v1/notes/{note_id} | Delete saved note |
POST | /api/v1/webhooks/whatsapp | Twilio inbound webhook |
POST | /api/v1/webhooks/whatsapp/status | Twilio delivery-status callback |
POST | /api/v1/eval/run | Eval suite |
GET | /api/v1/eval/results | List past eval reports |
GET | /api/v1/admin/settings | Runtime settings snapshot |
GET | /api/v1/health | Health check (?deep=true for full probe) |
GET | /api/v1/metrics | Prometheus metrics |
Full reference at /docs (FastAPI auto-generated OpenAPI).
Eval suite
Reproducible evaluation against a 50-query golden set covering all seed fixtures.
# Seed the eval corpus (idempotent).
python -m scripts.seed_eval

# Run the suite — resolves collection by name; writes JSON + Markdown.
python -m app.eval.runner run --markdown

# Compare runs.
python -m app.eval.runner diff \
  eval/results/<prev>.json eval/results/<curr>.json -o eval/results/diff.md
Metrics: accuracy, hallucination rate, retrieval precision@k, retrieval recall@k, latency avg/p50/p95, cost USD. Bucketed by difficulty and category.
Dataset: JSONL at eval/golden/queries.jsonl.
A/B: measure reranker + MMR lift
RERANKER_ENABLED=false MMR_ENABLED=false  python -m app.eval.runner run --markdown
pip install -e ".[rerank]"
RERANKER_ENABLED=true  MMR_ENABLED=true   python -m app.eval.runner run --markdown
python -m app.eval.runner diff <baseline>.json <reranked>.json -o eval/results/reranker-delta.md
The diff report shows per-metric deltas and per-item regressions.
Tests
pytest tests/ -q
# 58 passed
Layered: unit (tests/agent/ — nodes against FakeProvider + mocked retriever), service (tests/test_reranker.py, test_mmr.py, test_chunker.py).
Project layout
app/
  agent/          LangGraph agent (nodes, graph, state, prompts, utils)
  api/v1/         FastAPI routers — agent, query, documents, conversations,
                  notes, collections, eval, admin, webhooks, health, metrics
  services/       llm/ (providers + pricing), retriever, embedder, chunker,
                  reranker, mmr, retrieval_pipeline, ingestion, text_extractor,
                  rag, lang, whatsapp/, twilio_client
  models/         SQLAlchemy ORM
  schemas/        Pydantic
  eval/           Evaluation framework (runner, judge, evaluator, report, metrics)
alembic/          DB migrations
fixtures/seed-docs/   Curated corpus for the eval suite
frontend/         React + TanStack Router + shadcn/ui
tests/            Pytest
docs/adr/         Architecture Decision Records
License
MIT