
MCP ADS arXiv – Leitor de Papers Científicos
estevesjh/mcp-ads-arxiv
Leia papers científicos via LaTeX puro, não PDFs renderizados
Ver no GitHubServidor MCP que permite ao Claude ler artigos científicos diretamente do código-fonte LaTeX em vez de PDFs renderizados. Integra NASA ADS para busca e arXiv para download de arquivos .tex, evitando distorção de equações e economia massiva de tokens. Quando LaTeX não está disponível, converte PDF para markdown via docling.
Instalação
npx convez-ai estevesjh/mcp-ads-arxiv1 comando no terminal: detecta o formato do repositório (marketplace ou plugin avulso) e instala via Claude Code. Requer Node 18+ e o Claude Code instalado.
Métricas
Casos de uso
- Pesquisa acadêmica em astrofísica com busca inteligente em NASA ADS
- Extração de dados de artigos sem degradação de equações e tabelas
- Construção de bibliotecas locais de papers para reutilização
- Redução de consumo de tokens (~15x) comparado a upload direto de PDF
Veredito

Ferramenta especializada e bem arquitetada para pesquisadores que trabalham com literatura científica. Resolve um problema real (degradação de PDFs em IA) com engenharia sólida (LaTeX nativo, conversão inteligente, cache local). Nicho específico em astrofísica, mas padrão generalizável para outras ciências.
README
A tradução para o português deste README ainda está na fila.
mcp-ads-arxiv
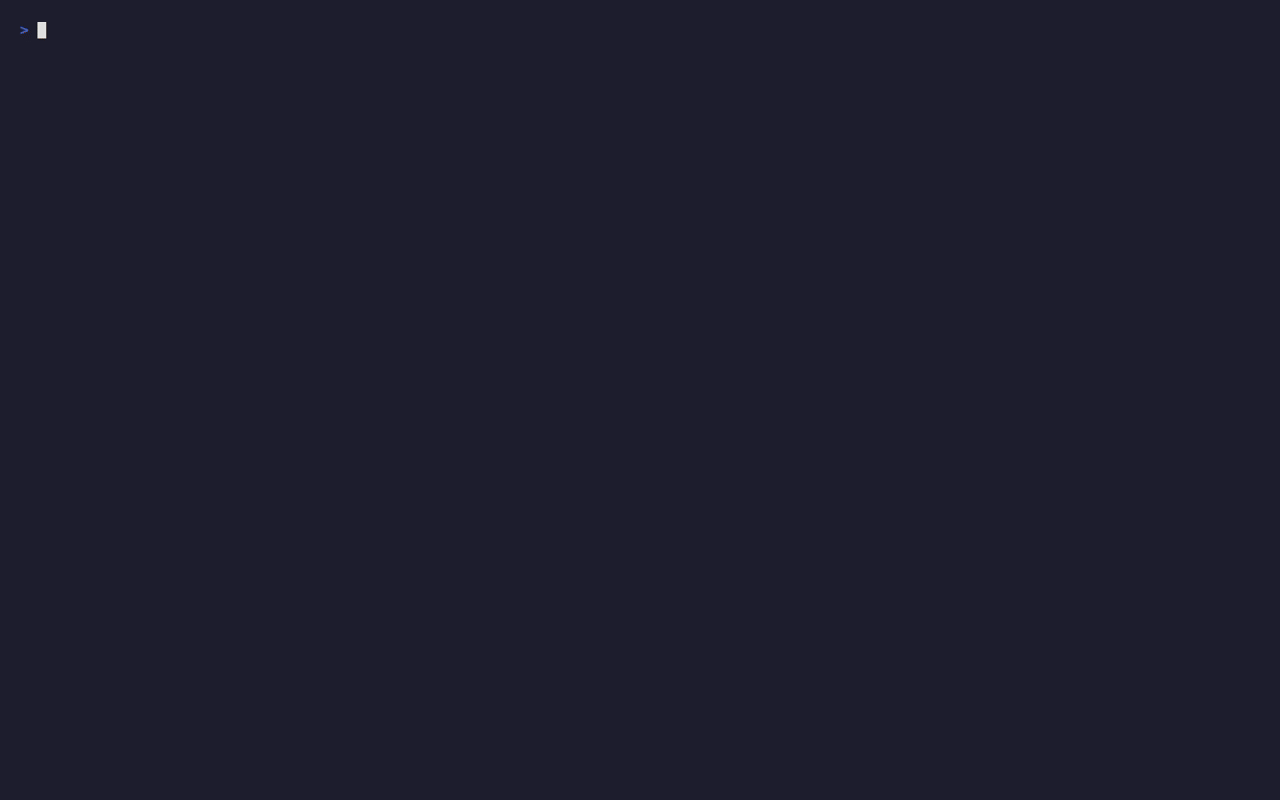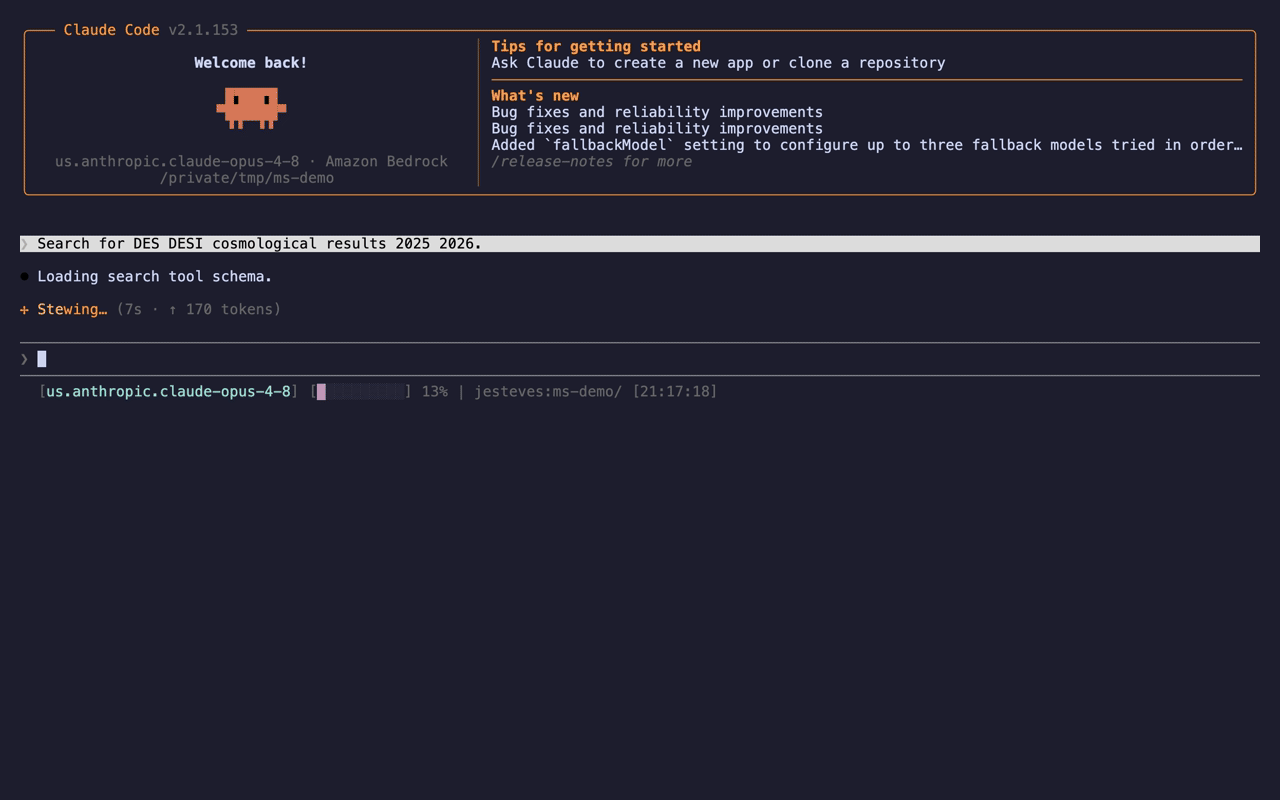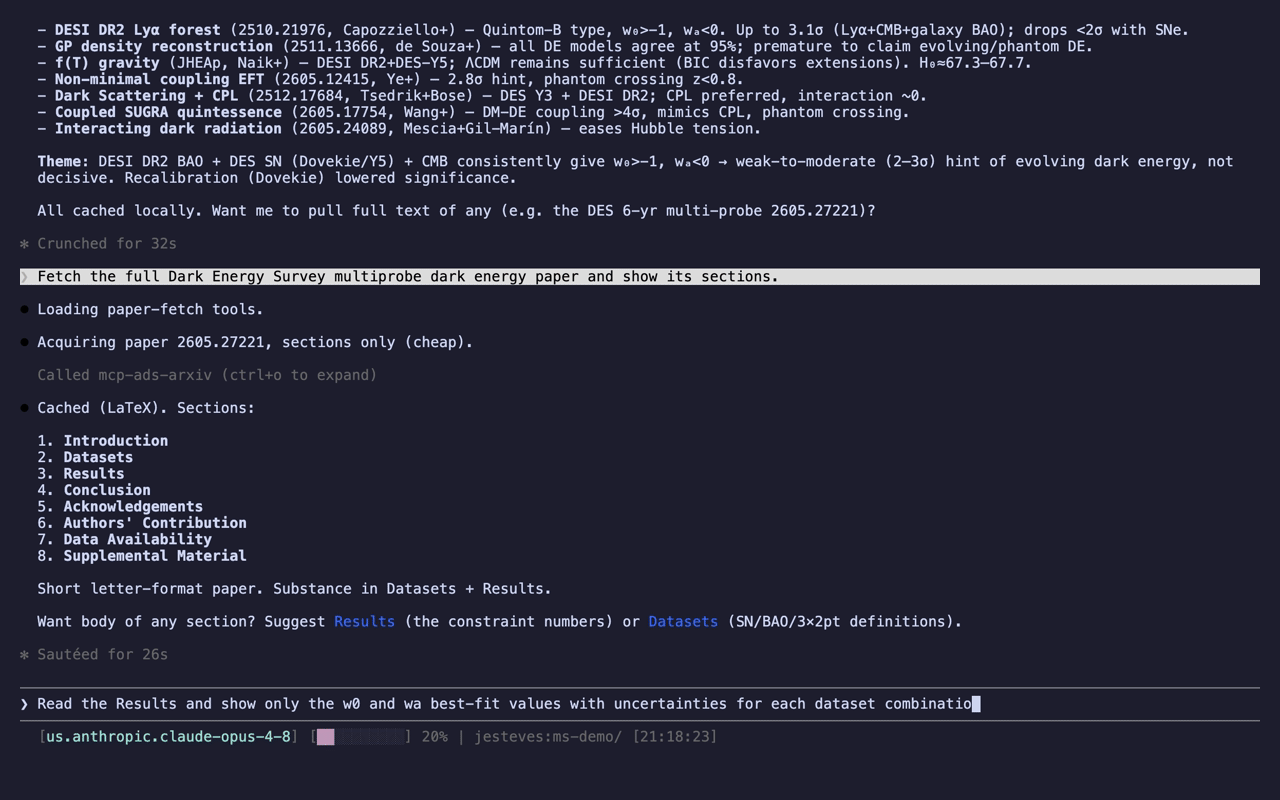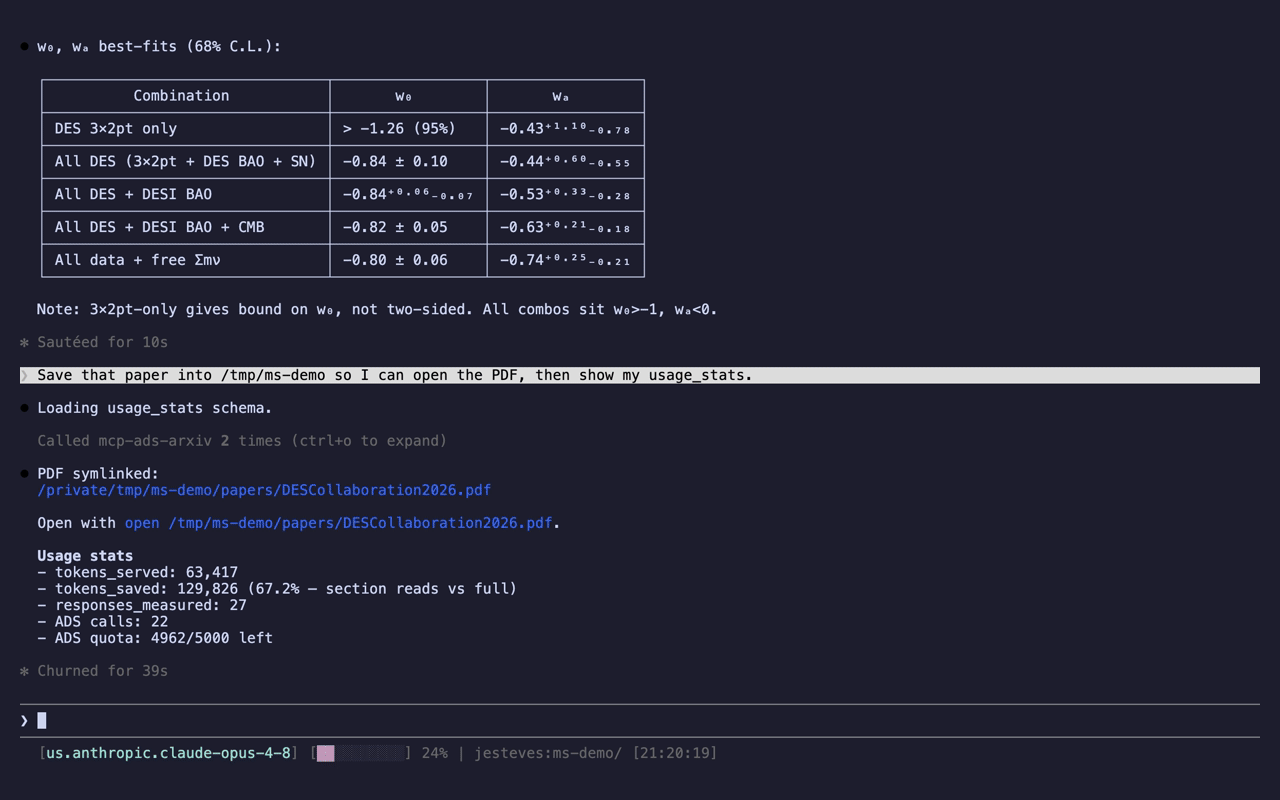 A real Claude Code session — search, fetch, extract w₀/wₐ constraints, save PDF. Idle frames trimmed.
An MCP server that makes Claude read scientific papers from their LaTeX source code instead
of PDFs. It searches NASA ADS and downloads the original
.tex files from arXiv — plain text that AI can read perfectly.
The problem with PDFs: when you upload a PDF to an AI, it doesn't read text — it processes
a rendered image. Equations get garbled (w₀ becomes wo or w0), table values shift
columns, and you burn tokens on figures, headers, and page numbers the AI can't even use.
The fix: read the LaTeX source directly. Equations stay as $w_0 = -0.82 \pm 0.05$,
tables keep their structure, and you only read the section you actually need — not all 40
pages.
Why not just upload a PDF?
| Approach | Tokens | Quality |
|---|---|---|
| Upload PDF to ChatGPT/Claude | ~50,000 (full document) | Image-based rendering, broken equations, shifted table values |
| This tool: read one section | ~3,000 (just what you asked) | Clean LaTeX plain text, exact $w_0$, proper tables |
| This tool: metadata only | ~500 (title + abstract + authors) | No file read at all |
~15x fewer tokens per query. You never pay for the 35 pages you didn't need. When no LaTeX source exists on arXiv, the PDF is converted to markdown via docling (still cleaner than raw PDF upload).
What it does
- ADS Search Execute native searches on ADS exactly like the web interface (metadata-only: title, abstract, keywords, authors, year).
- Local Library Locally stores all acquired paper
.texfiles to prevent redundant network downloads. - Pre-Flight Survey Perform a top-level sweep on ADS for a topic. The tool clusters results into 4 interested topics and 4 excluded topics to align on scope before any full text is ingested.
- Intelligent Acquisition Fetches arXiv .tex sources. If unavailable, it pulls the PDF to look for an inbox/ drop. read_paper subsequently serves the parsed text, optionally targeting a user-specified subset of sections.
Talking to the tool: prompt cookbook
You don't call these tools yourself — you ask Claude in plain English, and the directives in
CLAUDE.md route the request. The phrasings below are battle-tested; copy them, adapt the
identifier/topic, and Claude will pick the right tool path.
Discover papers
- "Search for Esteves 2023 tree rings." — natural academic notation, just works.
- "Find papers on galaxy cluster mass calibration with weak lensing, last 5 years."
- "Look for papers I already have on [topic] before going to the network." — forces local-first.
Acquire a paper into the library
- "Get paper 2023PASP..135k5003E." (ADS bibcode)
- "Acquire arXiv 2308.00919 into the library."
- "Download Esteves et al. 2023 PASP photometry paper." — Claude resolves via ADS first.
- "Get a PDF I can read for [paper]." — runs
fetch_pdffor human reading too.
Save papers to this project folder
By default, every paper goes to one global library so search stays unified. To also drop a shortcut into the current project folder, tell the server which folder is "this project":
- "Set the project directory to the current folder." — call once at the start of a session;
Claude should pass its
cwdtoset_project_dir. - "Use
/abs/path/to/myprojectas my project folder for this session."
After that, every smart_fetch_paper_content automatically creates two symlinks under <project>/papers/:
<bibcode>/→ the source directory in the global library<FirstAuthorLastNameYear>.pdf→ the PDF for human reading (e.g.Esteves2023.pdf)
The originals stay in the global library — no data duplication.
- "Show me what's been linked into this project." →
library_status - "Stop tracking [paper] in this project." →
unlink_paper(the global copy stays)
Read a paper without burning tokens
For natural-language asks, one tool call is enough — read_topic resolves the topic to
the right section(s) automatically (fuzzy match on LaTeX macros, whitespace, and case):
- "Summarize the methodology of 2010ApJ...720.1038B." — one call to
read_topic. - "Show me the Tree-rings section of 2023PASP..135k5003E."
- "What does the discussion of [paper] say?"
When you already know the exact labels, or want multiple specific sections:
- "Read just the Application and Discussion sections of [paper]." →
read_paper(sections=[...]) - "List the section headings of [paper]." →
list_sections - "Read the full text of [paper]." — only when you really need it.
Pre-flight survey (the token-saving habit)
When a search returns more than a handful of papers, ask Claude to survey first:
- "Search ADS for [topic], then run the pre-flight survey on the results."
- "Cluster these papers into focus and exclude topics so I can pick a scope."
Claude returns 4 focus + 4 exclude options and waits. Reply with your scope, and only then will it acquire/read the chosen subset.
PDF-only papers
If arXiv has no LaTeX source, smart_fetch_paper_content downloads the PDF and runs docling to produce a
markdown copy. Claude reads the markdown, never the raw PDF.
- "Acquire [closed-access bibcode]; if you can't auto-download, tell me where to drop the PDF."
- After dropping a PDF in
inbox/: "Ingest the inbox." →ingest_inbox
Inspect usage and saved tokens
- "What's my ADS quota and how many tokens has the library served?" →
usage_stats - "How much was saved by reading sections instead of full papers?"
Phrasing matters: "citations" vs "references"
NASA ADS (and related_papers) splits the citation graph into two opposite directions:
references— the papers this paper cites (its bibliography; backward; the foundations).citations— the papers that cite this paper (forward; the impact / what came after).
Everyday English mixes them up, so when prompting be explicit. Examples:
To get the paper's bibliography (references) on a topic
| Say this | What runs |
|---|---|
| "What does 2010ApJ...720.1038B cite about the halo model?" | mode="references", topic="halo model" |
| "Methodology references in 2010ApJ...720.1038B for the gas density profile." | mode="references", topic="gas density" |
| "What is this paper built on for its mass profile?" | mode="references", topic="mass profile" |
To get works that cited this paper (forward citations) on a topic
| Say this | What runs |
|---|---|
| "What papers cite 2010ApJ...720.1038B about density profiles?" | mode="citations", topic="density profile" |
| "Who built on this paper for gas density work?" | mode="citations", topic="gas density" |
| "What came after 2010ApJ...720.1038B on cluster mass profiles?" | mode="citations", topic="cluster mass" |
| "Forward citations of this paper, filtered by ICM thermodynamics." | mode="citations", topic="ICM" |
Avoid (ambiguous — triggers a clarifying question)
- "the citations of this paper" — could mean either direction
- "its citations" — same problem
- "citing papers" — slightly forward-leaning, but still ask to be safe
Topically adjacent (no direct graph edge)
- "Papers similar to 2010ApJ...720.1038B" →
mode="similar"
Tools
| Tool | Purpose |
|---|---|
search_library | Local, free search over already-acquired papers (title, abstract, and authors). |
flexible_paper_search | Human-friendly search (Esteves 2023 tree rings). ADS when token set; arXiv API fallback. |
related_papers | Citation graph: references / citations / similar, optional topic. |
generate_dynamic_survey | Cluster metadata into 4 focus + 4 exclude topics. |
smart_fetch_paper_content | One-call acquire + summarize: arXiv .tex → PDF→md → returns sections + abstract, no body. |
read_paper | Serve stored text; optional sections to save tokens. |
list_sections | Cheap heading list + abstract (a few hundred tokens). |
read_topic | One-shot "show me the methodology / results / [section]" with fuzzy match. |
ingest_inbox | Convert PDFs dropped in inbox/ to markdown. |
Setup
Requires Python 3.11+.
Option A: Homebrew (macOS, recommended)
brew tap estevesjh/mcp
brew install mcp-ads-arxiv
Option B: using pip
git clone https://github.com/estevesjh/mcp-ads-arxiv.git
cd mcp-ads-arxiv
pip install -e .
Option C: using conda + pip
conda create -n mcp-arxiv python=3.11
conda activate mcp-arxiv
git clone https://github.com/estevesjh/mcp-ads-arxiv.git
cd mcp-ads-arxiv
pip install -e .
Option D: using uv (fastest)
uv is a modern Python package manager — installs in seconds, no virtualenv management needed:
curl -LsSf https://astral.sh/uv/install.sh | sh   # one-time install
git clone https://github.com/estevesjh/mcp-ads-arxiv.git
cd mcp-ads-arxiv
uv sync
Optional: PDF conversion support
Most arXiv papers have LaTeX source and don't need this. For PDF-only papers
(no .tex on arXiv), install docling:
pip install 'mcp-ads-arxiv[pdf]'
This adds ~1GB (includes torch). Skip it if you only work with arXiv preprints.
Get an ADS API token
- Create a free account at NASA ADS.
- Go to Settings → API Token.
- Generate a key and copy it. The server reads it from
ADS_API_TOKEN.
Without a token the server still runs — it prints a startup notice to stderr and falls back to the free arXiv API for discovery. Citation graphs require a token.
Library location
By default the library lives in the current working directory. Set LIT_CACHE_DIR to put it
anywhere (e.g. a shared research folder). See .env.example.
Register with Claude
First, set your environment variables (add these to your ~/.bashrc or ~/.zshrc):
export ADS_API_TOKEN="your-token-here"
export LIT_CACHE_DIR="/path/to/your/paper/library"
export MCP_ADS_ARXIV_DIR="/path/to/mcp-ads-arxiv"   # where you cloned the repo
Claude Code
claude mcp add --scope user mcp-ads-arxiv \
  -e ADS_API_TOKEN=$ADS_API_TOKEN \
  -e LIT_CACHE_DIR=$LIT_CACHE_DIR \
  -- mcp-ads-arxiv
# If you installed with uv (Option C) instead of pip, replace the last line with:
#   -- uv run --directory $MCP_ADS_ARXIV_DIR mcp-ads-arxiv
Claude Desktop
Add to your Claude Desktop config (~/Library/Application Support/Claude/claude_desktop_config.json on macOS):
{
  "mcpServers": {
    "mcp-ads-arxiv": {
      "command": "uv",
      "args": ["run", "--directory", "/path/to/mcp-ads-arxiv", "mcp-ads-arxiv"],
      "env": {
        "ADS_API_TOKEN": "your-token-here",
        "LIT_CACHE_DIR": "/path/to/your/paper/library"
      }
    }
  }
}
Restart the client afterwards.
Skip the per-call permission prompts (Claude Code only)
By default Claude Code asks for approval the first time each tool is used. To pre-approve all 8
tools from this server, add one entry to ~/.claude/settings.json:
{
  "permissions": {
    "allow": ["mcp__mcp-ads-arxiv"]
  }
}
The mcp__<server-name> prefix matches every tool the server exposes. Merge with any existing
allow array — don't replace it. Restart Claude Code to pick up the change.
Development
uv run pytest          # pure-logic tests (no network/token needed)
uv run mcp-ads-arxiv   # boots the stdio server
Acknowledgments
This project builds directly on two excellent upstream MCP projects and depends on them rather than reimplementing their work:
- cbyrohl/mcp-server-ads — its
ADSClient(HTTP, auth, rate-limit tracking, typed errors) backs all NASA ADS access here. - takashiishida/arxiv-latex-mcp and the
underlying arxiv-to-prompt library —
arXiv source download,
\input/\includeflattening, and section listing/extraction.
PDF→markdown conversion uses docling (IBM).
License
MIT