
VoxKitchen
XqFeng-Josie/VoxKitchen
Pipeline YAML para preparar dados de áudio e fala para ASR/TTS
Ver no GitHubKit declarativo para processamento de dados de fala que transforma gravações brutas em datasets prontos para treinamento via pipelines YAML. Integra 52 operadores para conversão, segmentação, limpeza, diarização e filtragem de áudio, executando tudo em containers Docker isolados.
Instalação
npx convez-ai XqFeng-Josie/VoxKitchen1 comando no terminal: detecta o formato do repositório (marketplace ou plugin avulso) e instala via Claude Code. Requer Node 18+ e o Claude Code instalado.
Métricas
Casos de uso
- Preparar datasets de treinamento para modelos ASR (reconhecimento de fala)
- Processar e inspecionar dados de TTS (síntese de fala)
- Diarização de falantes, detecção de idioma e métricas de qualidade de áudio
- Limpeza, filtragem e empacotamento de áudio em escala sem scripts customizados
Veredito

Ferramenta madura e bem-arquitetada para quem precisa processar grandes volumes de dados de áudio de forma reproduzível. Docker-first e resumável por design, elimina scripts frágeis, mas exige familiaridade com pipelines declarativos e stack de áudio.
README
A tradução para o português deste README ainda está na fila.
Use VoxKitchen when you want to:
- turn long recordings into ASR training data;
- prepare and inspect TTS datasets;
- diarize speakers, tag languages, or run speech quality checks;
- clean, filter, and package audio without maintaining one-off scripts.
Why VoxKitchen
Speech data preparation is usually a chain of fragile scripts: convert audio, split speech, denoise, transcribe, diarize, filter, and export. VoxKitchen makes that chain explicit and repeatable:
- Docker-first execution: prebuilt runtimes avoid local dependency conflicts.
- One YAML pipeline: define ingest, stages, filters, and output packs in one file.
- 52 built-in operators: audio prep, VAD, ASR, diarization, TTS, quality metrics, and packing.
- Resumable by design: every stage checkpoints under
./work. - Inspectable outputs: reports, cut statistics, provenance, and per-stage errors.
Quick Start
Requirements:
- Docker
- Python 3.10+ for the lightweight
vkitlauncher
Install the vkit launcher from PyPI:
pipx install voxkitchen      # recommended — isolates the launcher
# or
pip install voxkitchen
This installs only the lightweight launcher and inspection commands (a few MB, no torch / ASR / TTS dependencies). All pipeline runtime dependencies stay inside the prebuilt Docker images.
Run the included demo with the smallest runtime image. No repository clone is required; the published image includes the demo pipeline and demo audio.
vkit docker pull --tag slim
vkit docker run --tag slim examples/pipelines/demo-no-asr.yaml
vkit inspect run ./work/demo-no-asr
$ vkit docker run --tag slim examples/pipelines/demo-no-asr.yaml
06:20:54  stage [1/9] to_wav  (ffmpeg_convert, 1 cuts in, env=core)
06:20:55  stage [1/9] to_wav  done → 1 cuts out (0.3s)
06:20:55  stage [2/9] vad  (silero_vad, 1 cuts in, env=core)
06:21:08  stage [2/9] vad  done → 7 cuts out (13.2s)
06:21:08  stage [3/9] extract  (ffmpeg_convert, 7 cuts in, env=core)
06:21:08  stage [3/9] extract  done → 7 cuts out (0.6s)
06:21:08  stage [4/9] snr  (snr_estimate, 7 cuts in, env=core)
06:21:08  stage [4/9] snr  done → 7 cuts out (0.0s)
06:21:08  stage [5/9] pitch  (pitch_stats, 7 cuts in, env=core)
06:21:11  stage [5/9] pitch  done → 7 cuts out (2.3s)
06:21:11  stage [6/9] clipping  (clipping_detect, 7 cuts in, env=core)
06:21:11  stage [6/9] clipping  done → 7 cuts out (0.0s)
06:21:11  stage [7/9] gender  (gender_classify, 7 cuts in, env=core)
06:21:44  stage [7/9] gender  done → 7 cuts out (33.2s)
06:21:44  stage [8/9] filter  (quality_score_filter, 7 cuts in, env=core)
06:21:44  stage [8/9] filter  done → 7 cuts out (0.0s)
06:21:44  stage [9/9] pack  (pack_jsonl, 7 cuts in, env=core)
06:21:44  stage [9/9] pack  done → 7 cuts out (0.0s)
06:21:44  report generated: work/demo-no-asr/report.html
pipeline complete
  work_dir: work/demo-no-asr
  final cuts: work/demo-no-asr/08_pack/cuts.jsonl.gz
  report: work/demo-no-asr/report.html

$ vkit inspect run ./work/demo-no-asr
Pipeline run: demo-no-asr
  00_to_wav: OK (1 cuts)  0.3s, 4 cuts/s
  01_vad: OK (7 cuts)  13.2s, 1 cuts/s
  02_extract: OK (7 cuts)  0.6s, 11 cuts/s
  03_snr: OK (7 cuts)  0.0s, 310 cuts/s
  04_pitch: OK (7 cuts)  2.3s, 3 cuts/s
  05_clipping: OK (7 cuts)  0.0s, 381 cuts/s
  06_gender: OK (7 cuts)  33.2s, 0 cuts/s
  07_filter: OK (7 cuts)  0.0s, 8124 cuts/s
  08_pack: OK (7 cuts)  0.0s, 6638 cuts/s
vkit docker run writes run artifacts under ./work and exported datasets
under ./output with your host user ID. It also mounts ./data automatically
when that directory exists.
What You Can Build
| Goal | Start with | Runtime image |
|---|---|---|
| Clean and filter raw speech audio | vkit init my-cleaning --template cleaning | slim |
| Build ASR training manifests | vkit init my-asr --template asr | asr |
| Analyze speakers and languages | vkit init my-speakers --template speaker | latest |
| Prepare TTS training data (quality gate) | vkit init my-tts --template tts | asr |
| Synthesize speech in a built-in voice | see Speaker TTS tutorial | tts |
| Clone a voice from a 3–10 s reference | see Voice Cloning & TTS tutorial | tts or fish-speech |
How It Works
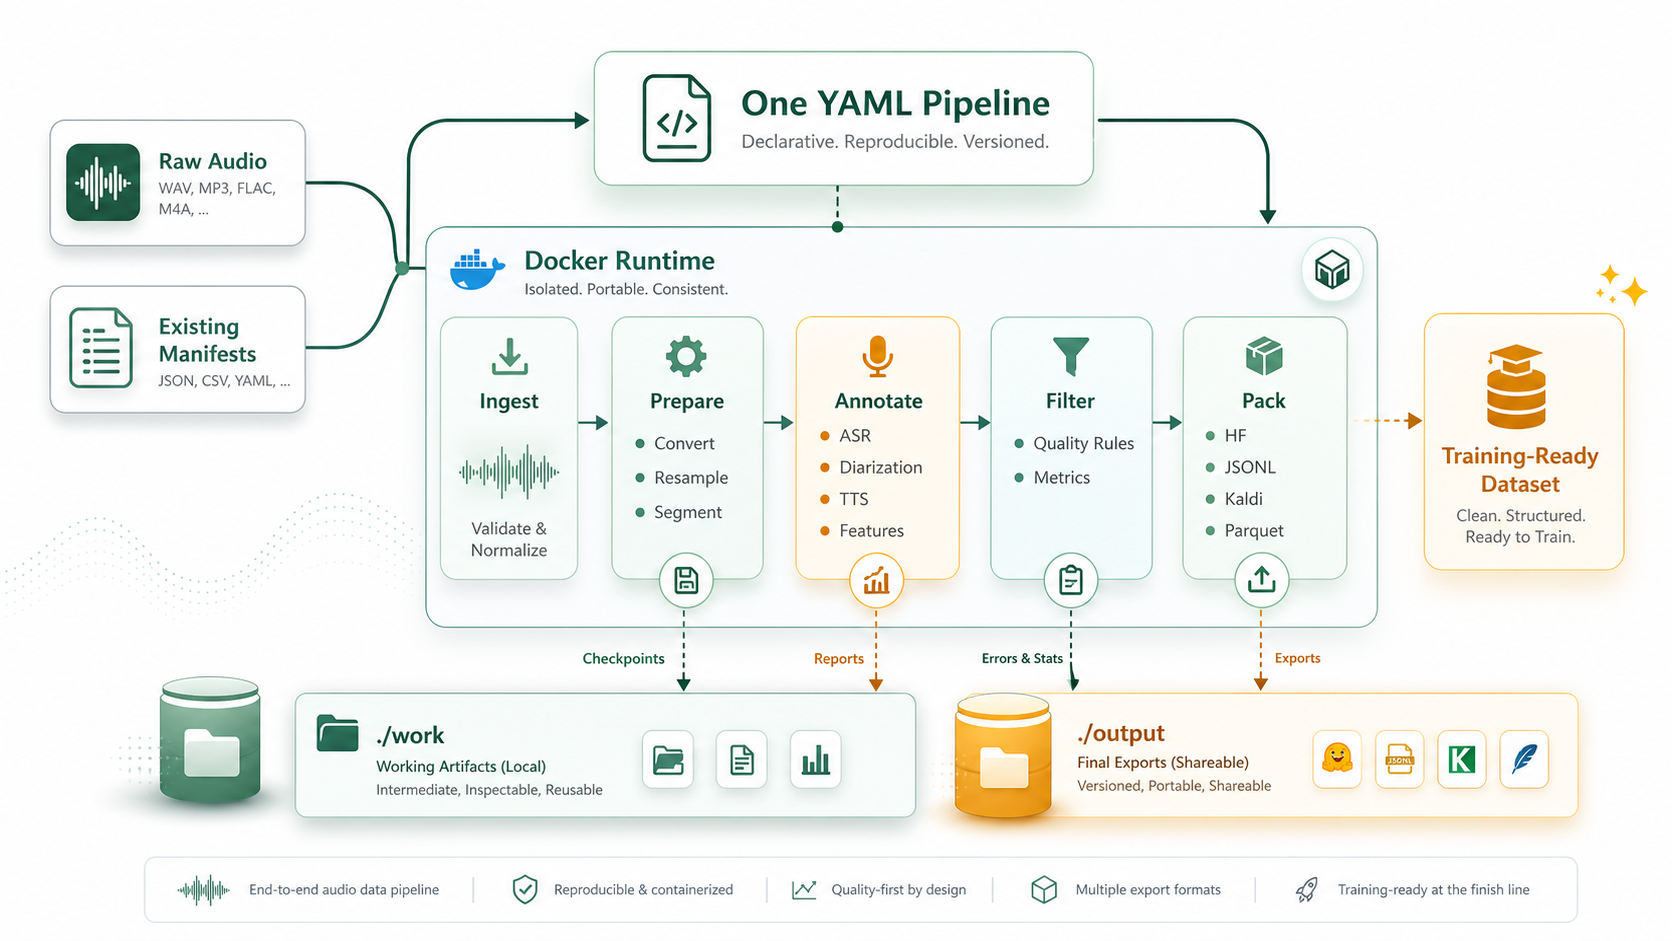
A pipeline is a YAML file. Each stage reads a CutSet, writes a checkpoint,
and passes the result to the next stage.
version: "0.1"
name: my-pipeline
work_dir: ./work/${name}-${run_id}

ingest:
  source: dir
  args:
    root: ./data
    recursive: true

stages:
  - name: resample
    op: resample
    args: { target_sr: 16000, target_channels: 1 }

  - name: vad
    op: silero_vad
    args: { threshold: 0.5 }

  - name: asr
    op: faster_whisper_asr
    args: { model: large-v3, compute_type: float16 }

  - name: filter
    op: quality_score_filter
    args:
      conditions: ["duration > 1", "duration < 30", "metrics.snr > 10"]

  - name: pack
    op: pack_jsonl
Interrupted runs resume from completed checkpoints.
Create A Project
vkit init my-project --template asr
cd my-project

# Put your audio files in ./data first.
vkit validate pipeline.yaml
vkit docker run --tag asr pipeline.yaml --dry-run
vkit docker run --tag asr pipeline.yaml
vkit inspect run work/
List templates:
vkit init --list-templates
Not sure which image a pipeline needs? Run:
vkit validate pipeline.yaml
It prints the recommended vkit docker pull --tag ... and
vkit docker run --tag ... commands for that YAML.
Runtime Images
Every vkit docker command accepts --tag <name>:
| Tag | Use when | GPU | Approx. size |
|---|---|---|---|
slim | CPU-friendly cleaning, VAD, quality, pack, enhancement | no | ~22 GB |
asr | Faster-Whisper, FunASR, Qwen3-ASR, forced alignment | yes | ~36 GB |
diarize | Pyannote speaker diarization | yes | ~20 GB |
tts | Kokoro, ChatTTS, CosyVoice | yes | ~46 GB |
fish-speech | Fish-Speech isolated runtime | yes | ~58 GB |
latest | Mixed pipelines across ASR, diarization, TTS, or Fish-Speech | yes | ~88 GB |
Use latest when one pipeline mixes multiple runtime families, such as ASR
plus diarization or ASR plus TTS. Otherwise, prefer the smallest image that
contains the operators you need.
Useful checks:
vkit docker pull --tag asr
vkit docker doctor --tag asr --expect asr
vkit docker doctor --tag latest
Configuration
Some operators require API tokens. Create ./.env; vkit docker run passes it
into the container automatically.
cp .env.example .env
| Variable | Required by | Notes |
|---|---|---|
HF_TOKEN | pyannote_diarize | Accept the pyannote model agreement on HuggingFace first. |
Common Commands
vkit init <path> --template asr           # Scaffold a project
vkit validate pipeline.yaml               # Validate YAML and recommend an image
vkit docker run --tag asr pipeline.yaml --dry-run
vkit docker run --tag asr pipeline.yaml
vkit inspect run work/                    # Stage summary
vkit inspect cuts <cuts.jsonl.gz>          # CutSet statistics
vkit inspect errors work/                  # Per-stage failed cuts
vkit operators search <keyword>            # Find operators by name or summary
vkit operators --category quality          # List one category's operators
vkit schema export --out pipeline.schema.json  # Editor autocompletion for YAML
vkit recipes                               # List dataset recipes
vkit docker download --tag slim librispeech --root ./data/librispeech --subsets dev-clean
vkit docker doctor --tag latest            # Check image health
Documentation
- Getting Started
- Examples & Use Cases
- Pipeline YAML
- Dataset Catalog
- CLI reference
- Operators reference
- Docker build guide
- Contributing
Agent Skill
The repo includes an agent-neutral VoxKitchen skill at skill/. Claude,
Codex, and other SKILL.md-compatible agents can copy, symlink, or import that
folder into their own skill search path. The skill follows the Docker-first
vkit workflow in this README.
Citation
If you use VoxKitchen in your research, please cite it. The repository ships
CITATION.cff,
which GitHub renders under "Cite this repository".
License
Apache 2.0. See LICENSE.