
NextRole — Acelerador de Carreira com IA
tam159/next-role
Automatize CV, pesquisa e prep de entrevista em minutos com agentes IA
Ver no GitHubMCP Server que automatiza preparação de entrevistas de emprego usando múltiplos agentes IA. Transforma seu CV e job description em resume tailorizado, pesquisa de empresa, plano de prep estruturado e battlcard para o dia da entrevista. Integra LangGraph, LangChain e web research para iteração contínua.
Instalação
npx convez-ai tam159/next-role1 comando no terminal: detecta o formato do repositório (marketplace ou plugin avulso) e instala via Claude Code. Requer Node 18+ e o Claude Code instalado.
Métricas
Casos de uso
- Candidatos ajustando CV para posições específicas em 30 min vs 3 horas
- Profissionais em transição pesquisando automáticamente cultura e tecnologia da empresa
- Candidatos internos preparando argumentos para promoção com dados estruturados
- Equipes de recrutamento gerando análises de fit candidato-vaga
Veredito

Ferramenta sólida e bem-engineered para automação end-to-end de entrevistas, com agentes especializados e workspace integrado. Recomendada para profissionais técnicos que fazem entrevistas frequentes ou equipes que processam alto volume de candidatos; exige setup Docker e chaves de API.
README
A tradução para o português deste README ainda está na fila.
NextRole 🚀
✨ GenAI-Accelerated Career Advancement ✨
Upload your CV + a job description. Get a tailored resume PDF, a researched interview-prep doc, and a day-of battlecard cheat sheet — built by a multi-agent system with long-term memory.


What is NextRole?
Preparing for an interview takes hours of tedious resume tailoring and company research. NextRole automates the heavy lifting. Hand it your current CV and a target Job Description (or just a JD URL) — whether you're applying externally or angling for an internal move — and a team of specialized AI agents researches the company, rewrites your resume to fit, coaches you round-by-round, and prints a cheat sheet for the day of.
- 📄 Tailored resume → PDF — your experience rewritten against the exact JD + company research, rendered with
rendercv(editable & re-renderable). - 🔍 Deep company & role recon — live web research distilled into a match analysis.
- 🎯 Structured interview prep — a self-introduction plus per-round STAR stories mapped to the role.
- ⚡ Day-of battlecard — a one-page-per-round PDF cheat sheet for the final high-pressure review.
- 🗓️ Time-boxed prep plans — a study plan that fits 1 month, 2 weeks, or just 3 hours.
- 🔗 Paste a JD URL — point it at a careers page; it extracts and processes the posting for you.
- 💬 Iterate by chatting — "add a 4th round", "add React to my skills" — streaming multi-turn edits, with the right agent owning each file.
- 🗂️ Built-in workspace — upload, preview (PDF / MD / YAML / JSON / code), print-to-PDF, and swap the LLM at runtime.
Demo
▶️ Watch the full walkthrough in HD on YouTube »
Quick Start
The whole stack — frontend, backend, Postgres, Redis — runs in Docker.
# 1. Clone & configure
git clone https://github.com/tam159/next-role.git
cd next-role
cp .env.example .env          # then fill in your API keys (see table below)

# 2. Launch everything
docker compose up -d

# 3. Find your host ports (set in .env, vary per machine)
docker ps                     # read the 0.0.0.0:<host>->... mappings

# 4. Open the app
#    Frontend UI      →  http://localhost:<FRONTEND_LOCAL_PORT>/
#    Backend API docs →  http://localhost:<LANGGRAPH_LOCAL_PORT>/docs
💡 Pick your LLM in the app. Open the in-app Configuration dialog to set the main agent and subagent models — no rebuild needed. See LLM configuration below for recommended models and free / local options.
| Variable | Required | Purpose |
|---|---|---|
OPENAI_API_KEY | ✅ | Default main + subagent models |
TAVILY_API_KEY | ✅ | Web research (hiring-recon) |
LLAMA_CLOUD_API_KEY | ✅ | Document parsing (LlamaParse) |
POSTGRES_PASSWORD | ✅ | Local Postgres password |
ANTHROPIC_API_KEY / GOOGLE_API_KEY | ⬜ | Alternative providers (swap at runtime) |
OPENAI_API_BASE | ⬜ | Self-hosted / Azure / LM Studio endpoint |
AWS_ACCESS_KEY_ID / AWS_SECRET_ACCESS_KEY / AWS_DEFAULT_REGION | ⬜ | AWS Bedrock models |
LANGCHAIN_API_KEY + LANGCHAIN_TRACING_V2=true | ⬜ | LangSmith tracing (recommended) |
FRONTEND_LOCAL_PORT / LANGGRAPH_LOCAL_PORT / POSTGRES_LOCAL_PORT / REDIS_LOCAL_PORT | preset | Host port mappings |
Secrets live only in .env (gitignored); gitleaks runs on every commit.
Models are swappable at runtime — no rebuild. Open the in-app Configuration dialog and set Main agent / Subagents to a <provider>:<model> string (e.g. anthropic:claude-sonnet-4.6); leave blank to use the defaults. Settings persist in your browser's local storage.
Recommended: Claude Sonnet 4.x, GPT-5.x, or Gemini 3.x — e.g. anthropic:claude-sonnet-4.6, openai:gpt-5.4, google_genai:gemini-3.5-flash.
Run it for free or fully local:
- Tavily and LlamaCloud both include a generous monthly free tier — plenty for local use.
- Google AI Studio offers a free tier for Gemini
flash/litemodels. - Fully local — point
OPENAI_API_BASEat LM Studio or Ollama (both expose an OpenAI-compatible API) and fill your local model in the UI.
Output quality tracks the model you pick — smaller local models trade some quality for zero cost.
- Code edits hot-reload in both containers — just save the file.
- Add a frontend dep:
pnpm --dir frontend add <pkg>→docker compose restart frontend - Add a backend dep:
uv add <pkg>→docker compose up -d --build backend - Change
.env:docker compose restart <service> - Stop:
docker compose down(add-vto wipe the DB & Redis volumes)
Architecture
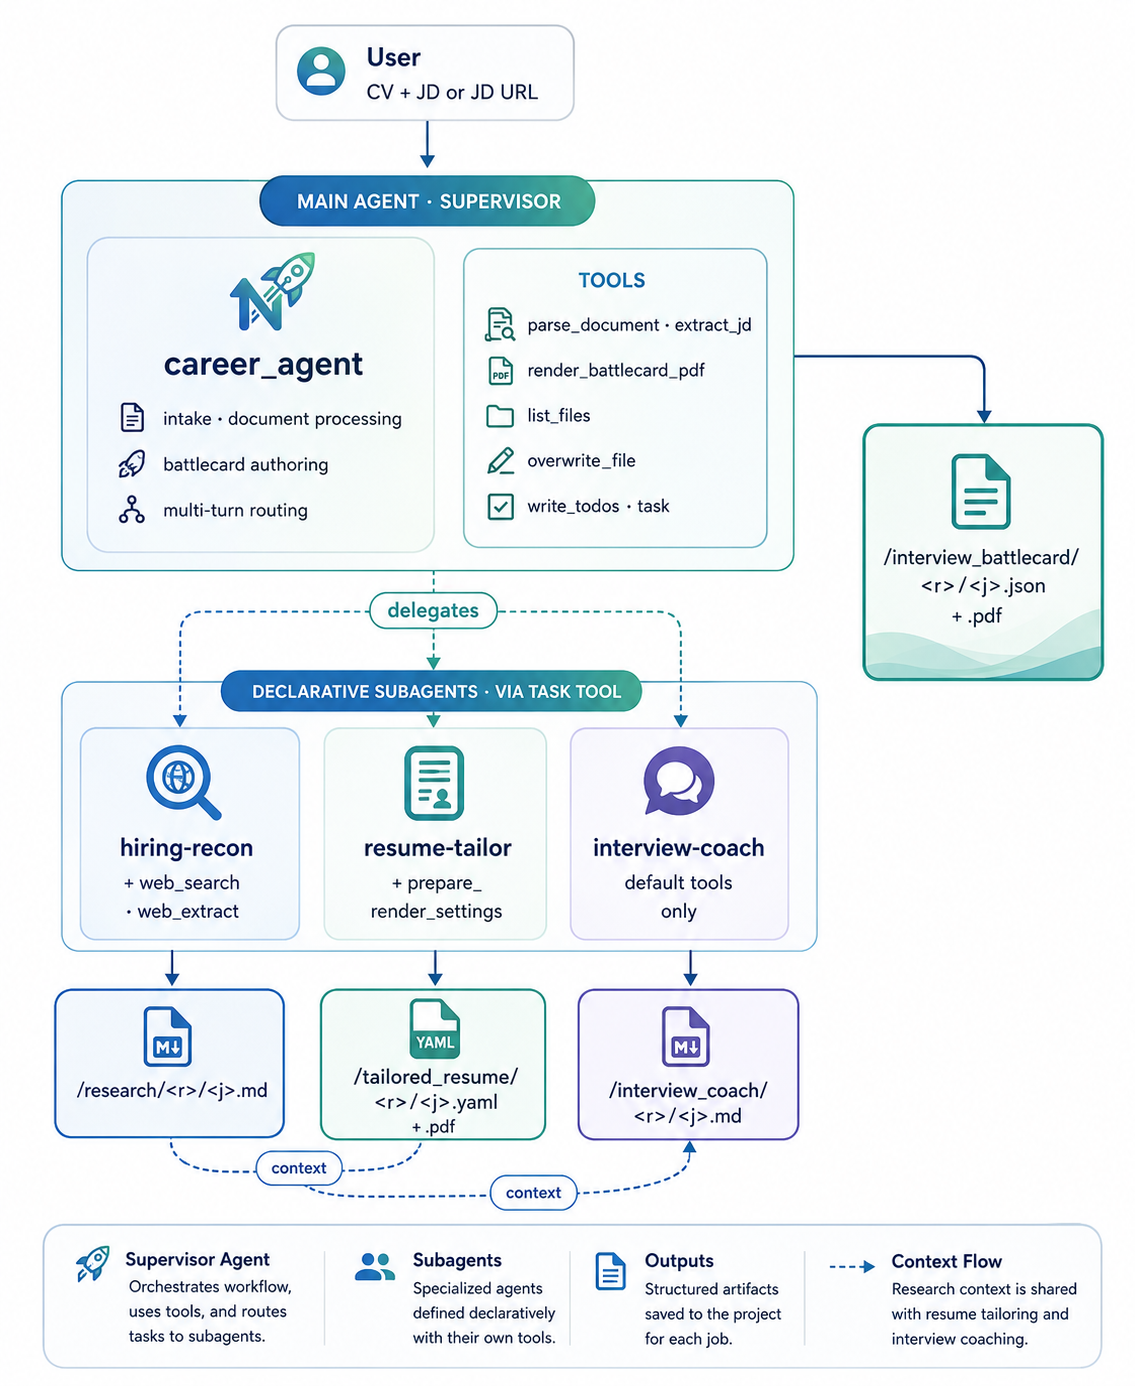
NextRole is a supervisor agent orchestrating three specialist subagents on LangGraph + DeepAgents. The main agent handles intake, document processing, and the final battlecard; it delegates research, resume tailoring, and interview coaching to declarative subagents (defined in subagents.yaml, each with its own model, tools, and skills).
How It Works
A five-stage pipeline. Stage 4 runs the resume tailor and interview coach in parallel; Stage 6 routes follow-up edits to whichever agent owns the target file.
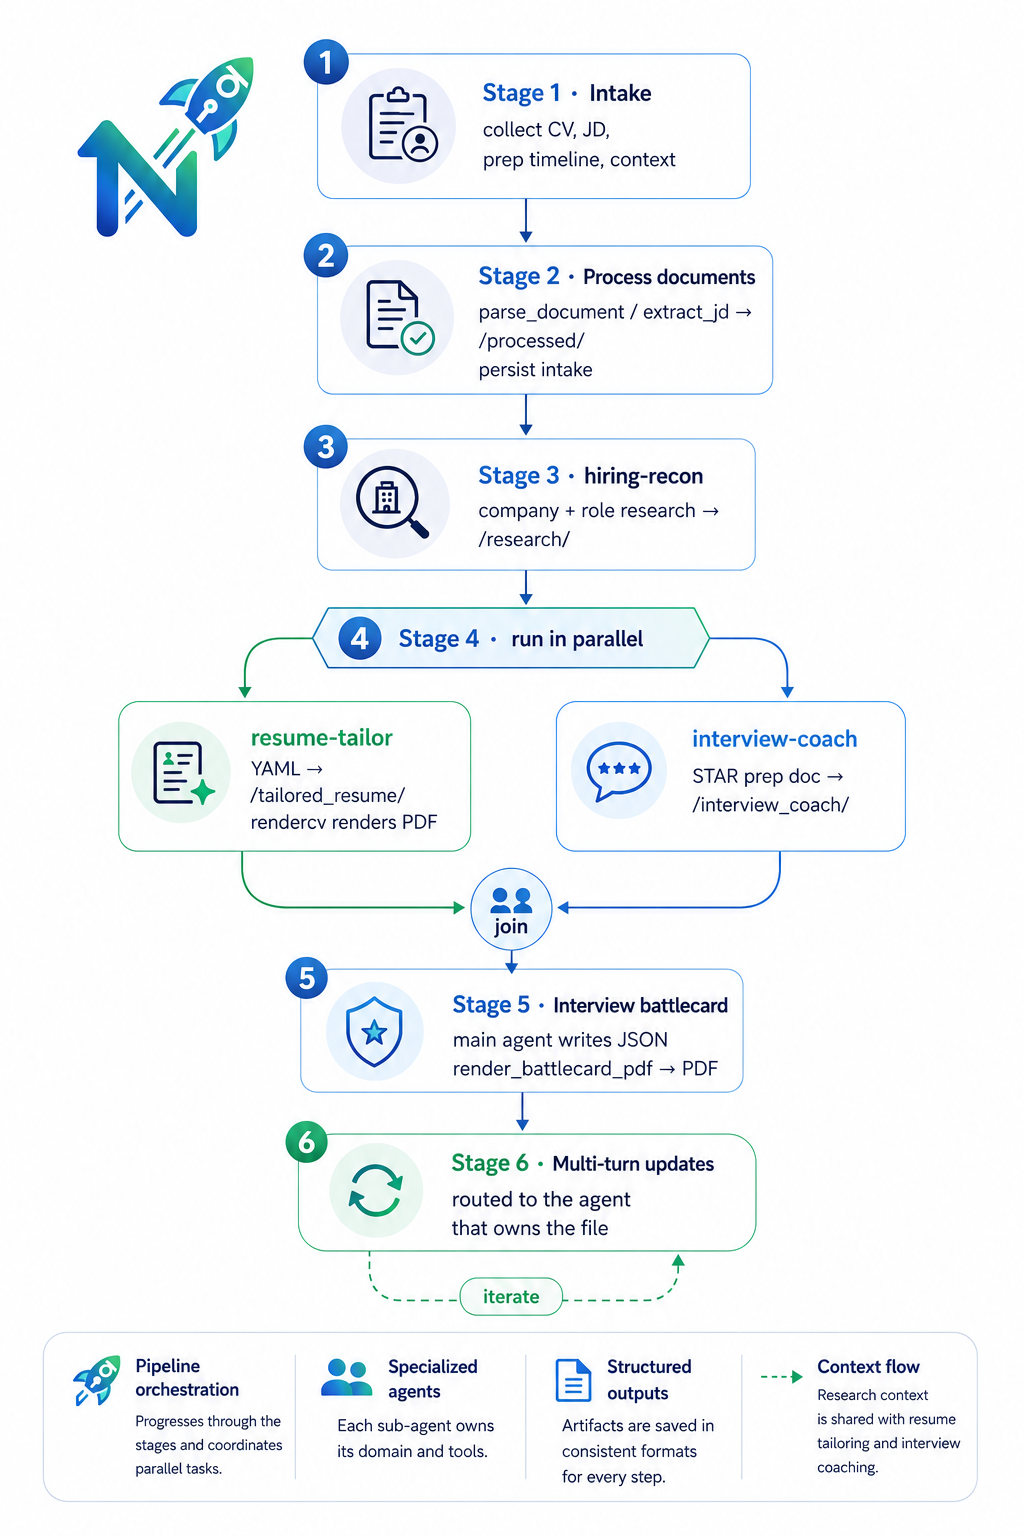
- Intake — the agent asks for your CV, the JD (file, URL, or pasted text), your prep timeline, and any extra context.
- Process documents — uploads are parsed to markdown via LlamaParse (
parse_document); JD URLs are pulled via Tavily (extract_jd). Results land in/processed/, alongside a persisted intake note. - Research — the
hiring-reconsubagent gathers company + role intel and a match analysis →/research/<resume>/<jd>.md. - Tailor & coach (parallel) —
resume-tailorrewrites the CV as arendercvYAML and renders a PDF;interview-coachwrites a structured prep doc (self-intro + per-round STAR stories). - Battlecard — the main agent assembles a one-page-per-round JSON and renders it to a day-of PDF via WeasyPrint.
- Multi-turn updates — ask for changes in chat; the owning agent reads the existing file, preserves everything you didn't name, and re-renders.
The full procedure (file layout, update routing, source-of-truth conventions) lives in backend/app/career_agent/README.md. Per-feature design docs are in docs/prd/.
The agent's behavior is configured by files, not hardcoded — making it easy to read, diff, and extend:
| Primitive | Where | Role | When loaded |
|---|---|---|---|
| Memory | AGENTS.md | Per-stage procedure manual (semantic memory) | Always (system prompt) |
| Skills | skills/<consumer>/<name>/SKILL.md | Task workflows (procedural memory) | On demand, per consumer |
| Subagents | subagents.yaml | Specialist delegates → the task tool | Always |
| Tools | tools.py + DeepAgents built-ins | parse_document, extract_jd, render_battlecard_pdf, prepare_render_settings, list_files, overwrite_file, plus read/write/edit_file, ls/glob/grep, execute | — |
| Filesystem | CompositeBackend | Routes virtual paths to the right store (see below) | — |
| Middleware | middleware.py | ModelOverrideMiddleware (runtime LLM swap) + UtcDatetimeMiddleware | — |
Subagents only receive the tools they opt into in YAML — tool whitelisting keeps interview-coach, for example, from inheriting the main agent's full toolset.
A single CompositeBackend gives the agent one virtual filesystem while routing each path prefix to the right physical store — Postgres for text artifacts, disk for binaries and render outputs, and a shell backend that translates virtual paths to real ones before running commands like rendercv render.
flowchart LR
    Agent["Agent filesystem tools<br/>read_file · write_file · edit_file<br/>ls · glob · grep · execute"]
    CB{{"CompositeBackend<br/>routes virtual paths"}}
    Agent --> CB
    subgraph Shell["VirtualPathShellBackend · default route"]
        SH["rewrites /virtual/path → on-disk path<br/>before subprocess.run<br/>(e.g. rendercv render /tailored_resume/...)"]
    end
    subgraph Store["StoreBackend · Postgres + pgvector"]
        ST["/memory/ · /processed/ · /research/<br/>/interview_coach/<br/>/large_tool_results/ · /workspace/"]
    end
    subgraph Disk["FilesystemBackend · disk (binaries + renders)"]
        DK["/upload/ · /tailored_resume/<br/>/render_intermediate/<br/>/interview_battlecard/"]
    end
    CB -->|default| Shell
    CB -->|KV routes| Store
    CB -->|binary + PDF routes| Disk
    Sem["Semantic memory · AGENTS.md"] -. loaded into system prompt .-> Agent
    Proc["Procedural memory · skills/*/SKILL.md"] -. loaded on demand .-> Agent
    Work["Working memory · LangGraph thread"] -. drives .-> Agent
    Store --- Epi["Episodic memory · persisted artifacts<br/>(incl. /memory/ auto-memory)"]
    Disk --- Epi
Mapped to memory types:
- Working memory — the live LangGraph conversation thread.
- Semantic memory —
AGENTS.md, always in the system prompt. - Procedural memory —
skills/*/SKILL.md, loaded on demand. - Episodic memory — persisted artifacts in Postgres + disk, including auto-memory: standing preferences saved to the
/memory/route and auto-applied across sessions.
| Layer | Stack |
|---|---|
| Backend | Python 3.13 · LangChain v1 · LangGraph 1.x · DeepAgents 0.6 · uv · served on langchain/langgraph-api:3.13 |
| Agent I/O | Tavily (web search) · LlamaParse / LlamaCloud (document parsing) · rendercv (resume → PDF) · WeasyPrint (battlecard → PDF) |
| Frontend | Next.js 16 · React 19 · TypeScript · Tailwind · pnpm · @langchain/react (v2 useStream) |
| Data | PostgreSQL 18 + pgvector · Redis 8 |
| Infra | Docker Compose (frontend · backend · postgres · redis) |
| Observability | LangSmith |
Because NextRole runs on the LangGraph Agent Server, the career_agent assistant is also reachable by other tools and agents — no extra code:
- MCP — exposed as Model Context Protocol tools at
/mcp(Streamable HTTP), usable by any MCP-compliant client. → docs - A2A — Google's Agent2Agent protocol at
/a2a/{assistant_id}(JSON-RPC 2.0;message/send+message/stream). → docs - The full server API is browsable at the
/docsendpoint of your deployment.
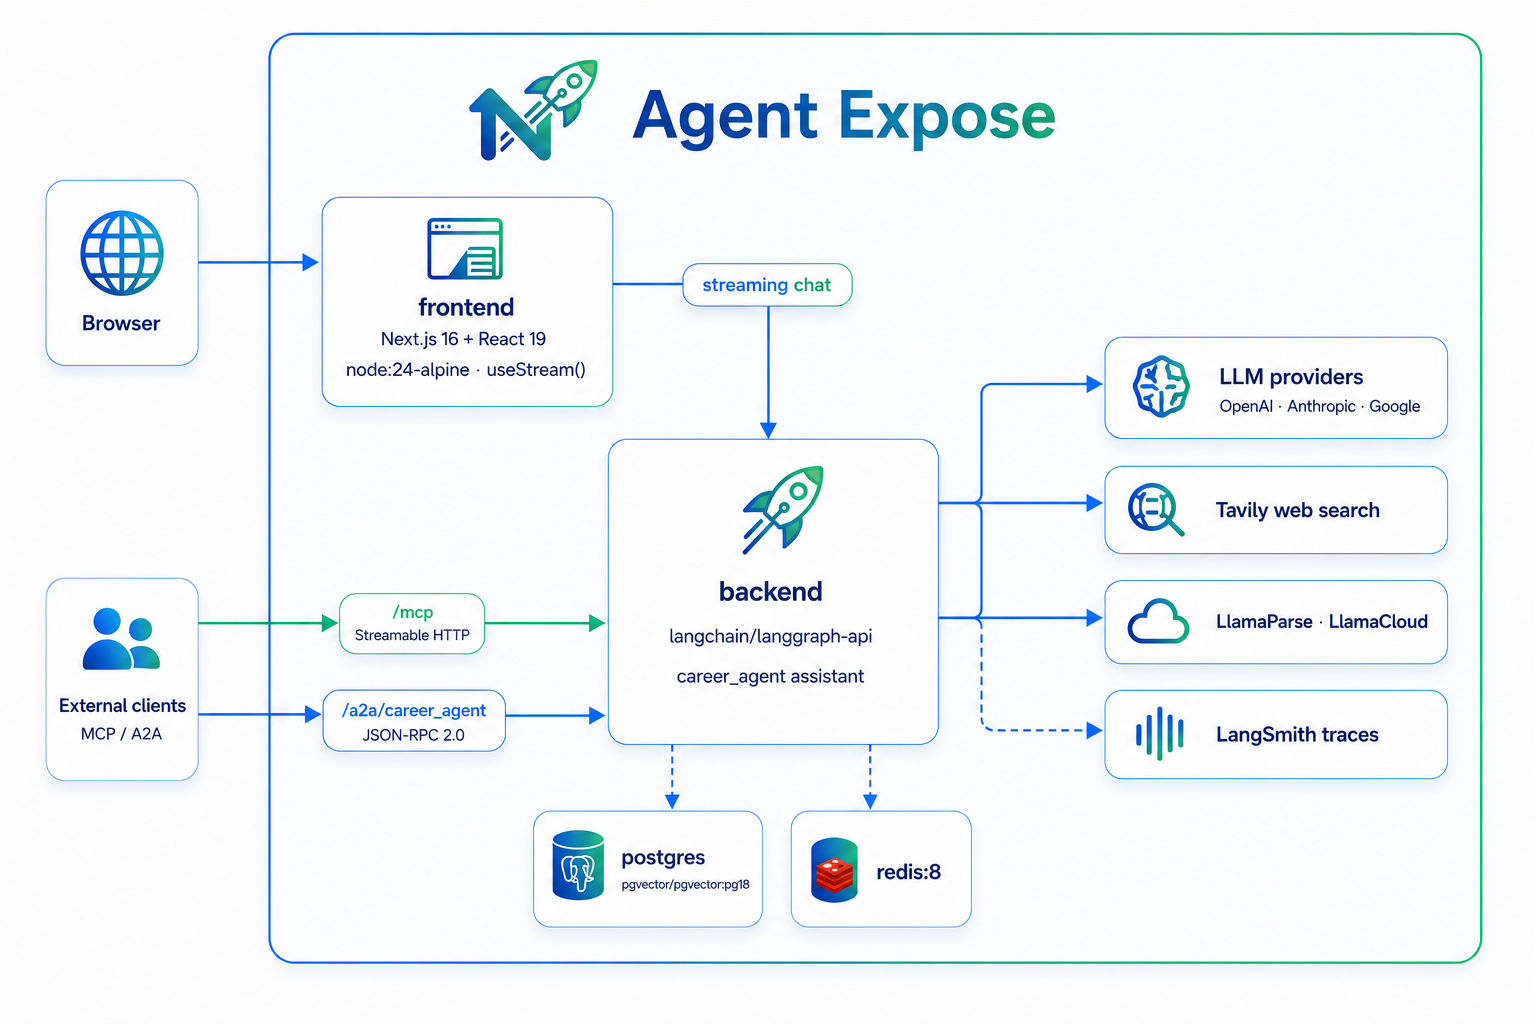
Set LANGCHAIN_API_KEY and LANGCHAIN_TRACING_V2=true in .env, and every run — each LLM call, tool call, and nested subagent — is traced at smith.langchain.com under the LANGCHAIN_PROJECT you configure. Optional, but invaluable for debugging the multi-agent flow.
Roadmap
- 💤 "Auto-dream" consolidation — sleep-time compaction that prunes stale notes and merges insights into durable memory.
- 📦 Remote sandboxes — swap
LocalShellBackendfor an isolated remote sandbox (e.g. Daytona) so render/shell steps are safe for multi-tenant use. - 📊 Agent evaluation — LangSmith evals over the workflow (the
@pytest.mark.evalmarker is already reserved). - 🎨 Enhanced UI — richer artifact editing, diff views, and inline regeneration.
- 🔌 MCP / A2A examples — sample integrations driving
career_agentfrom external agents and IDEs. - 🧵 Per-thread / multi-user scoping — namespace artifacts per user instead of the current global layout.
- 🌐 More sources & ATS-aware tailoring — pluggable retrievers + keyword/ATS optimization passes.
Limitations
NextRole is built for local, single-user, trusted use today.
- 🔒 Local shell execution —
VirtualPathShellBackendruns render commands viasubprocesson the host. Safe locally; not hardened for multi-tenant production (needs sandboxing — see roadmap). - 👤 Global file scoping — uploads and artifacts share one filesystem layout; re-uploading a filename overwrites. No per-user isolation yet.
- 🧪 LLM evals deferred — current tests are unit + local-DB integration; automated quality evals aren't wired up yet.
- 🧠 Personalization is preferences-only — the agent persists and auto-applies the preferences you state across sessions, but doesn't yet infer your style/history on its own or consolidate memory over time (see roadmap).
- ⏱️ Latency — a full run makes several LLM and tool calls across multiple agents; expect minutes, not seconds.
Contributing
PRs and issues are welcome! Start with CONTRIBUTING.md — it walks through the fork → PR workflow, local setup, the CI quality gate (pre-commit + backend tests), testing, and conventions. Stack-specific details live in backend/CLAUDE.md and frontend/CLAUDE.md; commits follow Conventional Commits.
New here? Issues labelled good first issue are a gentle place to start, and questions are welcome in Discussions.
License
MIT © 2026 Tam Nguyen
Acknowledgements
Built on DeepAgents, LangChain / LangGraph / LangSmith, rendercv, WeasyPrint, Tavily, and LlamaIndex / LlamaParse.