
MarketMind — Gerador de Campanhas de Marketing com Multi-Agents
richakumari0311/MarketMind
Gerador automático de campanhas de marketing com multi-agentes e memória persistente
Ver no GitHubSistema de IA multi-agentes que gera campanhas de marketing completas a partir de descrições de produtos. Orquestra quatro agentes especializados (Research, Strategy, Content, Critique) que realizam pesquisa web ao vivo, definem estratégia, criam conteúdo tipado por canal e reescrevem automaticamente peças fracas. Suporta LLM local (Ollama) ou Anthropic, com streaming em tempo real via SSE.
Instalação
npx convez-ai richakumari0311/MarketMind1 comando no terminal: detecta o formato do repositório (marketplace ou plugin avulso) e instala via Claude Code. Requer Node 18+ e o Claude Code instalado.
Métricas
Casos de uso
- Gerar pesquisa de mercado, estratégia e conteúdo em uma única execução
- Criar campanhas multi-canal (blog, LinkedIn, email) com consistência
- Acumular conhecimento entre rodadas via memória JSON para evitar repetição de ângulos
Veredito

MarketMind é um agente robusto e well-engineered para automação de marketing em escala. A orquestração multi-agentes com memória persistente, suporte a LLM hot-swap e pipeline SSE demonstra expertise técnica sólida; recomendado para equipes que querem automatizar geração de campanhas com controle sobre modelos e dados.
README
A tradução para o português deste README ainda está na fila.
MarketMind
An AI-powered marketing campaign generator built with a multi-agent pipeline. Give it a product description and it returns a full campaign — market research, strategy brief, written content, and a critique with automatic rewrites — in a single run.
What it does
MarketMind chains four specialised agents, each with a focused job:
| Agent | Input | Output |
|---|---|---|
ResearchAgent | Product description | Audience, competitors, pain points, positioning (grounded in live web search) |
StrategyAgent | Research | Campaign name, channel plan, messaging hierarchy, 4-week content calendar |
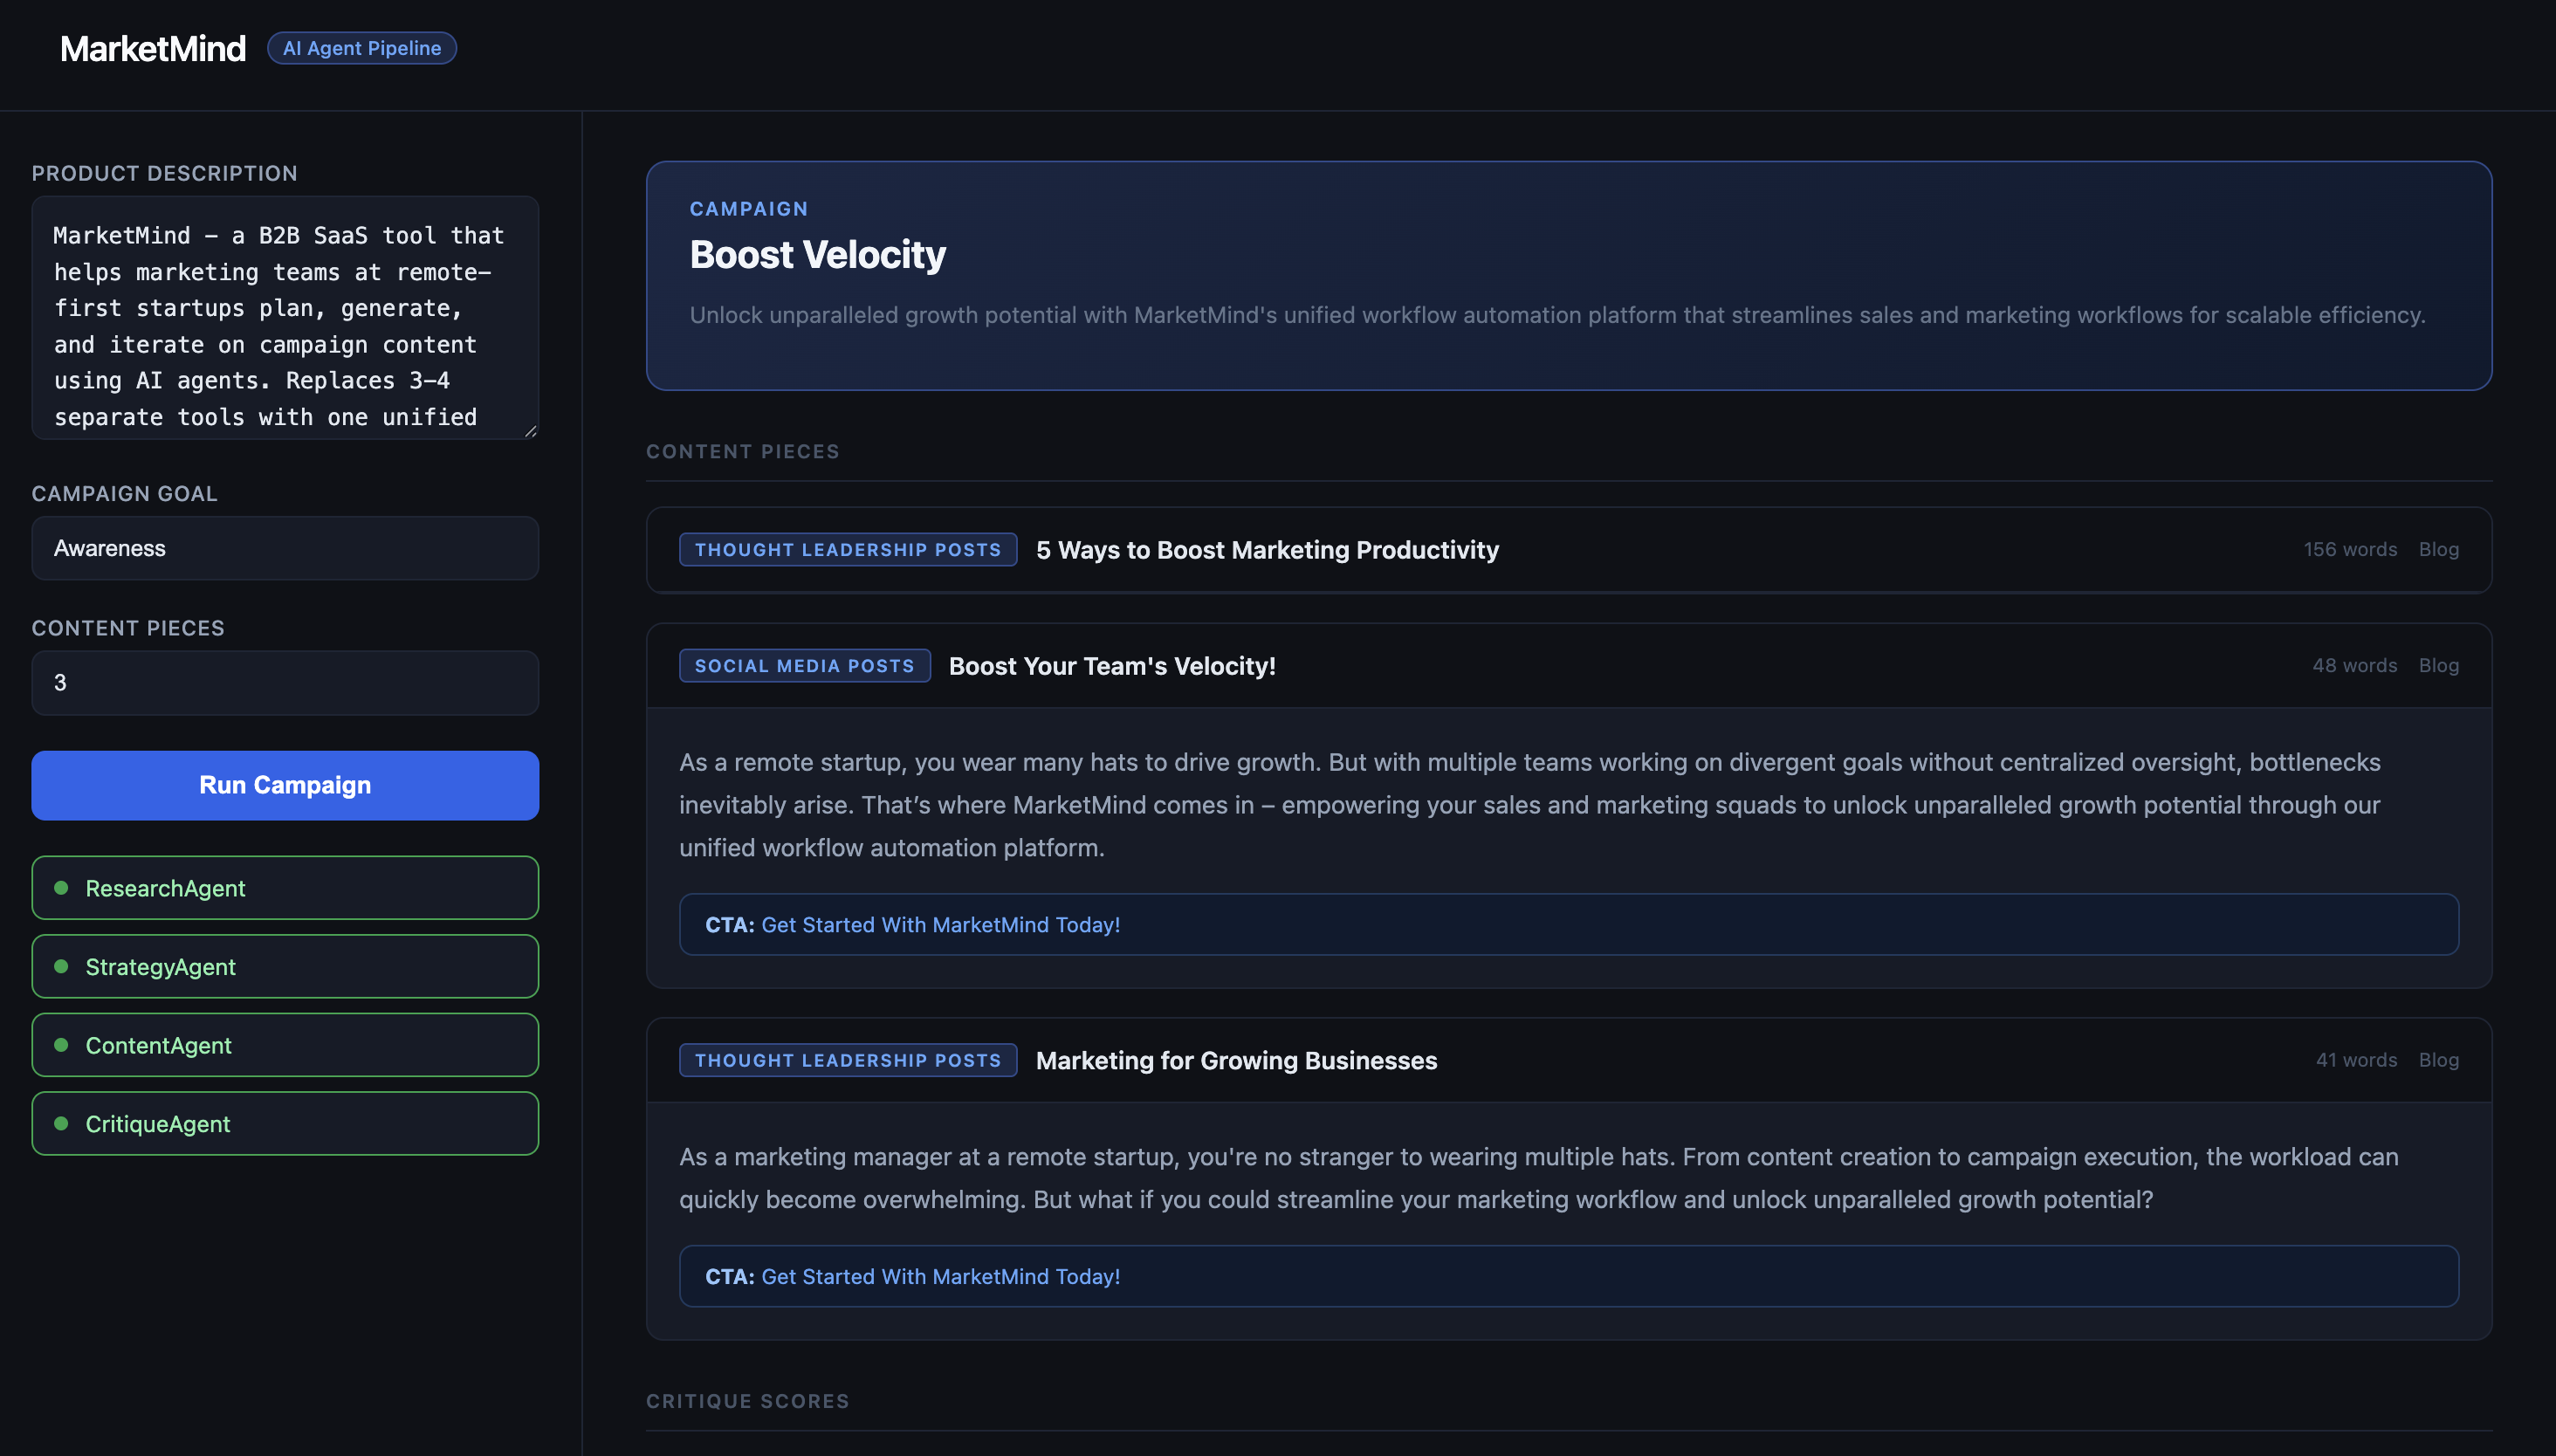
ContentAgent | Strategy | Blog posts, LinkedIn posts, email newsletters — typed per channel |
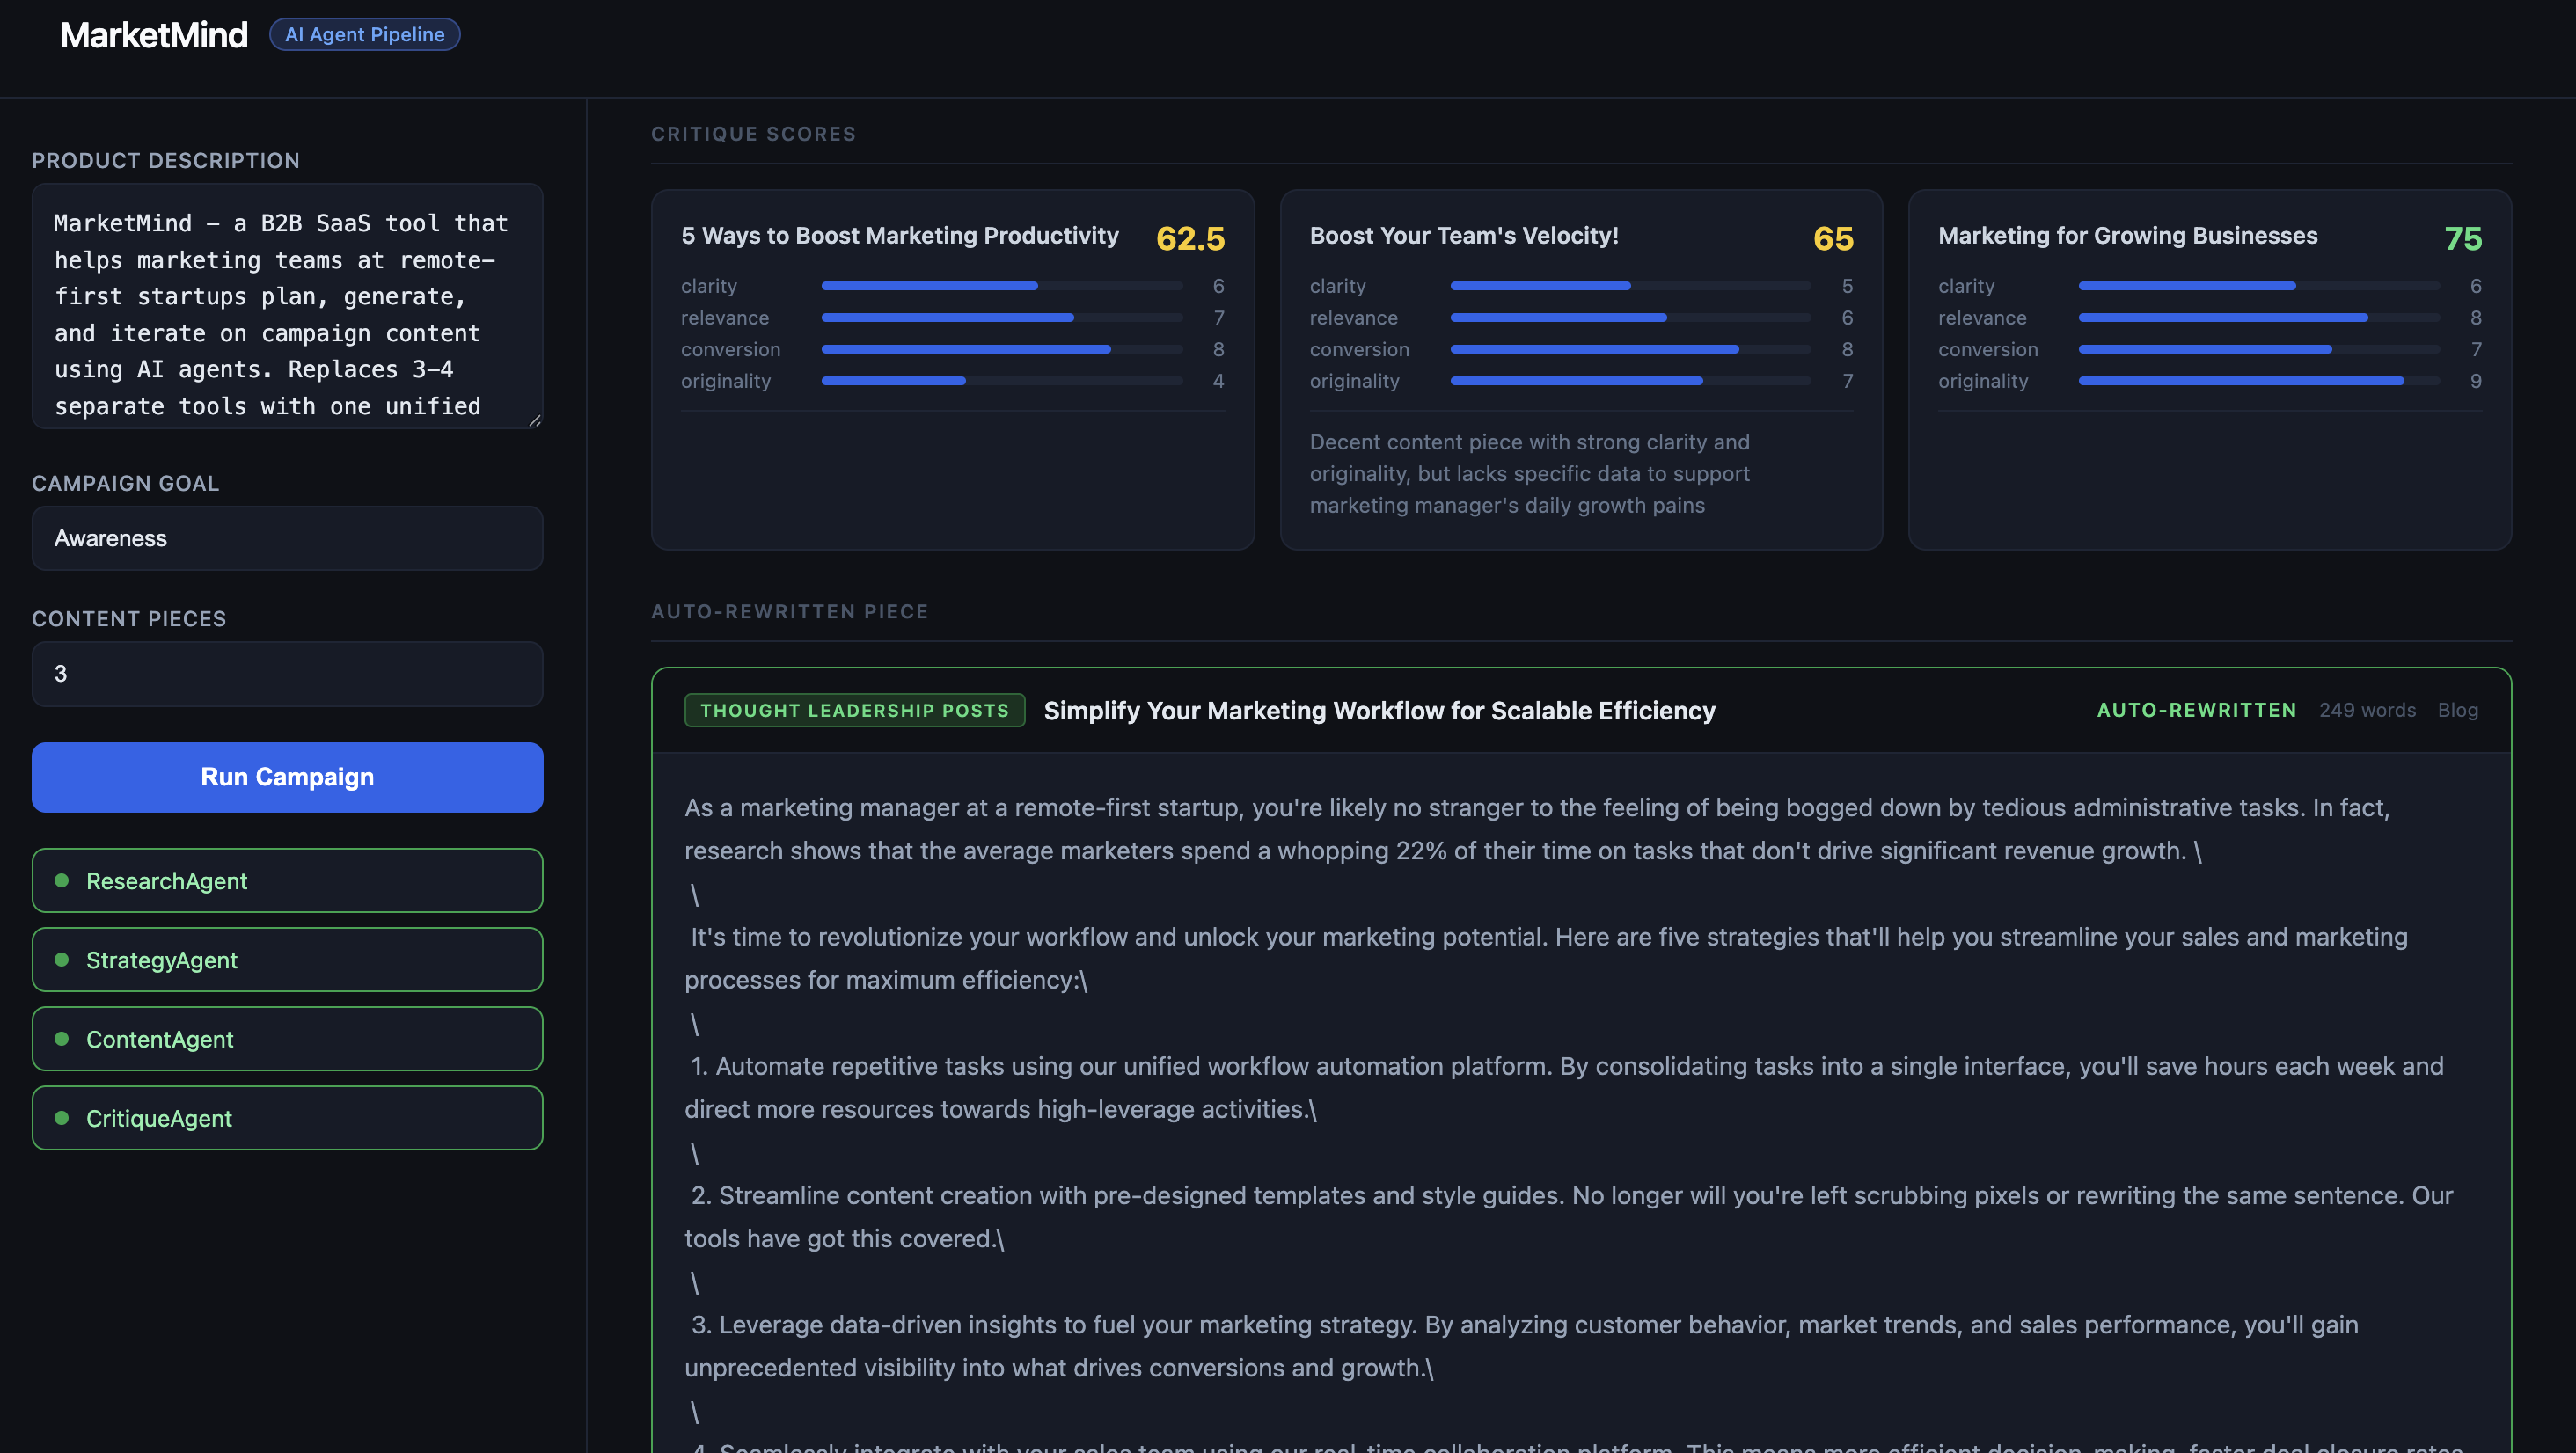
CritiqueAgent | All content | Scores per piece (clarity, relevance, conversion, originality), auto-rewrites the weakest |
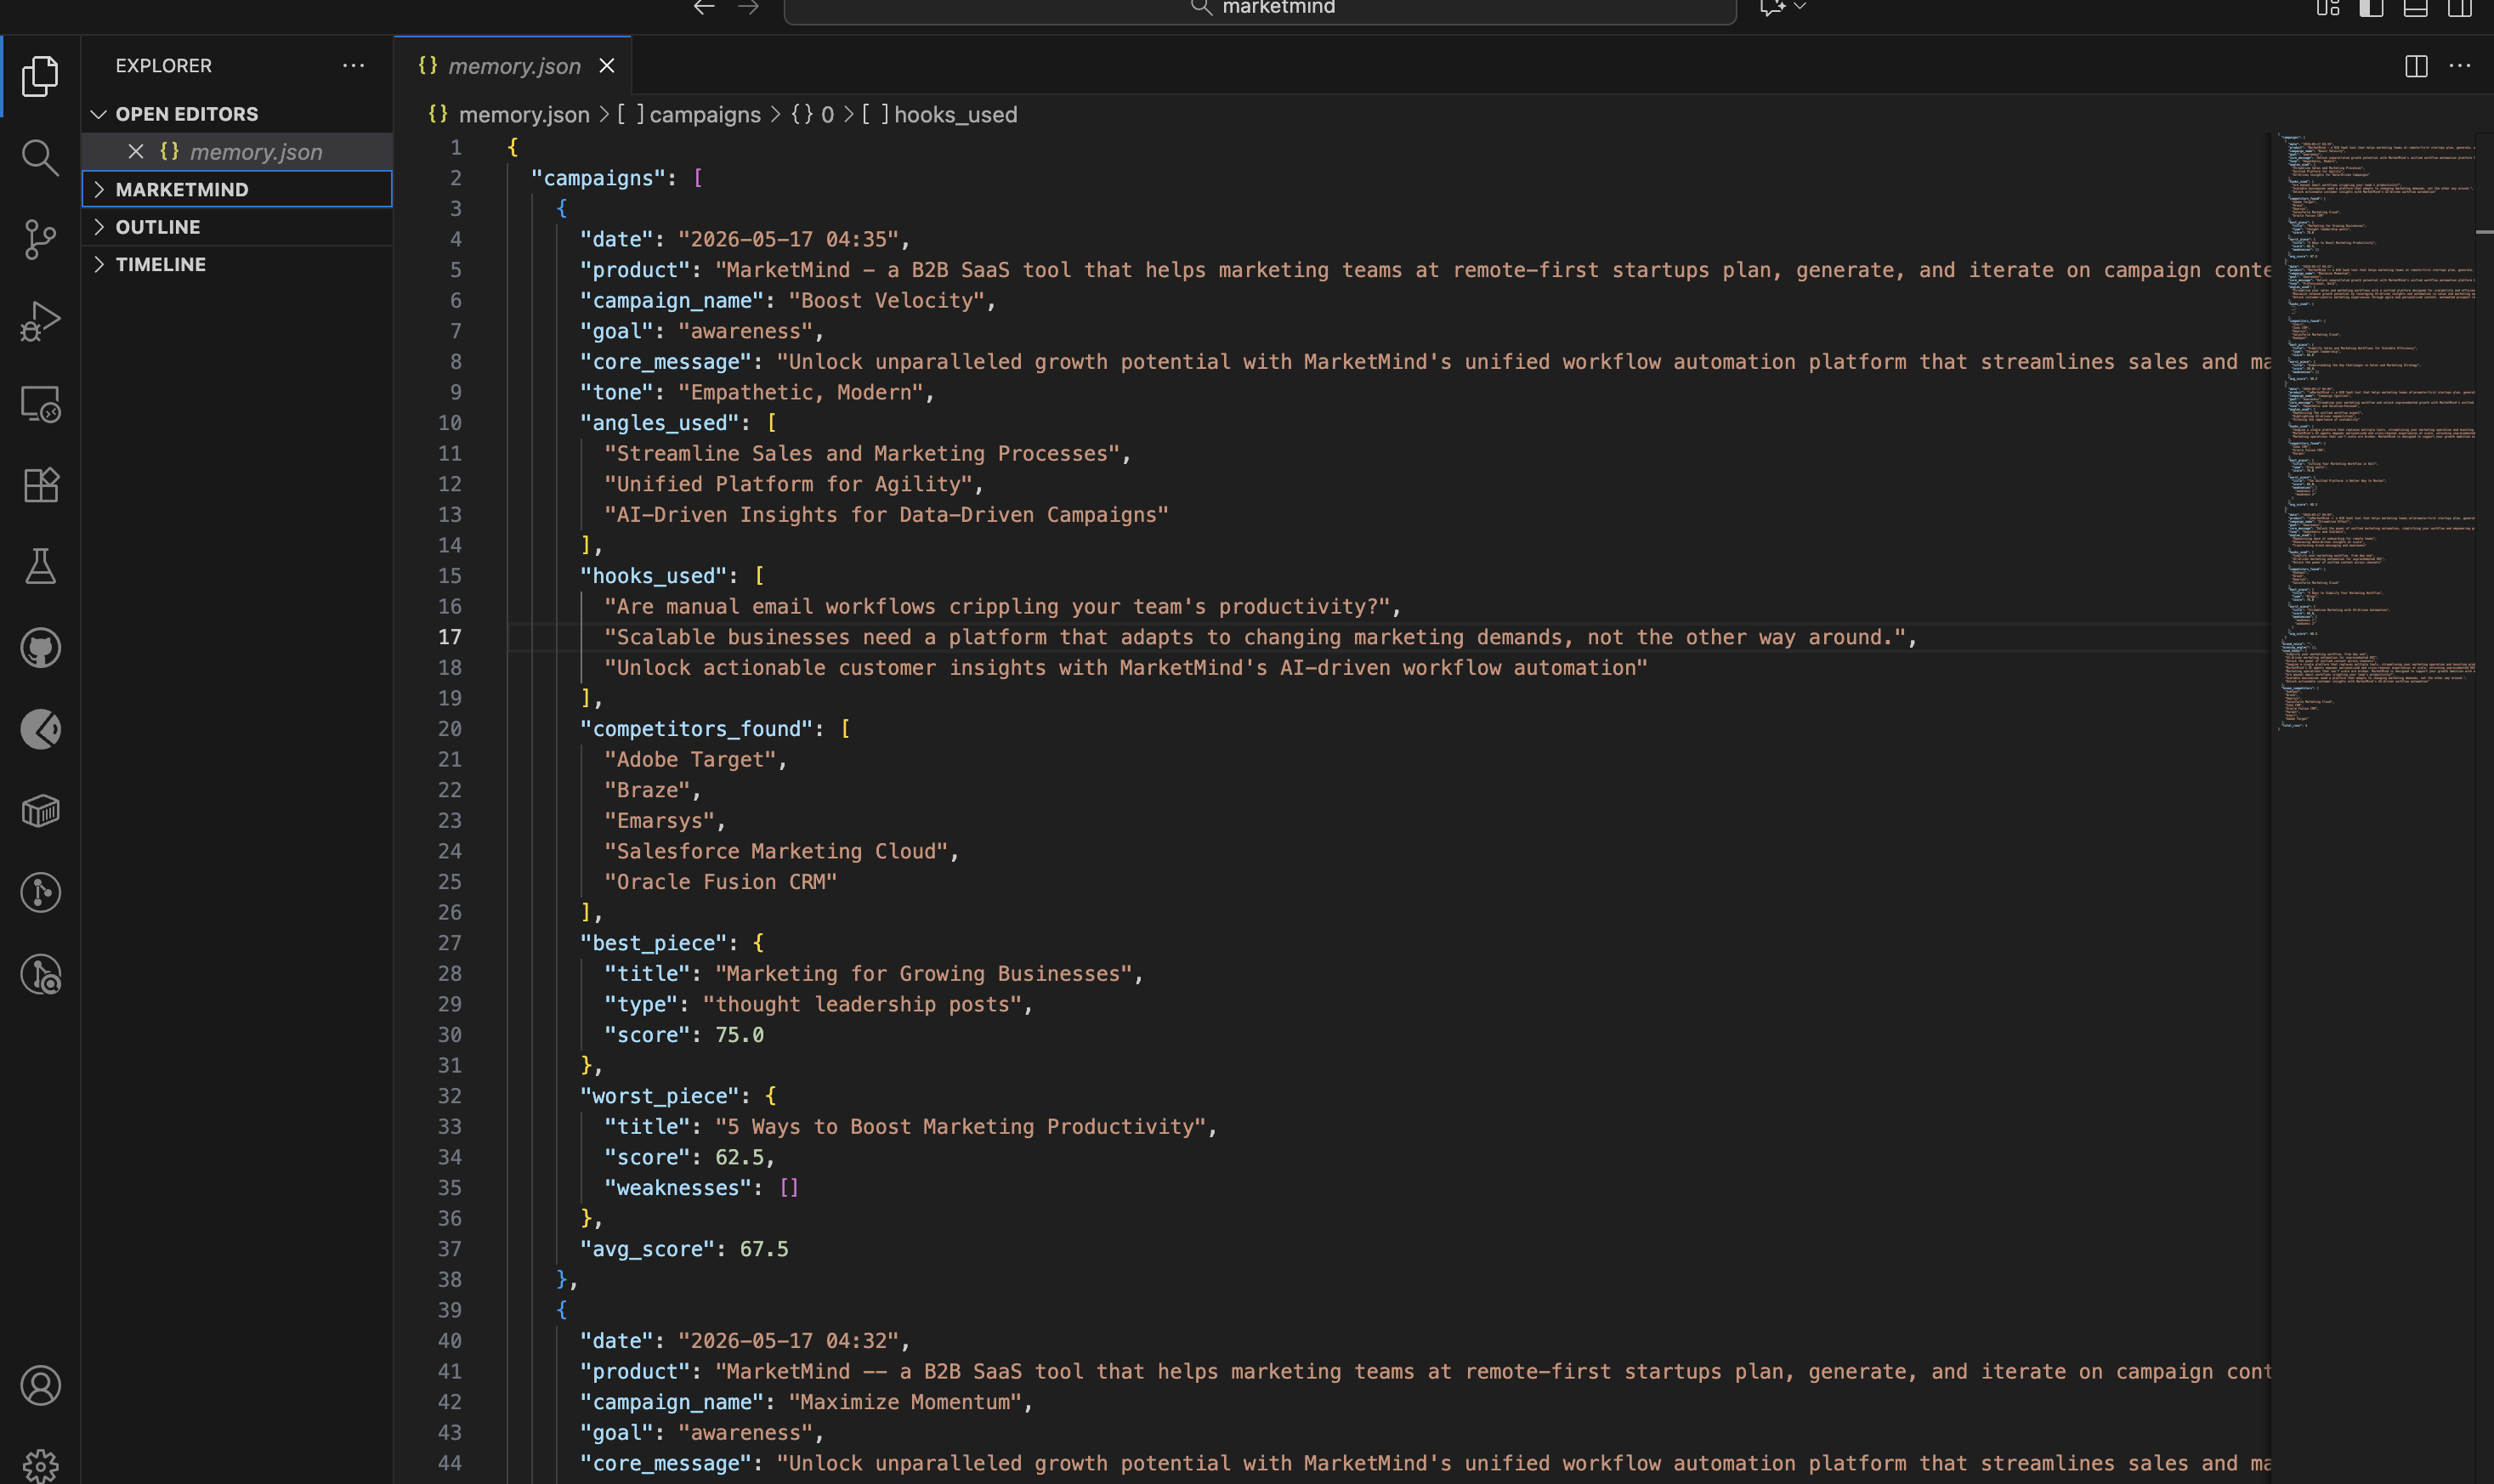
Every run is saved to memory.json. On the next run, agents read past campaigns to avoid repeating angles, hooks, and campaign names — the system compounds knowledge over time.
Screenshots
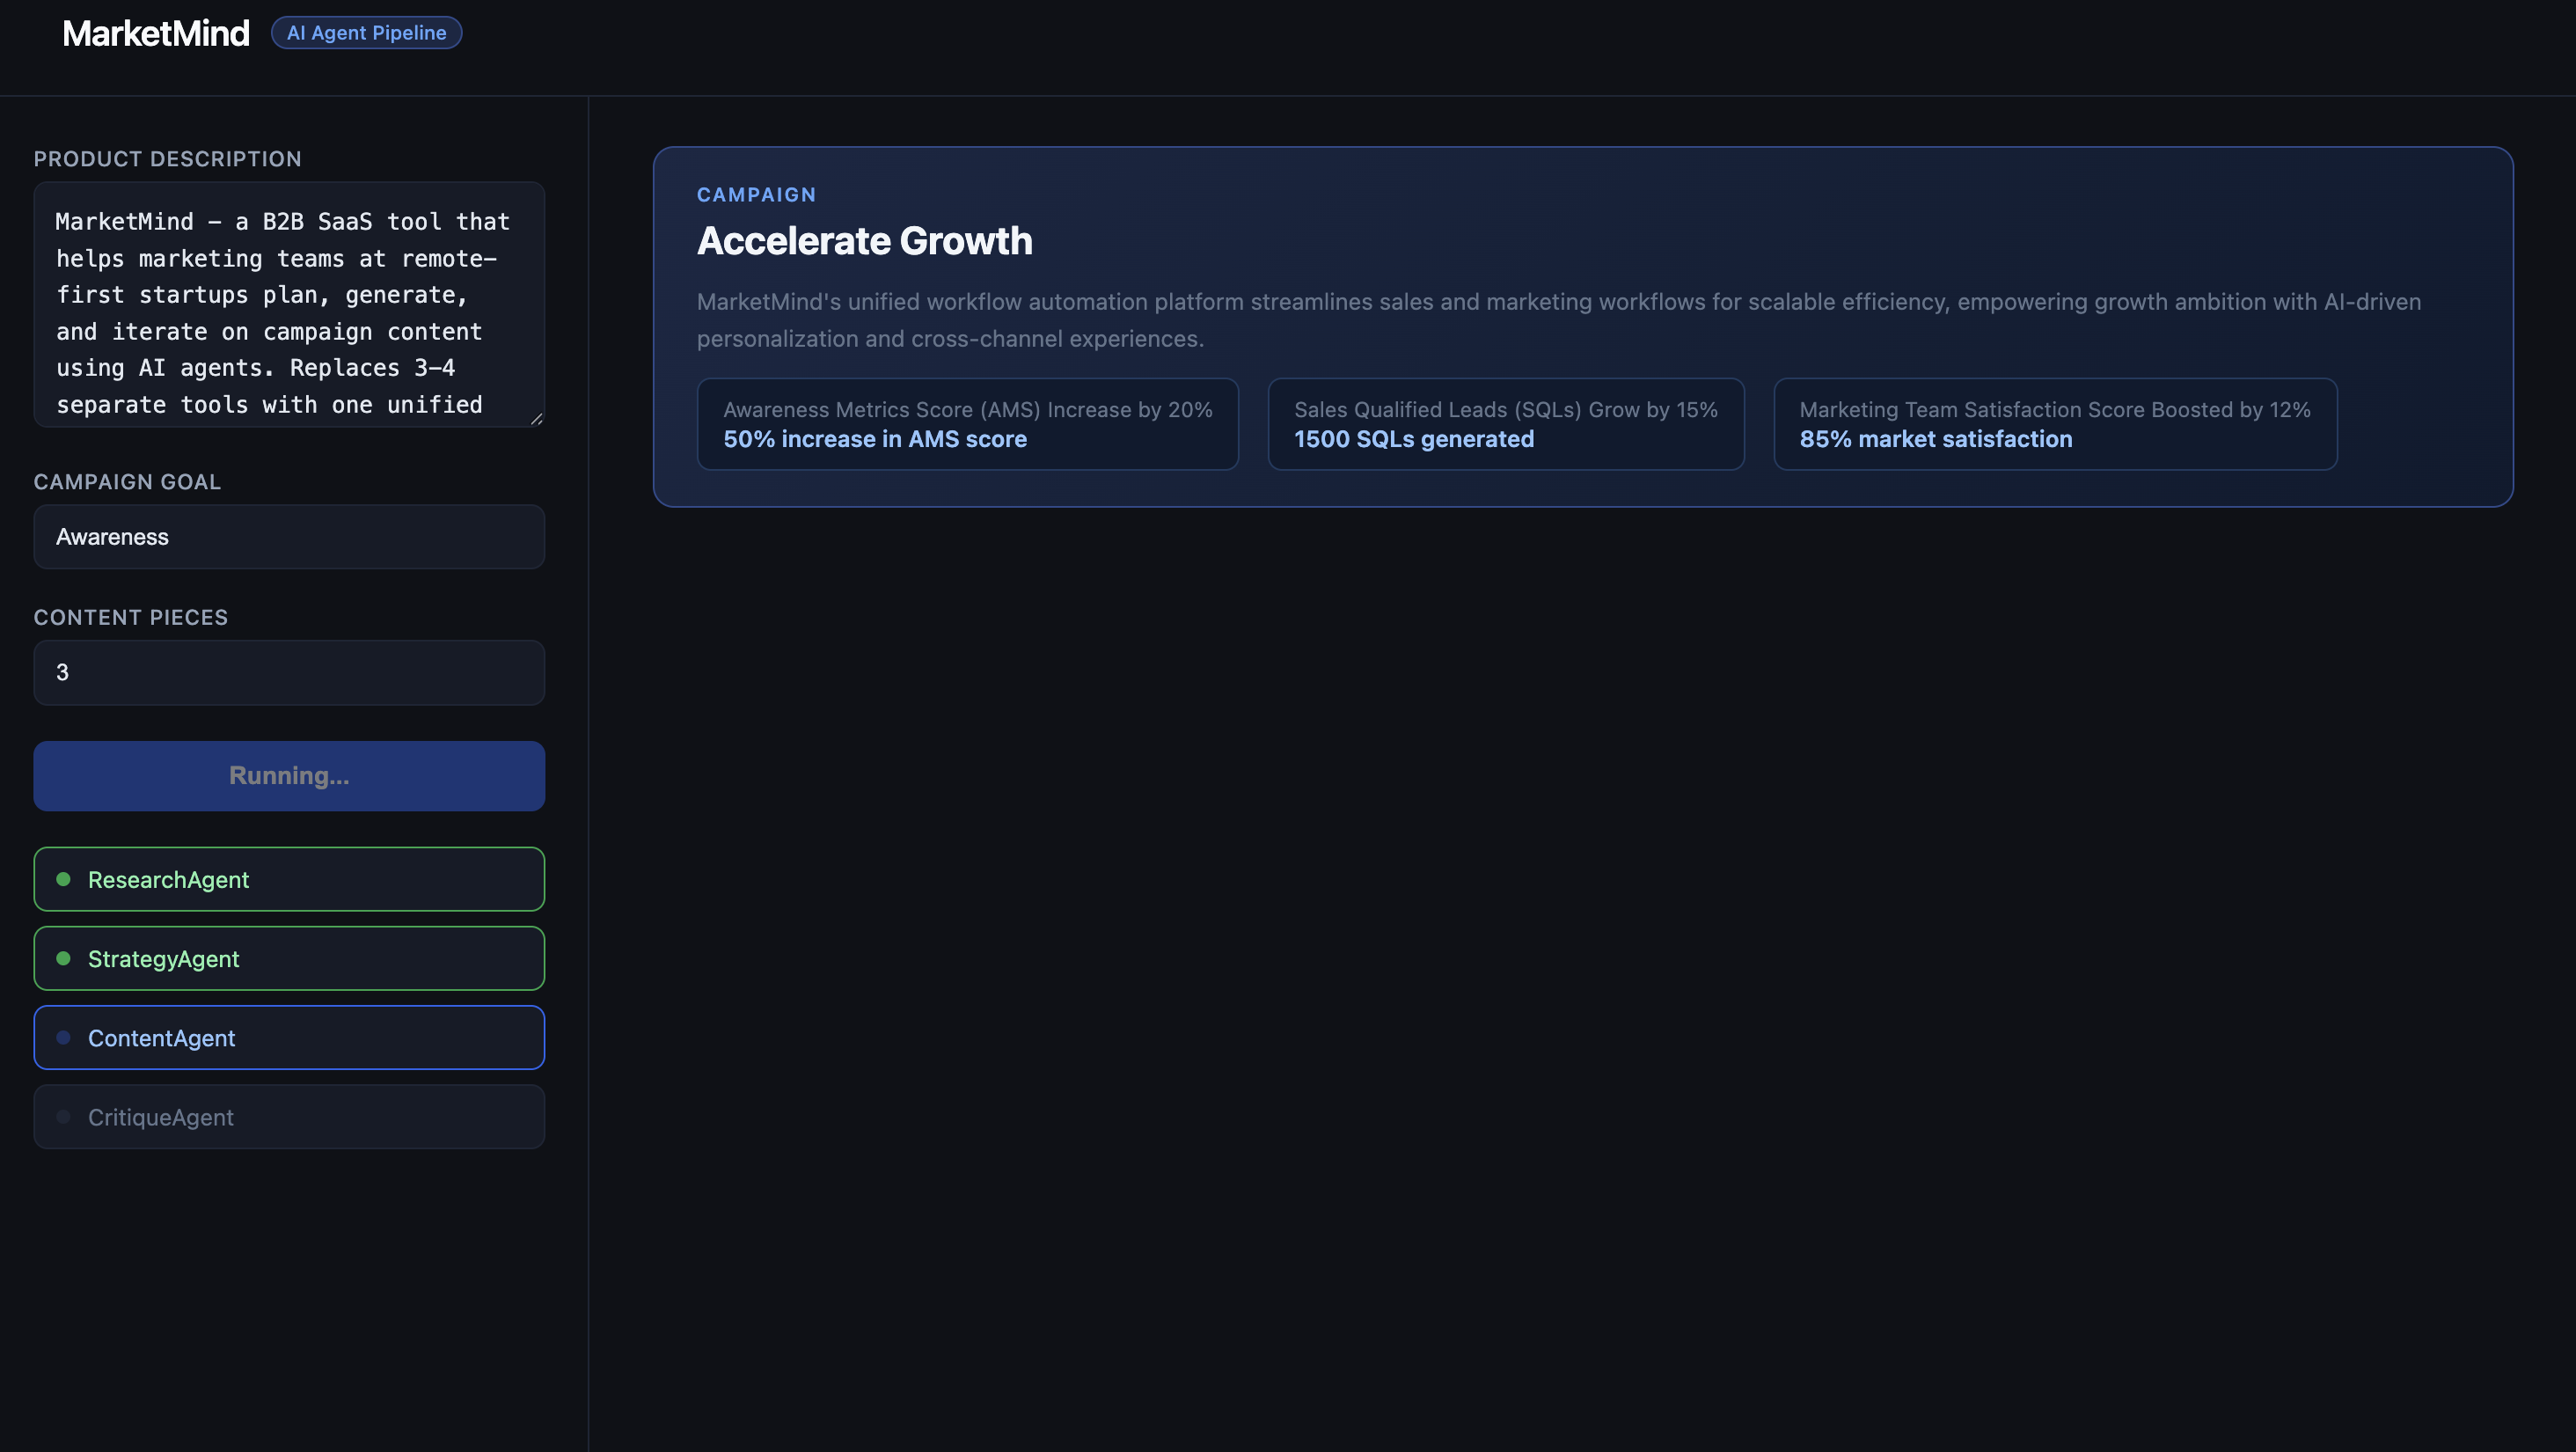
Web UI — live pipeline progress
Campaign output — scores and content
Memory after multiple runs
Stack
- Python 3.10+
- FastAPI — web backend with Server-Sent Events for live pipeline progress
- Ollama (local, free) or Anthropic API (production) — swap with one
.envline - Serper API — live web search for grounded research
- Google ADK — agent orchestration framework
- json-repair — automatic recovery from malformed LLM JSON output
Project structure
marketmind/
├── agents/
│   ├── research_agent.py    # web search + memory-aware research
│   ├── strategy_agent.py    # campaign brief from research
│   ├── content_agent.py     # typed content per channel
│   ├── critique_agent.py    # scoring + automatic rewrite
│   └── orchestrator.py      # chains all agents, saves memory
├── utils/
│   ├── llm_client.py        # unified LLM wrapper (Ollama / Anthropic)
│   ├── tools.py             # web_search(), scrape_page()
│   └── memory.py            # read / write / format campaign memory
├── static/
│   └── index.html           # real-time web UI (SSE)
├── server.py                # FastAPI server
├── cli.py                   # command-line interface
├── main.py                  # quick run via orchestrator
├── .env.example             # required environment variables
└── memory.json              # auto-generated, gitignored
Setup
1. Clone and create environment
git clone https://github.com/richakumari0311/marketmind.git
cd marketmind
python3 -m venv .venv
source .venv/bin/activate
pip install -r requirements.txt
2. Configure environment
cp .env.example .env
Edit .env with your keys:
LLM_PROVIDER=local              # local or anthropic
LOCAL_MODEL=llama3.2
LOCAL_BASE_URL=http://localhost:11434/v1
ANTHROPIC_API_KEY=              # required if LLM_PROVIDER=anthropic
SERPER_API_KEY=                 # get free key at serper.dev
3. Start Ollama (local mode only)
ollama pull llama3.2
ollama serve
4. Run the web UI
uvicorn server:app --reload --port 8000
Open http://localhost:8000 in your browser.
Usage
Web UI
Open http://localhost:8000, fill in your product description, choose a campaign goal, and click Run Campaign. Each agent streams progress live as it runs.
CLI
# Run with built-in demo product
python cli.py

# Run with your own product
python cli.py --product "Your product description here" --goal leads --pieces 3

# Save full JSON output to disk
python cli.py --save output.json

# Show scores only, skip printing full content
python cli.py --scores-only
CLI flags:
| Flag | Default | Options |
|---|---|---|
--product | built-in demo | any string |
--goal | awareness | awareness, leads, retention |
--pieces | 3 | 1 to 6 |
--save | none | path e.g. output.json |
--scores-only | off | flag |
Python
from agents.orchestrator import run

result = run(
    product_description="Your product here",
    campaign_goal="awareness",
    num_pieces=3,
)

print(result["strategy"]["campaign_name"])
print(result["critique"]["scores"])
Switching to Anthropic API
Change one line in .env:
LLM_PROVIDER=anthropic
Add your API key:
ANTHROPIC_API_KEY=sk-ant-...
No other changes needed. Every agent, prompt, and output format stays identical. The Anthropic API eliminates most JSON parsing issues common with local models and produces noticeably better output quality.
Get an API key at console.anthropic.com. Free credits are available on signup.
Memory system
After each successful run, memory.json is updated with:
- Campaign names used (avoided on next run)
- Messaging angles and hooks used (avoided on next run)
- Competitors found across all runs
- Winning angles — angles from runs that scored above 70/100
- Best and worst piece per run with scores
The ResearchAgent and StrategyAgent both read this before running, so the system actively avoids repetition and builds on what worked.
memory.json is gitignored — it stays local to your machine.
Agent scoring dimensions
The CritiqueAgent scores each content piece from 1 to 10 across four dimensions:
| Dimension | What it measures |
|---|---|
| Clarity | Is the message immediately clear? |
| Relevance | Does it speak directly to the target audience? |
| Conversion | Does it drive toward the CTA? |
| Originality | Does it avoid cliches and generic phrasing? |
The final score is the average of all four, scaled to 100. The lowest-scoring piece is automatically rewritten with specific fixes applied and logged.
Requirements
- Python 3.10 or higher
- Ollama (for local mode) -- ollama.com
- Serper API key (free tier) -- serper.dev
- Anthropic API key (for production mode) -- console.anthropic.com
Install all Python dependencies:
pip install -r requirements.txt
Roadmap
- Campaign history sidebar in web UI
- Export campaigns to PDF and DOCX
- Brand voice field in memory for consistent tone
- MCP integrations -- HubSpot, Notion, Google Analytics
- Campaign scheduler -- run on cron, auto-post to LinkedIn
License
MIT