
HarnessAI
reasonableplan/harnessai
Controle rigoroso de agentes IA com contratos, gates de qualidade e detecção de anti-padrões
Ver no GitHubAgent de orquestração multi-agente que força IA a seguir suas regras de código através de contratos de esqueleto, 9 gates de qualidade automatizados e detecção de 21 anti-padrões comuns. Valida segurança, padrões de projeto e integridade de skeleton em tempo real, bloqueando violações antes do deploy.
Instalação
npx convez-ai reasonableplan/harnessai1 comando no terminal: detecta o formato do repositório (marketplace ou plugin avulso) e instala via Claude Code. Requer Node 18+ e o Claude Code instalado.
Métricas
Casos de uso
- Forçar padrões de código e arquitetura em geração de IA
- Validar conformidade de segurança em agentes multi-stack
- Detectar dead code e AI-slop que testes convencionais perdem
- Orquestrar agentes especializados (backend, frontend, mobile) por stack profile
Veredito

Ferramenta robusta para times que precisam governança séria em pipelines de IA—usa gates de qualidade com 100% precision/recall medido em 35 fixtures. Melhor para arquitetos que controlam stacks variados (Python CLI, mobile cross-platform, backends). Implementação Python 3.12+ com cobertura de testes sólida, mas curva de aprendizado íngreme por requerer adaptação do skeleton.md ao projeto.
README
A tradução para o português deste README ainda está na fila.
HarnessAI
🌐 English · 한국어




Make AI agents write code — but force them to follow your rules.
Claude / Cursor / Copilot will write working code, but they don't write it your way. They ignore your CLAUDE.md. They import libraries you didn't allow. Their error handling doesn't match the rest of your codebase. Fixing it by hand defeats the point.
HarnessAI closes that loop:
- A contract (
skeleton.mdwith 36 standard section IDs, auto-selected by 6-axis project answers) declares what will be built before any code exists. - Eleven agents (Architect · Designer · Orchestrator · Backend Coder · Frontend Coder · 4× mobile_coder (RN/Flutter/Android/iOS) · Reviewer · QA) implement the declaration — Orchestrator routes each task to the matching coder by stack profile.
- Ten quality gates automatically block contract violations — 7 security hooks + ai-slop detection + test distribution + skeleton-integrity.
HarnessAI doesn't replace the AI. It controls it.
🎯 What it actually catches
Plain Claude writes this — tests pass, lint passes, code runs:
_BACKOFF_SECONDS = (1.0, 2.0, 4.0, 8.0)   # declares 4 backoff steps
max_retries = 2
for i in range(max_retries):              # but only consumes 2
    time.sleep(_BACKOFF_SECONDS[i])
The constant declares 4 elements; the loop reads 2. Dead code that no test catches because the program runs fine. This is real — LESSON-018 from this repo's own dogfooding log.
/ha-review flags it via the ai-slop hook (the 7th gate):
{
  "hook": "ai-slop",
  "severity": "WARN",
  "message": "dead 상수 의심 (LESSON-018) — 상수 정의 범위 vs 실제 사용 범위 확인",
  "snippet": "_BACKOFF_SECONDS = (1.0, 2.0, 4.0, 8.0)\n+max_retries = 2"
}
This is the kind of error LLMs reliably introduce and humans miss in review. Across 35 fixture cases, the 7 benchmark-measured gates score precision 100% / recall 100% — see gate-coverage.md for which gates and how the other 3 are covered.
🎯 What it actually adapts
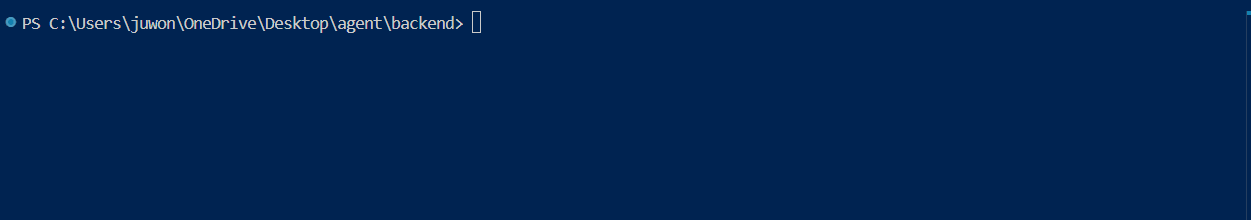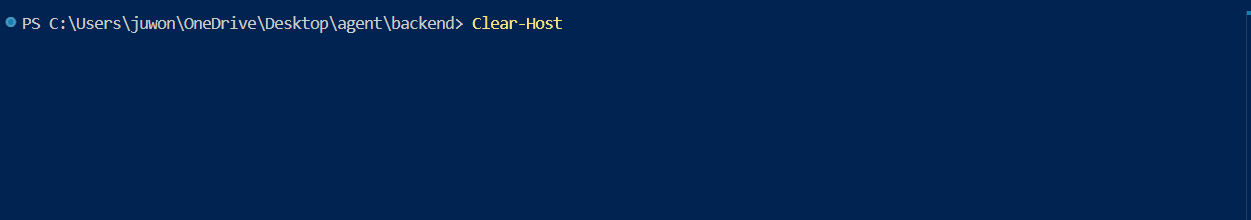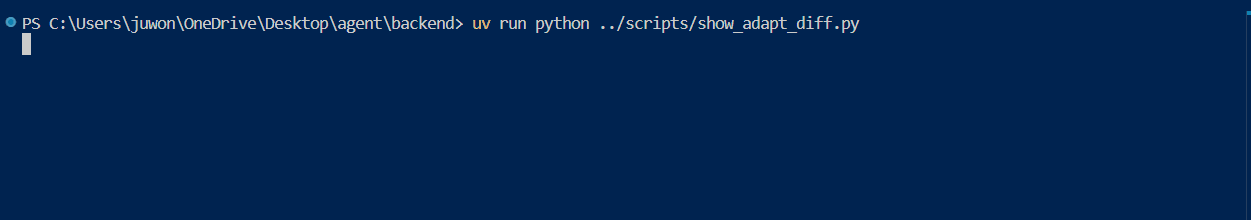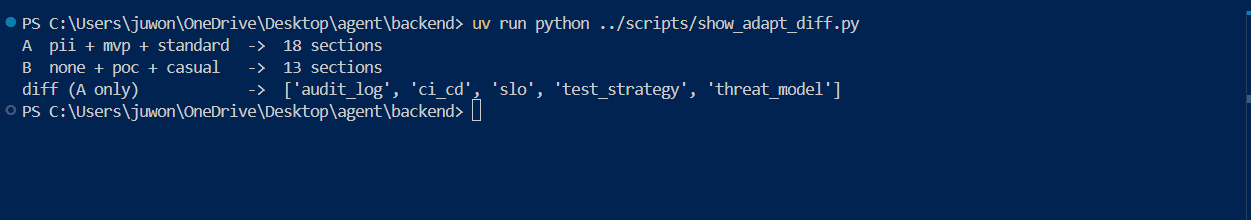
Same python-cli profile, two interview answers — different skeleton.
Baseline — data_sensitivity=none / lifecycle=poc / availability=casual → 14 sections
overview · stack · errors · interface.cli · core.logic ·
configuration · environments · persistence · data_model · external_deps ·
integrations · requirements · tasks · notes
Bumped — data_sensitivity=pii / lifecycle=mvp / availability=standard → 18 sections (baseline 14 + these 4):
| + Section | required_when rule | Why this answer triggered it |
|---|---|---|
audit_log | data_sensitivity in [pii, payment] | sensitive data → compliance log |
threat_model | data_sensitivity in [pii, payment] or availability == high | sensitive data → STRIDE/OWASP |
ci_cd | lifecycle in [mvp, ga] | mvp+ → pipeline / rollback |
test_strategy | lifecycle in [mvp, ga] | mvp+ → test pyramid / contract test |
The 6 axes (user_scale / data_sensitivity / team_size / availability / monetization / lifecycle) are captured by /ha-init. Each fragment's expression is parsed by scale_expression.py, evaluated against the axes, and ProfileLoader.compute_active_sections returns the section list. The rules live in harness/templates/skeleton/*.md frontmatter — full transparency, change them and the loader picks it up.
Reproduce (from a fresh clone, no agent calls):
cd backend && uv run python ../scripts/show_adapt_diff.py
# A  pii + mvp + standard  ->  18 sections
# B  none + poc + casual   ->  14 sections
# diff (A only)            ->  ['audit_log', 'ci_cd', 'test_strategy', 'threat_model']
🚀 30-second usage
git clone https://github.com/reasonableplan/harnessai.git
cd harnessai
./install.sh                          # Windows: .\install.ps1
export HARNESS_AI_HOME="$(pwd)"       # the installer prints this line
In a fresh Claude Code session:
/ha-init     # detect stack + interview → harness-plan.md + skeleton.md
/ha-design   # Architect + Designer fill skeleton sections
/ha-plan     # Orchestrator decomposes into tasks.md
/ha-build T-001          # implement one task [sonnet]
/ha-verify   # run toolchain + skeleton integrity gate [sonnet]
/ha-review   # security hooks + LESSONs + ai-slop + test distribution
/ha-smoke    # runtime launch probe — does the app actually start? (advisory)
Deep dive: ARCHITECTURE.md · SETUP.md
🏗 Pipeline
               ┌─ profile detection (~/.claude/harness/profiles/) ┐
               │                                                  │
  /ha-init ───▶│ harness-plan.md  +  skeleton.md (empty template) │
               └──────────────────────────┬───────────────────────┘
                                          ▼
  /ha-design ─────▶ Architect + Designer (up to 3 negotiation rounds) ─▶ fills skeleton
                                          ▼
  /ha-plan   ─────▶ Orchestrator ─▶ tasks.md (dependency graph)
                                          ▼
  /ha-build  ─────▶ Backend/Frontend Coder ─▶ source files
    │                                 [--parallel T-001,T-002  ← ultrawork]
    ▼
  /ha-verify ─────▶ [1] harness integrity (skeleton ↔ real FS)
                    [2] profile toolchain (pytest / ruff / pyright)
                                          ▼
  /ha-review ─────▶ Security hooks × 7 + LESSONs × 31 + ai-slop × 7 + test distribution
                                          ▼
  /ha-smoke  ─────▶ runtime launch probe (exit 0 / URL readiness) — advisory
                                          ▼
                               APPROVE / REJECT → /ship
Each stage can chain with gstack skills (/office-hours, /plan-eng-review, /review, /qa, /ship, /retro).
🙋 Human-In-The-Loop Gate (v0.10.0+)
Three sections (persona / user journey / screen designs) consistently produce flat results when AI fills them by guessing. v0.10.0 forces user interview for those sections.
<!-- HUMAN-LOCKED:<section_id> -->markers inskeleton.md— a PreToolUse hook (~/.claude/harness/bin/check_locked.py) blocks any Edit/Write inside locked regions/ha-designpresents 5 AI candidates per LOCKED section →AskUserQuestion→ user picks → section filled/ha-buildentry requiresfrozen_status="frozen"inharness-plan.mdfrontmatter- Design changes go through
/ha-redesign(audit record + mutation propagation), not direct edits
# Migrate an existing v0.9.x project
python ~/.claude/harness/bin/harness migrate-v10 docs/harness-plan.md

# Run /ha-design to complete HITL interview + freeze
/ha-design

# Build as normal
/ha-build T-001

# Escape hatch for development / CI (user takes responsibility)
/ha-build --skip-frozen-gate
🎯 Core ideas
1. Profiles — declare rules per stack
A single file under ~/.claude/harness/profiles/<stack>.md holds every rule for that stack:
- Detection rules (which files indicate this stack)
- Components (required / optional)
- skeleton_sections (which sections must be filled)
- toolchain (test / lint / type commands)
- whitelist (allowed dependencies)
- lessons_applied (which LESSONs enforce here)
Twelve profiles ship by default: fastapi · nestjs · nextjs · react-vite · electron · python-cli · python-lib · claude-skill · react-native-expo · flutter · android-kotlin · ios-swift. Adding a new stack is one file.
2. Skeleton — the project contract
Thirty-six standard section IDs; profiles pick which ones apply, and 6-axis user answers further narrow to project-fit sections (mobile profiles activate mobile.navigation / mobile.build_config / mobile.lifecycle via has.* atoms):
overview · requirements · stack · configuration · environments · errors · auth ·
persistence · integrations · interface.{http,cli,ipc,sdk} ·
view.{screens,components} · state.flow · core.logic ·
observability · deployment · error_ux · tasks · notes ·
data_model · threat_model · audit_log · slo · runbook ·
test_strategy · user_journey · authorization_matrix · ci_cd · external_deps ·
rate_limiting · mobile.{navigation,build_config,lifecycle}
The last 13 (data_model … rate_limiting) are activated by required_when expressions evaluated against the 6 axes — see What it actually adapts below. The 3 mobile.* sections are activated by mobile profile declarations (has.navigation / has.build_config / has.lifecycle atoms).
The section content is the contract. /ha-verify checks that declared filesystem paths actually exist, and that placeholders (<pkg>, <cmd_a>) were replaced.
3. Shared Lessons — institutional memory
backend/docs/shared-lessons.md stores 28 past mistakes. Every bug that was ever made gets a LESSON entry. Future /ha-review sessions read those entries so the same class of mistake never repeats.
Examples:
- LESSON-001 — FastAPI query params must be snake_case
- LESSON-018 — Constant definition length vs. actual consumption (dead-constant detection)
- LESSON-020 —
[N/M]progress indicators must actually update (no cosmetic fakes) - LESSON-021 — A task is
doneonly after test + lint + type all pass
LESSONs are enforced in three ways: text reference (Reviewer agent reads them), regex auto-detection (LESSON-018 via ai-slop patterns), and hard gates (LESSON-013 via test-distribution, LESSON-021 via toolchain-gate).
🆚 Comparison
| HarnessAI | Cursor / Copilot | Claude Code (plain) | aider | |
|---|---|---|---|---|
| Scope | Whole project | File / function | Conversation-based | Diff-based |
| Rule enforcement | Profiles + 10 gates | .cursorrules (advisory) | CLAUDE.md (advisory) | Commit style only |
| Mistake accumulation | 28 LESSONs (auto-detect + reviewer context) | ❌ | ❌ | ❌ |
| Stack auto-detection | 12 built-in + extensible (web · desktop · CLI · lib · 4 mobile) | ❌ | ❌ | ❌ |
| Parallel implementation | /ha-build --parallel | ❌ | ❌ | ❌ |
| Design-implementation contract | skeleton.md + integrity gate | ❌ | ❌ | ❌ |
Where HarnessAI fits: multiple small-to-medium projects built to the same quality bar, where you want the system to remember mistakes so you don't have to.
Where it doesn't: one-off scripts, exploratory prototypes, large legacy codebases (use /ha-deepinit first).
📦 Installation
# Unix / WSL / macOS / Git Bash
./install.sh

# Windows PowerShell
.\install.ps1
What it does:
- Copies
harness/+skills/ha-*+skills/_ha_shared→~/.claude/ - Records SHA256 in
~/.claude/harness/.install-manifest.json(diff detection on re-runs) - Supports
--force/--dry-run CLAUDE_HOME=/custom/path ./install.shfor a custom target
Env var: set HARNESS_AI_HOME to the absolute path of this repo after install. The installer prints the exact command.
🧪 Quality gates (15 BLOCK-class + 10 advisory)
Full registry with stage / severity / bypass flag: backend/docs/GATES.md. Highlights:
| Gate | Location | Role |
|---|---|---|
| secret-filter | security_hooks.py | Detect hardcoded tokens / keys / DB connection strings |
| command-guard | " | Block rm -rf, eval, DROP TABLE, … |
| db-guard | " | Block raw SQL, f-string SQL, WHERE-less DELETE/UPDATE |
| dependency-check | " | Block non-whitelisted imports / installs |
| code-quality | " | Bare except:, print debugging, excessive # type: ignore |
| contract-validator | " | Endpoints outside the skeleton's interface.http |
| auth-guard | " | JWT type+ver claim missing, localStorage token storage, logout no-op, MAX()+1 race (LESSON-022~027) |
| ai-slop (8th hook) | ha-review/run.py | 6 regex patterns — verbose docstrings, cosmetic try/except, dead constants (LESSON-018), TODO/FIXME, unused funcs, stub pass |
| test distribution | " | Detect skewed test coverage (BLOCK: 0 tests for a src module, WARN: 10x variance) |
| skeleton integrity | harness integrity | Declared paths ↔ real filesystem + placeholder residue |
| file_structure drift | ha-build (advisory) | Detects uncommitted FS drift vs skeleton-declared paths (WARN) |
| skeleton drift gate | ha-build prepare | Post-freeze external skeleton edits BLOCK (--accept-skeleton-drift to override) |
| reverse contract | ha-review prepare | Declared-but-unimplemented endpoints (missing_declared_endpoints) |
| loop-escape guard | ha-verify record | 3rd FAIL of the same task blocks the loop (--force-continue) |
| design cross-section | ha-design commit | error_ux↔errors codes / screen APIs↔interface.http / blank Auth cells (design_findings) |
🎭 Agents
| Role | Responsibility |
|---|---|
| Architect | DB / API / auth / state-flow design in skeleton |
| Designer | UI / UX / component tree / state management design |
| Orchestrator | Task decomposition, dependency graph, phase management |
| Backend Coder | Python / FastAPI / CLI implementation |
| Frontend Coder | React / TS web implementation (web only — mobile delegated to mobile_coder_*) |
| mobile_coder_rn | React Native + Expo (Expo Router · Zustand · NativeWind) |
| mobile_coder_flutter | Flutter + Dart (Riverpod · go_router · drift · Material3) |
| mobile_coder_android | Android Kotlin + Jetpack Compose (StateFlow · Room · Retrofit · Hilt) |
| mobile_coder_ios | iOS Swift + SwiftUI (@Observable · NavigationStack · CoreData/SwiftData · Keychain) |
| Reviewer | (v1 path — superseded by /ha-review skill: fp-check + LESSON + 7 hooks) |
| QA | (v1 path — superseded by /ha-verify + /ha-review) |
Each agent's rules live in backend/agents/<role>/CLAUDE.md — editable.
⚠️ Current limitations
- Windows-first testing — Linux / macOS designs are in place but CI matrix is not yet green on all OSes
- No LLM auto-learning yet — new LESSONs are added manually (auto-learning is on the roadmap)
- Second E2E underway — first (code-hijack, python-cli) completed; second (fastapi + react-vite monorepo) phase 1 done, phase 2 in progress
- gstack coupling — some gates assume gstack skills are available (standalone execution works, but full power requires gstack)
🗺 Roadmap
Phase 1–4 (completed): profile system · 7 /ha-* skills · 28 LESSONs · 10 quality gates · single-command install · /my-* legacy skills removed · v1 legacy code (SECTION_MAP / extract_section / fill_skeleton_template) removed · Orchestra v2 wiring
Phase 5 — v0.5.0 (completed, 2026-05-02): auto-fit skeleton — 6-axis interview answers (user_scale / data_sensitivity / team_size / availability / monetization / lifecycle) auto-activate fragments via required_when expressions. 30 standard sections, custom AST + parser + evaluator.
Phase 6 — v0.6.0 (completed, 2026-05-07): mobile expansion. 4 new profiles (react-native-expo · flutter · android-kotlin · ios-swift) + 4 new mobile_coder agents (Pydantic + system prompts + dispatch routing) + 3 new mobile.* fragments (navigation / build_config / lifecycle) + harness-global guidelines auto-loaded for external users (no <project>/docs/guidelines/ copy needed) + HARNESS_AI_HOME fallback for prompt_path resolution. iOS native is Windows-host friendly (SwiftLint + swift build dry-run; full xcodebuild deferred to macOS CI).
Phase 7 — v0.7.0 (completed, 2026-05-11): web + desktop profiles — nextjs (App Router · Server Actions · better-auth · Drizzle) · nestjs (TypeORM · class-validator · Passport JWT · GlobalExceptionFilter) · electron (Context Isolation · preload IPC · electron-updater · code signing). 3 new skeleton fragments (environments / error_ux / rate_limiting). State machine bug fixes (ha-review / ha-verify state guards). Cross-platform toolchain gate tests.
Phase 8 — v0.8.0 (completed, 2026-05-11): design defect fixes. 7 new infrastructure modules (capabilities / consistency / lessons / agent_matching / tasks_schema / skeleton_hash / skeleton_stale). 4 new HarnessPlan frontmatter fields. harness migrate-plan CLI. 220+ regression tests (541 → 761). Mobile-only false-positive / false-negative fixes. Fractional task ID guard. Discovered via챙겼니 (RN/Expo) dogfooding.
Phase 9 — v0.9.x (completed, 2026-05-12): dogfood hardening + audit cleanup.
- v0.9.0: 11 defects from챙겼니 dogfood fixed —
harness migrate-skeleton-hash+harness analyze-failureCLI, RN bun test, ha-review/ha-verify record gate, ha-build state machine + atomic writes, file_structure drift audit. +105 regression tests (761 → 866). - v0.9.1:
harness graphCLI backfill — tasks.md → Mermaid dependency graph (was documented in v0.8.0 but not implemented). +4 tests (866 → 870). - v0.9.2: mirror sync (repo ↔
~/.claude5-file drift), profile hardening (LESSON-STYLE-001, whitelist additions), spec-code gap closure (G1 ha-deepinit augment-plan · G2 ha-verify integrity auto-run · G3 ha-build git WARN). +23 tests (870 → 893).
Phase 10 — v0.10.0 (completed, 2026-05-15): HITL Gate. Human-locked sections (requirements / user_journey / view.screens) enforced via PreToolUse hook. PlanManager.freeze() one-way gate. /ha-design HITL interview (5 AI candidates → user pick). /ha-build frozen-status gate. /ha-review extract-lesson auto-appends to Pending Lessons. /ha-log micro skill (worklog append + subprocess auto-append). harness migrate-v10 CLI. ChatDev / aider / CrewAI gap closed. +39 tests (893 → 939).
Phase 11 — v0.11.0 (completed, 2026-06-10): Design Integrity & Intent Capture. Full-system review (prompt audit + parallel code/architecture review agents) → ID-keyed consistency checker, 5 fail-open fixes, skeleton drift gate, per-section hashes for deterministic rebuild derivation, reverse contract validation, loop-escape guard, /ha-ship last mile. Intent-capture batch from dogfood feedback ("works, but not what I meant"): Intent Echo, per-feature Given/When/Then acceptance criteria, behavioral walkthrough gates, vague-word scan, adversarial self-critique. Senior handoff notes across 9 agent prompts. 3-way fragment title sync test (caught 2 live drifts on first run). GATES.md registry. Late additions: canonical section insertion (user_journey no longer dangles after notes), fake-FAIL guard for mis-matched profile cwd, harness validate 0/0, weak-model prompt diet (checklists→≤7 invariants, ha-design 519→391 lines with an execution progress table), first full LESSON auto-learning cycle (LESSON-029). +55 tests (939 → 994).
Phase 12 — v0.12.0 (completed, 2026-06-12): runtime smoke gate + default guidelines. /ha-smoke — top of the validation ladder: catches builds where test/lint/type all pass but the app doesn't start. exit-mode (exit 0 = PASS) / URL-readiness probe with process-tree cleanup, recorded as verify_history step=smoke (advisory, zero schema change) + optional toolchain.smoke profile field. Untracked-file scan bypass closed — freshly written files now join the /ha-build security gate and /ha-review scans via synthesized pseudo-diff. cp949 decode crashes root-fixed (6 subprocess sites). Default guidelines for electron / nextjs / nestjs (11 files — kalpie-lineage rules validated in sosel dogfooding, re-exported). ha-design locked_section_status backported (mirror→repo spec-code gap caught by full mirror hash audit). +23 tests (1015 → 1038).
v1.0.0 backlog:
- Live LESSONS auto-learning (ha-review repeated pattern → LESSON candidate)
- Multi-provider (Gemini / OpenAI backend) —
providers/gemini_*.pyfoundation in place, full validation pending - macOS GitHub Actions CI for iOS native (
xcodebuildtest/build) - Cost tracking (per-agent token / USD accumulation)
- Claude Code plugin manifest distribution
- Vector memory (CrewAI-style) — per-project LESSON embedding
- Execution sandbox (OpenHands-style) — isolated subprocess environment
ha-smokeextensions — declared-endpoint liveness sweep + user_journey browser smoke (GWT acceptance criteria as checklist). Core runtime launch gate shipped in v0.12.0/ha-export— read-only 기술명세서 / 화면설계서 / 페르소나 renders from skeleton (single source of truth preserved)
🧱 Tech stack
- Language: Python 3.12
- Server: FastAPI + WebSocket (port 3002)
- Package manager: uv
- Agent execution: Claude CLI subprocess (swappable — Gemini / local LLM)
- State:
docs/harness-plan.md(YAML frontmatter) +.orchestra/JSON (no DB) - Tests: 948 backend pytest + 12 install-snapshot assertions (0 regressions)
- Type check: pyright 0 errors on
src/ - Gate coverage (self-test): 7 of the 10 gates measured on 35 fixtures (positive / negative) → precision 100% / recall 100% / accuracy 100%. The other 3 are covered separately —
auth-guardbytest_security_hooksunit tests,test-distribution+skeleton-integrityby filesystem-level pytest fixtures. Details: gate-coverage.md - Latency (30-iter median, no LLM calls): profile detect ~5 ms, skeleton assemble <1 ms,
harness validate~150 ms,harness integrity~104 ms. Details: benchmarks/ - v2 infrastructure:
profile_loader,skeleton_assembler,plan_manager,harnessvalidation CLI
📂 Directory layout
harness/              Profile / template / CLI sources ─┐
skills/               ha-* skills + _ha_shared         ├─ install.sh → ~/.claude/
install.sh/ps1        Install + manifest               ─┘

backend/
  agents/<role>/CLAUDE.md     11 agent system prompts (editable)
  agents.yaml                 provider / model / timeout
  docs/shared-lessons.md      28 LESSONs
  src/orchestrator/           profile_loader / skeleton_assembler /
                              plan_manager / security_hooks / runner
  tests/                      948 pytest + skills/ regression guards

docs/
  ARCHITECTURE.md             System structure — read this first
  decisions/                  ADRs (five so far)
  benchmarks/                 Latency + gate coverage + dogfooding catches
  e2e-reports/                Dogfooding evidence
🛠 Development
cd backend
uv sync
uv run pytest tests/ --rootdir=.      # 948 tests
uv run ruff check src/                 # 0 errors
uv run pyright src/                    # 0 errors
uv run python -m src.main              # dashboard server (port 3002)
Install-script regression test:
./tests/install/test_install_snapshot.sh # 12 assertions
Harness schema validation:
python harness/bin/harness validate                 # 50 files, 0 errors
python harness/bin/harness integrity --project .    # skeleton ↔ FS integrity
python harness/bin/harness graph docs/tasks.md      # tasks.md → Mermaid dependency graph
python harness/bin/harness migrate-plan docs/harness-plan.md --apply  # legacy plan migration
python harness/bin/harness migrate-skeleton-hash docs/harness-plan.md --apply  # skeleton hash migration
python harness/bin/harness analyze-failure          # classify build failure + suggest fix
Gate coverage benchmark:
python scripts/gate_benchmark.py # 35 fixtures, exits 1 on any miss / false alarm
📚 Documentation
| Document | Contents |
|---|---|
| ARCHITECTURE.md | System structure · profiles · skeleton · gates (read first) |
| docs/decisions/ | Architecture Decision Records (5 ADRs) |
| docs/e2e-reports/ | E2E reports — dogfooding evidence (code-hijack completed, ui-assistant in progress) |
| docs/benchmarks/ | Performance benchmarks + gate coverage (35 fixtures, 100%) + LESSON↔gate dogfooding tracing |
| CONTRIBUTING.md | Profile / LESSON / gate / skill contribution guide |
| CHANGELOG.md | Version history |
| SETUP.md | End-to-end install + run guide |
| TODOS.md | Planned improvements |
| backend/docs/shared-lessons.md | 28 past-mistake patterns |
| CLAUDE.md | Implementation rules (senior-production bar) |
| SECURITY.md | Vulnerability disclosure |
| CODE_OF_CONDUCT.md | Community conduct |
| docs/harness-v2-design.md | v2 redesign worklog (Korean-only, developer reference) |
License
MIT — see LICENSE.