
Skill Check Job Search
PranavMishra17/skill-check-JobSearch
Dossier diário de vagas tech + recrutadores, com filtros inteligentes e estética Disco Elysium
Ver no GitHubAgregador inteligente de vagas de IA/ML/LLM que funde múltiplas fontes (JobSpy, SimplifyJobs, Arbeitnow) em um único feed filtrado e pontuado. Executa como skill dentro do Claude Code, com dashboard estático que persiste em GitHub Pages e rastreia candidaturas via localStorage.
Instalação
npx convez-ai PranavMishra17/skill-check-JobSearch1 comando no terminal: detecta o formato do repositório (marketplace ou plugin avulso) e instala via Claude Code. Requer Node 18+ e o Claude Code instalado.
Métricas
Casos de uso
- Monitorar vagas de IA/ML/LLM em múltiplas plataformas simultaneamente
- Filtrar automaticamente por critérios (visa, experiência, setor)
- Rastrear candidaturas e contatos com recrutadores em um único lugar
- Construir um histórico persistente de oportunidades e atividades
Veredito

Solução técnica sofisticada para busca de emprego em IA, com arquitetura multi-source e persistência inteligente. Requer setup em Claude Code + GitHub Pages, mas entrega valor real ao consolidar fontes dispersas com scoring automático.
README
A tradução para o português deste README ainda está na fila.
skill-check-JobSearch
A two-headed daily dossier of job listings and the humans hiring for them — wrapped in a Disco Elysium aesthetic and run from Claude Code.
/job-search · /hire-search
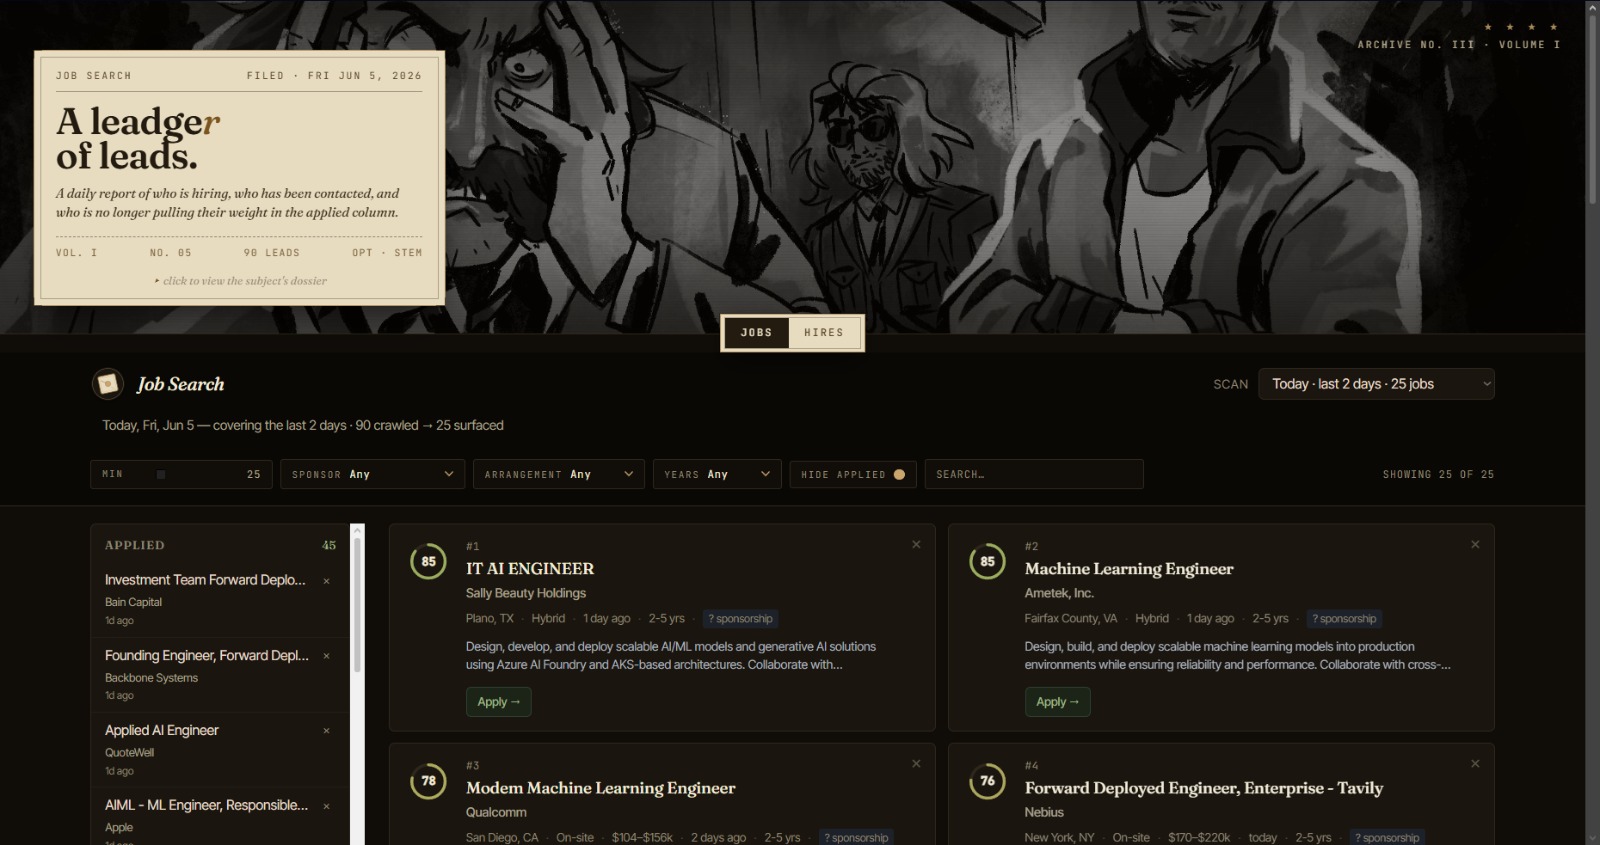
"There is a particular cruelty in a job board that returns nothing on a Thursday."
Live preview: the static dashboard auto-deploys to GitHub Pages on every push that touches jobs_ui/. After you push this repo, GitHub Pages will serve it at https://<your-user>.github.io/skill-check-JobSearch/. The hero label is clickable — opens a dossier modal so visitors understand which profile and preferences the agent is filtering against.
This is a personal command-line + browser-dashboard rig. Two slash commands run inside Claude Code, each fan out across job-board sources, score the results against your profile, and append a new session to a static HTML dashboard you open in your browser. The HTML never changes between runs — only the underlying data.js / hires.js files grow.
/job-search runs a multi-source local crawler by default — free, no API keys. It fuses four sources into one normalised feed:
- JobSpy — Indeed, Google Jobs, Glassdoor (LinkedIn opt-in). 17 AI/ML/agentic/founding/MLOps/research search terms.
SimplifyJobs/New-Grad-Positions— daily-updatedlistings.json, AI-filtered.speedyapply/2026-AI-College-Jobs— daily AI/ML new-grad markdown table.- Arbeitnow — free public API, AI-filtered.
/hire-search uses two LinkedIn-focused Apify actors. Apify is also kept as a fallback for /job-search via --apify for ATS-direct coverage (Workday / Greenhouse / Ashby / Lever) when needed.
What it does
/job-search [Nd] — fuses JobSpy + SimplifyJobs + speedyapply + Arbeitnow into a single feed of AI / LLM / ML / Founding-Eng / Forward-Deployed roles posted in the last N days. Filters out roles that explicitly close the door on visa sponsorship, anything senior/staff/principal, 4+ YoE requirements, defense / clearance-gated work, and dedups against everything you've already seen (both intra-run and against past sessions). Survivors are scored 0–100, written to jobs_ui/data.js, and rendered as cards in jobs_ui/index.html. Add --apify to fall through to the prior Apify-actor path for ATS-direct coverage.
/hire-search [Nd] [scope] — crawls LinkedIn for (a) recruiters at AI/ML companies and (b) public "we are hiring" posts (still via Apify — the apt_marble actors are free-tier-friendly). Decodes LinkedIn activity IDs to compute post age and drops anything older than the requested window. Cross-references companies against the open positions in your job-search history (matches get a badge + score boost). Surfaces both kinds in one ranked list in jobs_ui/hires.html.
Both interfaces share a sidebar with Applied / Contacted (top) and Dismissed (bottom, collapsed) that persists in localStorage. Apply / Open-profile auto-marks the entry and removes it from the main grid. The card you just clicked vanishes into the sidebar; the next lead steps forward.
Setup
1. Prerequisites
| Python | 3.10+ | for the crawler + scoring scripts |
| Claude Code | Install | runs the slash commands |
python-jobspy | pip install -U python-jobspy | the primary job crawler — free, no API key |
| Apify account (optional) | Free tier OK; token at apify.com/account/integrations | only needed for /hire-search and the /job-search --apify fallback |
2. Clone
git clone https://github.com/<you>/<repo-name>.git
cd <repo-name>
The repo's tree:
.
├── README.md
├── CLAUDE.md                      project memory for Claude Code
├── jobs_ui/                       browser dashboard (open this in a browser)
│   ├── index.html                 Jobs page — never regenerated
│   ├── hires.html                 Hires page — never regenerated
│   ├── data.js                    window.JOB_SESSIONS = [...]
│   ├── hires.js                   window.HIRE_SESSIONS = [...]
│   ├── favicon.svg                loaded-die icon
│   └── disco.jpg                  hero background
├── profile/                       your candidate inputs (read-only to the agent)
│   ├── RESUME.pdf
│   ├── PORTFOLIO.pdf
│   └── *.md
├── scripts/                       crawlers, scorer, audit tool — all Python
│   ├── crawl_all.py               multi-source orchestrator (default)
│   ├── crawl_jobspy.py            JobSpy-only crawler (single-source fallback)
│   ├── render_results.py          scoring + filtering + dedup + data.js write
│   ├── inspect_drops.py           per-bucket drop audit (debug tool)
│   └── hire_search.py             hire-search scorer + normaliser
└── .claude/
    ├── agents/                    sub-agent specs (documentation)
    └── commands/                  slash command runtimes
        ├── job-search.md
        └── hire-search.md
Personal state (your
state.json, past sessions, raw crawl JSON) stays at~/.job_search/outside the repo. The scripts read from / write to that directory by default — no path edits needed when you clone.
3. Install JobSpy
pip install -U python-jobspy
That's it for /job-search. No API keys, no accounts, runs entirely on your machine. The scripts in scripts/ use urllib from stdlib for everything else (GitHub fetches, Arbeitnow API).
3a. Tuning the title-scope filter
scripts/render_results.py has a TITLE_SCOPE list that decides which job titles to keep. After any crawl, run the audit tool to see what got dropped:
python scripts/inspect_drops.py \
  --dataset ~/.job_search/raw_jobs/<latest>.json \
  --window-days 3 --samples 5
It prints every drop bucket with sample items and the matched snippet. If you spot a false positive, add a substring to TITLE_SCOPE in scripts/render_results.py and re-run.
3b. (Optional) Install the Apify MCP server
Only needed if you want to run /hire-search or the /job-search --apify fallback. Skip this for a JobSpy-only setup.
claude mcp add apify --transport http \
  --url https://mcp.apify.com \
  --header "Authorization: Bearer <YOUR_APIFY_TOKEN>"
(Or use Apify's official MCP docs for stdio mode.)
Apify pitfall: if /job-search --apify returns "Maximum charged results must be greater than zero", raise the per-actor charge cap in console.apify.com → that actor → settings → Maximum charged results per run.
4. Drop your profile in profile/
Put your inputs anywhere under profile/ — the agent reads them once during bootstrap. Suggested files:
RESUME.pdf— current resumePORTFOLIO.pdf— public-facing portfolio<CURRENT_ROLE>.md— a deep-dive on your current job (what you're shipping, stack, scope)<PRIOR_ROLE>.md— deep-dives on prior roles (interview-grade detail)<PROJECT>.md— any side project you'd want surfaced when scoring
5. Bootstrap your state
The first run of /job-search walks you through a short questionnaire (salary floor / preferred, location, role titles in scope, dealbreakers, etc.) and writes:
~/.job_search/state.json
~/.job_search/sessions/
~/.job_search/raw_hires/
This state file is the source of truth — never commit it. Everything in this repo is templates and code; your personal data lives outside.
6. Configure preferences (optional)
You can hand-edit ~/.job_search/state.json to tune:
preferences.salary— floor / preferred / cappreferences.location— remote / hybrid / on-site weightspreferences.industries_avoid— defense, military, etc.preferences.dealbreakers— title regexes that auto-drop (senior / staff / etc.)preferences.crawl_sources— which Apify actors to use as primary / secondarypreferences.applied_or_tracking— companies to silently exclude from future scans
The slash command /job-search I applied to <Company> does this for you.
Daily use
/job-search             # JobSpy, 1-day window
/job-search 7d          # JobSpy, past week
/job-search 14d         # JobSpy, past two weeks
/job-search show me jobs from Cohere      # targeted single-company crawl
/job-search 7d --apify  # Apify fallback (ATS-direct coverage)
/job-search I applied to Anthropic        # state mutation only, no crawl
/job-search reset job history             # destructive — confirms first

/hire-search            # 14-day window, US AI scope
/hire-search 5d         # past 5 days
/hire-search 5d founding   # founding-engineer scope, past 5 days
/hire-search 7d india   # India scope
/hire-search remote
Cost. /job-search is $0 (JobSpy runs locally, no API). /hire-search is ~$1.00 per run on Apify FREE tier. /job-search --apify is ~$2.40 per 200-job crawl.
After each run, open jobs_ui/index.html (or hires.html) in a browser. The Scan dropdown lets you flip between past sessions. Filters persist in localStorage; Apply / Open-profile auto-moves the entry to the sidebar; the × on a card dismisses it.
Future: run from the dashboard itself
Status: proposed, not built. Scope only.
Right now /job-search and /hire-search are typed inside Claude Code. The dashboard is read-only. The next step is a tiny local server that lets you click a button in the browser and have the workflow run, refresh the data file, and re-render — without leaving the page.
Architecture
                     ┌──────────────────┐
       browser   ──► │  jobs_ui/*.html  │ ──► fetch('http://localhost:8123/run/job-search?args=7d')
                     └──────────────────┘                      │
                                                               ▼
                                                ┌────────────────────────────┐
                                                │  Flask / FastAPI server    │
                                                │  app.py  ~80 lines         │
                                                └────────────────────────────┘
                                                               │ subprocess.run
                                                               ▼
                                              ┌─────────────────────────────────┐
                                              │  claude -p "/job-search 7d"     │
                                              │  --output-format=stream-json    │
                                              └─────────────────────────────────┘
                                                               │
                                                               ▼
                                                    data.js / hires.js
                                                    (written by the script
                                                    the slash command runs)
                                                               │
                                                browser refreshes data.js  ◄────┘
Files to add (not present yet)
.
├── webapp/
│   ├── app.py                     ~80 lines, single endpoint per command
│   ├── requirements.txt           flask, python-dotenv
│   └── .env.example               APIFY_TOKEN, CLAUDE_BIN path
└── jobs_ui/
    └── run-controls.js            small script the HTML loads; renders Run buttons
Server endpoints (proposed)
| Method | Path | Body | What it does |
|---|---|---|---|
POST | /run/job-search | { "args": "7d" } | shells claude -p "/job-search 7d" --output-format=stream-json and streams progress to the client; returns when data.js has been written |
POST | /run/hire-search | { "args": "5d founding" } | same, for /hire-search |
POST | /run/applied | { "company": "Anthropic" } | thin wrapper for /job-search I applied to ... (state mutation, no crawl) |
GET | /healthz | — | returns 200 + Apify token presence |
Setup (when built)
cd webapp
pip install -r requirements.txt
cp .env.example .env             # fill in APIFY_TOKEN, CLAUDE_BIN
python app.py                    # starts at http://localhost:8123
Then open http://localhost:8123/jobs_ui/index.html (the Flask app also serves the dashboard so the browser fetch() request doesn't hit a CORS wall from file://).
Concerns to handle before shipping
- Auth. Anyone on localhost could fire a paid Apify crawl. A simple shared token in the
.env, validated on each request, is probably enough for a single-user local server. - Cost. Each
/job-searchis ~$2.40,/hire-searchis ~$1.00. Surface estimated cost on the button hover and add a--dry-runmode. - Concurrency. One workflow at a time. The server should reject a second
/run/*while one is in flight. - Streaming.
claude -p --output-format=stream-jsonemits NDJSON; pipe that to Server-Sent Events so the UI can show progress ("calling Apify… scoring… writing data.js…"). - Failure. If the subprocess exits non-zero, surface the last 50 lines of
claude's stderr in the UI.
What this doesn't solve
This is a personal local rig, not a hosted product. It still needs your machine running, with the Apify MCP server connected through Claude Code, with Python on path. For an "always fresh" dashboard with no machine running, the path is GitHub Actions cron (a workflow that runs render_results.py directly via Apify's REST API, no Claude Code, commits the new data.js back to the repo, GitHub Pages serves the HTML).
Customize for yourself
This repo ships with one person's profile and one set of preferences. To make it yours:
- Replace everything under
profile/with your own materials. - Delete
~/.job_search/state.jsonand run/job-searchto re-bootstrap. - Tweak the title strings in
jobs_ui/index.htmlandjobs_ui/hires.html(the Crimebook label has a hard-coded byline you'll probably want to change). - Optionally swap
disco.jpgfor an image you like better — keep the aspect ratio around 1.3:1 and the focal point near top-center.
The CSS palette lives in :root at the top of each HTML file. The Crimebook label assumes a warm-espresso bg; if you want a light theme, the label-on-image effect won't work the same way.
Architecture (one paragraph)
The whole rig avoids LLM dependency at run-time. The slash commands tell Claude which crawler to invoke (crawl_all.py by default, Apify on --apify) and with what parameters — but the actual scoring, filtering, dedup, and HTML-data writes are deterministic Python (render_results.py). Every source's output is normalised to the same Apify-shape JSON, so the scorer is unchanged across all paths. That means once you've worked out the parameters and the score weights for your profile, you can port the entire workflow off Claude Code onto a GitHub Action or a cron job without losing anything except the natural-language argument parsing.
                      ┌─────────────────────────┐
                      │  /job-search 7d         │  (Claude Code slash command)
                      └────────────┬────────────┘
                                   │
              ┌────────────────────┴────────────────┐
              │                                     │
              ▼ (default)                           ▼ (only with --apify)
  ┌────────────────────────────────┐   ┌──────────────────────┐
  │  crawl_all.py                  │   │  Apify MCP actor     │
  │  ├── JobSpy (Indeed/Google/    │   │  fantastic-jobs/…    │
  │  │   Glassdoor; LinkedIn opt)  │   │  (ATS direct)        │
  │  ├── SimplifyJobs/New-Grad     │   │  ~$0.012/job         │
  │  ├── speedyapply/AI-College    │   │                      │
  │  └── Arbeitnow API             │   │                      │
  │  $0, runs locally              │   │                      │
  └──────────┬─────────────────────┘   └──────────┬───────────┘
             │                                     │
             │  cross-source URL + (co,title) dedup │
             └───────────────────┬─────────────────┘
                                 ▼
                ~/.job_search/raw_jobs/<date>_<window>.json
                                 │  (unified Apify-shape JSON)
                                 ▼
                ┌─────────────────────────┐
                │  render_results.py      │  (scoring + dedup vs seen + filters)
                └────────────┬────────────┘
                             ▼
                jobs_ui/data.js  ←  jobs_ui/index.html reads
License
MIT — see LICENSE (add one before publishing).
Credits
- Hero image: Disco Elysium (ZA/UM, 2019). Used here under fair-use for personal aesthetic purposes; this repo claims no ownership.
- Fonts: Fraunces (Undercase Type), Inter Tight (Rasmus Andersson), JetBrains Mono.
- Primary crawler: JobSpy (Cullen Watson, Zachary Hampton — MIT). Scrapes Indeed, Glassdoor, Google, LinkedIn, ZipRecruiter.
- GitHub job aggregators (community-maintained, daily-updated):
SimplifyJobs/New-Grad-Positions,speedyapply/2026-AI-College-Jobs. - Free public APIs: Arbeitnow.
- Fallback /
/hire-searchactors on Apify:fantastic-jobs/career-site-job-listing-api,apt_marble/linkedin-hiring-posts-scraper,apt_marble/linkedIn-recruiter-scraper. - Built with Claude Code.