
engram — Memória Persistente para Claude Code
prajwalppv/engram
Memória local e inteligente para Claude Code — nada sai da sua máquina
Ver no GitHubMCP server que dá ao Claude Code uma memória local e permanente entre sessões. Armazena decisões, gotchas e convenções de forma consciente de papéis (engineer, PM, manager), com pruning automático e zero dados saindo da máquina. Essencial para manter contexto crucial em projetos de longa duração sem comprometer privacidade.
Instalação
npx convez-ai prajwalppv/engram1 comando no terminal: detecta o formato do repositório (marketplace ou plugin avulso) e instala via Claude Code. Requer Node 18+ e o Claude Code instalado.
Métricas
Casos de uso
- Recuperar decisões e constrains críticos em novas sessões de trabalho
- Evitar re-causar incidentes de produção através de gotchas armazenados
- Manter convenções de código e padrões de projeto consistentes ao longo do tempo
Veredito

engram resolve um problema real: Claude Code perde contexto a cada sessão. A implementação é sensata (local-first, sem auth, self-pruning) e a UX é direta — `/engram:recall` e amigos. Não é indispensável, mas economiza tempo material em projetos com histórico complexo e reduz risco de regressões.
README
A tradução para o português deste README ainda está na fila.
🧠 engram — give Claude Code a memory
Claude Code forgets everything when a session ends. engram fixes that — privately, on your machine, and it gets sharper over time.
engram is a Claude Code plugin that remembers the durable facts from each session (decisions, gotchas, conventions) and recalls the relevant ones the moment you start working again. It's role-aware (it remembers differently for an engineer vs a PM vs a manager, learned automatically), it keeps itself sharp with bonsai-style pruning, and it self-improves from your feedback.
🔒 Absolute privacy by construction: everything is stored locally on your own laptop. No server, no account, no auth, no telemetry — zero bytes leave your machine.
Install (Claude Code)
/plugin marketplace add prajwalppv/engram
/plugin install engram@engram
Restart Claude Code. That's it — on a platform with a prebuilt binary you need nothing
else installed (no Python, no uv). Then just work: engram recalls your repo's memory at
session start and captures as you work. Commands: /engram:recall,
/engram:remember, /engram:howto, /engram:status, /engram:prune, /engram:optimize.
A future, opt-in, sanitized export could let teammates share selected learnings; it does not exist yet and is never automatic.
Demo
Last sprint you fought through a prod incident, locked in some decisions, and set conventions. Weeks later you start a new feature in a brand-new session — blank-slate Claude. You ask in your own words, and engram surfaces each crucial prior fact by meaning, fully on-device — including the gotcha that stops you re-causing the incident:
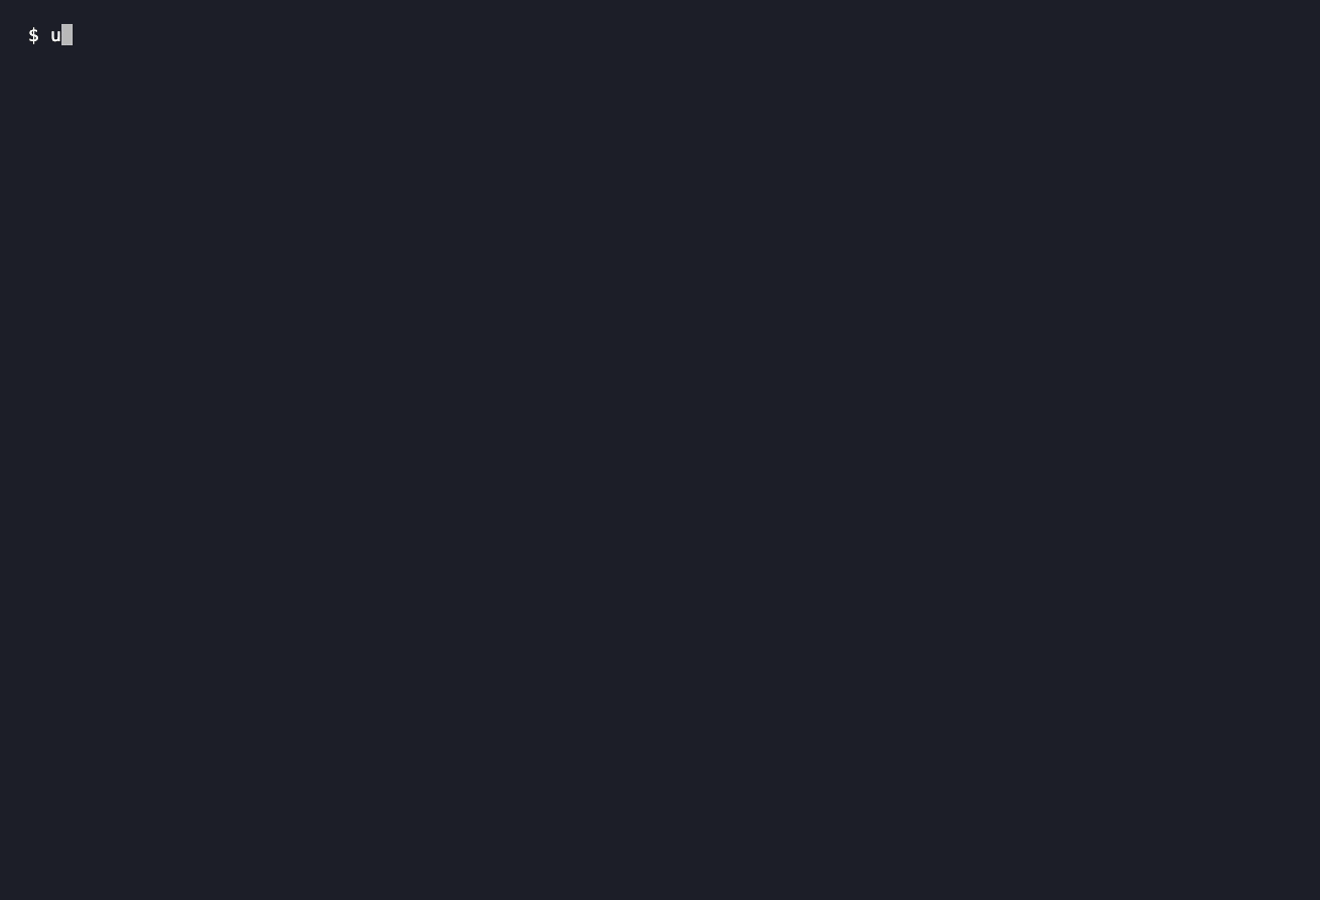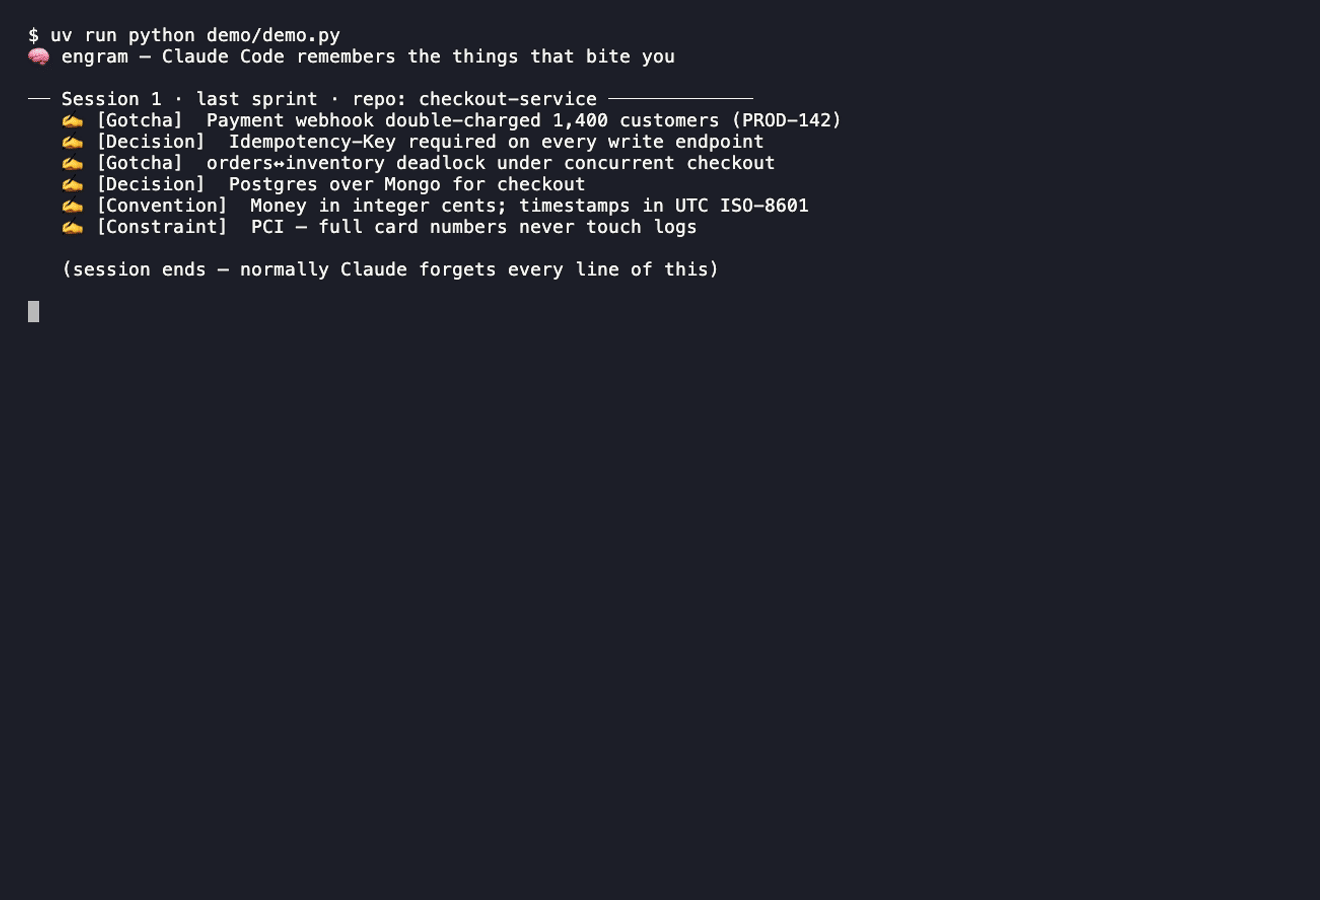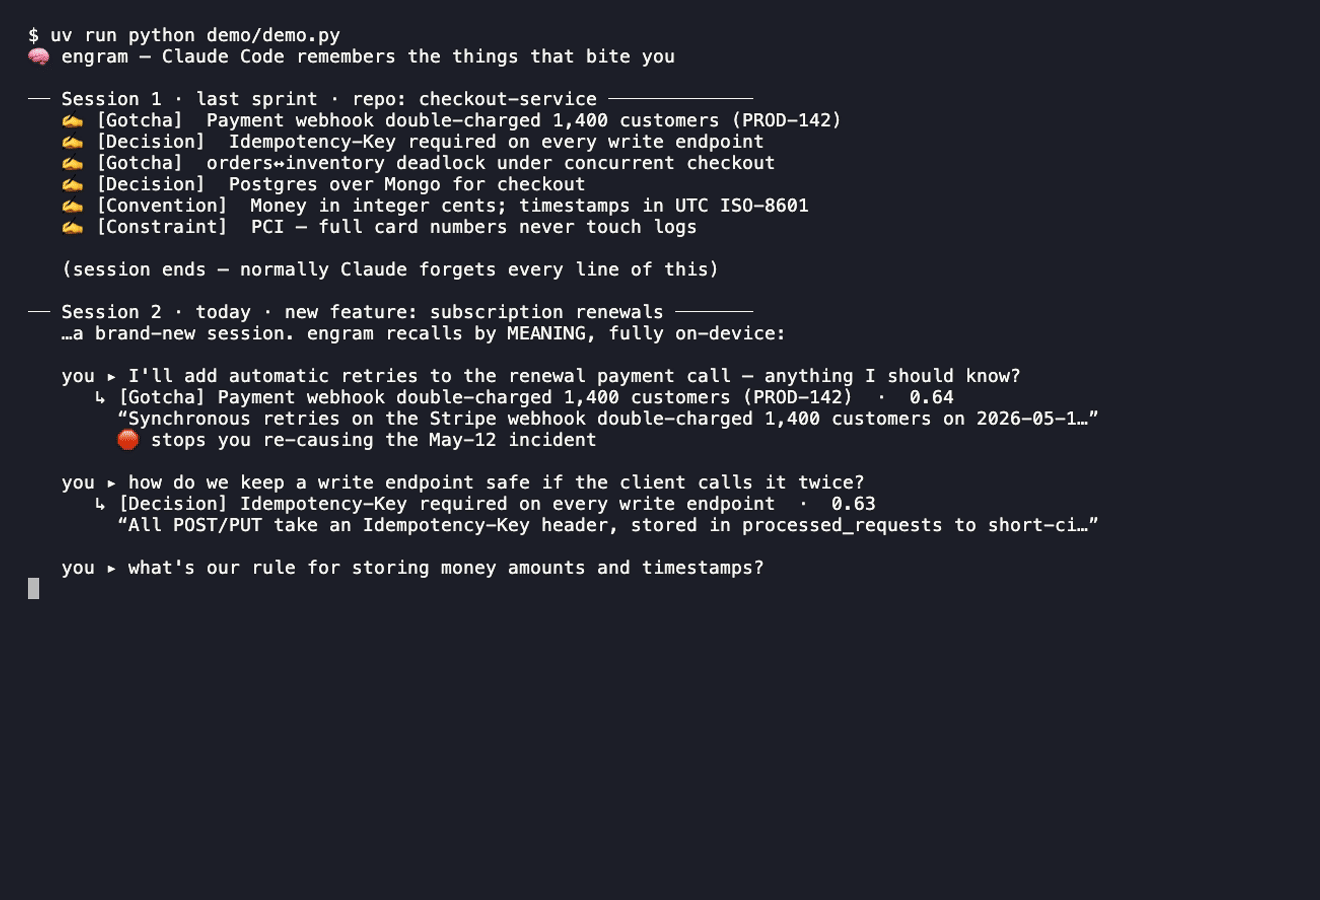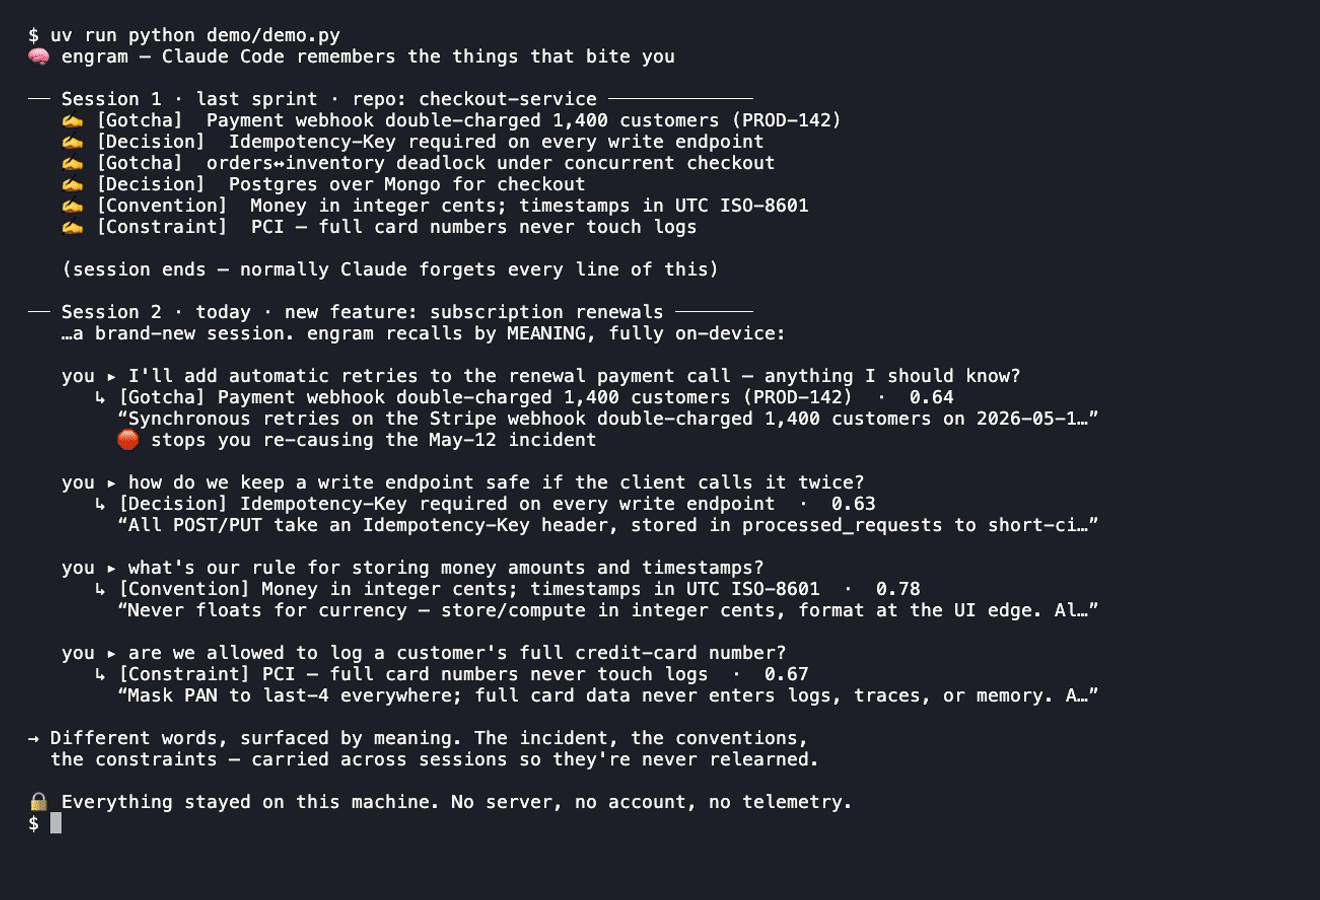
🧠 engram — Claude Code remembers the things that bite you

── Session 1 · last sprint · repo: checkout-service ─────────────
   ✍️  [Gotcha]      Payment webhook double-charged 1,400 customers (PROD-142)
   ✍️  [Decision]    Idempotency-Key required on every write endpoint
   ✍️  [Gotcha]      orders↔inventory deadlock under concurrent checkout
   ✍️  [Decision]    Postgres over Mongo for checkout
   ✍️  [Convention]  Money in integer cents; timestamps in UTC ISO-8601
   ✍️  [Constraint]  PCI — full card numbers never touch logs

   (session ends — normally Claude forgets every line of this)

── Session 2 · today · new feature: subscription renewals ───────
   …a brand-new session. engram recalls by MEANING, fully on-device:

   you ▸ I'll add automatic retries to the renewal payment call — anything I should know?
      ↳ [Gotcha] Payment webhook double-charged 1,400 customers (PROD-142)  ·  0.64
        “Synchronous retries on the Stripe webhook double-charged 1,400 customers on 2026-05-12. NEVER…”
        🛑 stops you re-causing the May-12 incident

   you ▸ how do we keep a write endpoint safe if the client calls it twice?
      ↳ [Decision] Idempotency-Key required on every write endpoint  ·  0.63
        “All POST/PUT take an Idempotency-Key header, stored in processed_requests to short-circuit…”

   you ▸ what's our rule for storing money amounts and timestamps?
      ↳ [Convention] Money in integer cents; timestamps in UTC ISO-8601  ·  0.78
        “Never floats for currency — store/compute in integer cents, format at the UI edge…”

   you ▸ are we allowed to log a customer's full credit-card number?
      ↳ [Constraint] PCI — full card numbers never touch logs  ·  0.67
        “Mask PAN to last-4 everywhere; full card data never enters logs, traces, or memory…”

→ Different words, surfaced by meaning. The incident, the conventions, the
  constraints — carried across sessions so they're never relearned.

🔒 Everything stayed on this machine. No server, no account, no telemetry.
(The transcript above is the same run, for readers with images off.)
Run it yourself (throwaway store, ~15s): uv run python demo/demo.py.
Re-record the GIF with VHS:
vhs demo/engram.tape → writes docs/demo.gif.
How it works
- Memory is a local knowledge graph of markdown notes (wikilinks + backlinks), searched semantically (local embeddings, no cloud).
- A Claude Code plugin captures and recalls memory across the session lifecycle —
not just at the end, so nothing is lost to compaction or an abrupt terminal close:
SessionStart→ recall context relevant to your current repo/task (also after a compaction).Stop(end of every turn) → incremental capture, throttled so it only distills once a few new turns accumulate.PreCompact→ flush before compaction — captures detail right before Claude summarizes it away.SessionEnd→ final flush of anything remaining.- Every
SessionStartalso kicks off (detached, non-blocking) a safe auto-maintenance pass: bonsai-prune stale clusters (archived, recoverable, bounded, lifelines preserved) and self-tune the prune fraction from the resurrection signal — so the store keeps itself sharp without a manual command. (SessionStart is the trigger becauseSessionEnddoesn't reliably fire.)
- Every capture is incremental and idempotent: a per-session high-water mark means each trigger folds only the new delta into memory, and content-hash + semantic dedup prevent duplicates. See docs/ARCHITECTURE.md.
- A role profile (SWE / PM / EM / …) shapes what gets extracted and recalled. Your role is inferred as soft weights from your sessions and is overridable.
- An always-on layer learns your standing preferences ("always use uv", "never force-push", "I prefer terse answers") and applies them every session — see below.
- A feedback loop runs in two tiers. Automatic: recall biases toward
memories that proved useful (used, or whose body you fetched) and lets unused
noise decay, the bonsai prune fraction self-tunes from its own resurrection rate,
and these run on their own at SessionStart. Gated/manual: the LLM-cost
extraction-prompt search is an explicit, eval-gated tool (
/engram:optimize,memory_optimize_prompt) that only accepts a new prompt if it beats the current one on a held-out split — never an automatic, unsupervised rewrite.
Preferences — the always-on layer
engram has different memory horizons. Most memory is retrieved on relevance (decisions, gotchas, conventions). But standing preferences are global rules that should apply to every session — so they're delivered automatically, two ways (a deliberate hybrid):
- Persistent: engram maintains a managed block in your project's
CLAUDE.md(only ever touching content between its own markers — your file is otherwise untouched). - Immediate: they're also injected at
SessionStart, so a freshly-learned preference applies right away.
It learns them automatically when you state a standing rule ("from now on…",
"always…", "I prefer…") — no command needed — and they're pruning lifelines
(never auto-removed). Review and remove them anytime with /engram:status
(→ memory_forget). One-tap undo; fully recoverable.
Memory horizons & scope
engram models memory along two orthogonal axes — which is what keeps recall sharp instead of a noisy everything-bucket:
Horizon — the kind of memory (each with its own capture, recall, and decay):
| Horizon | Holds | Lifetime |
|---|---|---|
| working | the current task's "where was I" | hours — TTL'd; injected only on resume |
| episodic | what happened (sessions, incidents) | weeks — consolidated by bonsai |
| semantic | durable facts (decisions, gotchas, conventions) | long — vigor-scored |
| procedural | runbooks / "how we do X" | long — durable, supersede-with-history |
| preference | standing rules about you | ~permanent — lifeline, always-on |
Scope — where it applies: global → role → area → repo → session. Recall is
applicability-filtered, so one repo's conventions never leak into another, and a
preference can be global ("always use uv") or repo-specific. Precedence is
most-specific-wins, and a memory can supersede ones it replaces. Working
scratch decays in a day; preferences effectively never — pruning is horizon-aware.
Procedural runbooks are auto-captured when you spell out a process with steps (or
save one with /engram:howto); working memory needs no setup.
Capture stays sharp. Auto-capture restates the same fact across sessions, so engram merges near-duplicates: a new memory that restates an existing one (same type, high body overlap — or high semantic similarity) is appended into that node instead of spawning a separate near-dup. Combined with the feedback loop and bonsai pruning, the graph compresses noise rather than accumulating it.
Capture builds the graph. A new memory is also auto-linked to its related neighbors (the band below near-duplicate, cross-type on purpose — a Decision links to the Gotcha about the same thing), so the wikilink graph is load-bearing and graph-expansion recall has real edges to traverse, instead of a pile of orphans.
Recall, privacy & provenance
- Recall that learns (the feedback loop). engram tracks which recalled memories were actually acted on — explicitly marked used, or whose body you fetched after the compact index — and biases future recall toward what's proven useful while letting recalled-but-never-used noise decay out of the bonsai. The memory gets sharper with use; stateless compress-and-inject tools don't.
- Token-frugal recall (progressive disclosure).
memory_recallreturns a compact index — each hit carries a boundedsnippetand acreateddate, not the full body. The agent judges relevance from the index and pulls full bodies withmemory_readonly when it needs them. Cheap recall, no token blowups. - Temporal correctness + auto-contradiction. Capture shows the LLM the
project's related existing memories; when a new fact makes one obsolete or
false (a reversed decision, a changed convention), the LLM marks it
supersedesand engram retires the old one automatically — kept but stamped with a dated back-reference (superseded_by/superseded_on), recoverable, never deleted (the mem0/Zep "invalidate, don't delete" model). Recall surfaces the current fact; history stays traceable. Conservative by design + guarded to only retire memories actually shown to the model.ENGRAM_DETECT_CONTRADICTIONS=falseto opt out. <private>redaction. Anything you wrap in<private>…</private>is stripped before any capture — it never reaches the store, summarizer, index, or working memory (and an unclosed tag fails safe). On by default;ENGRAM_REDACT_PRIVATE=falseto opt out.- Provenance —
/engram:why(and thememory_whytool). Ask why a recalled fact exists: its origin (when/session/role), whether it's been superseded, and its graph links — so you can trust it or discard it. - Correct or forget anything.
memory_forgetremoves any memory (not just preferences) by id, title, or path — archived and fully recoverable, and dropped from the index immediately. Pair it withsupersedeto replace a fact while keeping its history.
Architecture
Memory is captured at multiple points in the session lifecycle and recalled at the start of the next one — all on-device. (full diagrams + component view →)
flowchart TD
    subgraph CC["Claude Code session"]
        S0(["SessionStart"])
        STOP(["Stop · every turn"])
        PC(["PreCompact"])
        SE(["SessionEnd"])
    end
    S0 -->|recall| R[["recall: memory for this repo"]]
    R -->|additionalContext| CC
    STOP -->|"capture (throttled)"| CAP
    PC -->|"capture (forced flush)"| CAP
    SE -->|"capture (forced flush)"| CAP
    CAP["capture_delta()<br/>new events since high-water mark"]
    CAP --> HWM[("high-water mark<br/>.state/sessions")]
    CAP --> SUM["summarize → typed, linked nodes"]
    SUM --> STORE[("local store<br/>markdown graph + index")]
    STORE -.->|next session| R

    classDef hook fill:#1f2937,stroke:#60a5fa,color:#e5e7eb;
    classDef work fill:#0f172a,stroke:#34d399,color:#e5e7eb;
    classDef data fill:#111827,stroke:#fbbf24,color:#e5e7eb;
    class S0,STOP,PC,SE hook;
    class R,CAP,SUM work;
    class HWM,STORE data;
Status
Working, single-user, local-only — with a real memory model:
- Multi-horizon memory — working · episodic · semantic · procedural · preference, each with its own capture, recall, and decay (see Memory horizons & scope).
- Always-on preferences — learned standing rules, delivered every session
(hybrid: a managed
CLAUDE.mdblock +SessionStartinjection). - Scope ladder + precedence (
global → role → area → repo → session) so memory applies where it should and a specific rule overrides a general one. - Semantic recall on by default (local embeddings); automatic text fallback.
- Durable multi-trigger capture (Stop / PreCompact / SessionEnd) — survives compaction and abrupt exits.
- One stable store at
~/.engram/store, shared across every editor/host, with safe auto-migration on update. - Self-healing index + a recall metric — the semantic index repairs drift
automatically (cross-process-safe writes), and
memory_evalreports recall@k/MRR so quality is measured, not assumed. - Hybrid recall — dense embeddings fused with lexical (term-overlap) ranking + graph-neighbor expansion, so exact tokens (error codes, flags, paths) are recalled, not just semantic matches. Measured +exact-term recall@5 0.80→1.00 on a real store.
- Proactive guardrails — at the moment you run a risky tool (
Bash/Edit/…), engram surfaces a relevant remembered gotcha/decision as non-blocking advice, so Claude doesn't repeat a known mistake. Conservative + per-session dedup;ENGRAM_PROACTIVE=0to disable. - Self-maintaining — at SessionStart engram runs a safe, bounded maintenance pass on its own: bonsai-prune stale clusters (archived/recoverable, lifelines preserved) and self-tune the prune fraction from its resurrection rate. The deep self-improvement (extraction-prompt search) stays a gated, eval-checked tool, not an unsupervised rewrite.
- Eval-gated — recall, guardrail precision/silence, preference detection, role inference, pruning safety, and extraction all run as CI gates, so quality regressions fail the build, not just crashes.
Requirements
- uv for the full semantic experience. On first run, the plugin pulls fastembed + a small embedding model (~160 MB once, from PyPI + HuggingFace), then runs fully offline. Nothing is committed to the repo.
- No uv? Still works. The plugin falls back to a committed self-contained binary (~16 MB on macOS arm64, ~36 MB on Linux x86_64) that gives fast text recall with zero setup.
Either way, everything stays on your machine.
Self-contained binary (the no-uv text fallback)
The plugin runs via scripts/engram-launch, which prefers uv (semantic) and
falls back to the bundled binary (text). Build the binary per platform (ideally CI):
bash scripts/build_binary.sh # → bin/<os>_<arch>/engram (~16–36 MB, PyInstaller)
It's lean by design — the heavy embedding deps are pulled on demand via uv, never bundled or committed.
Install as a Claude Code plugin (the few-click path)
From the public marketplace repo (or any git repo, e.g. a private one for a team):
/plugin marketplace add prajwalppv/engram
/plugin install engram@engram
Or from this local checkout, to try it now:
/plugin marketplace add /Users/vibestar/dev/engram
/plugin install engram@engram
Then restart Claude Code. The plugin:
- spawns the local
engram-mcpserver (stdio) over a single, stable per-user store at~/.engram/store(shared across every editor/host, so your memory is never fragmented); - adds lifecycle hooks that recall memory at SessionStart and capture it incrementally at Stop / PreCompact / SessionEnd (durable across compaction and abrupt exits);
- adds commands:
/engram:recall,/engram:remember,/engram:status.
Zero-click for a shared repo: commit a .claude/settings.json with
extraKnownMarketplaces + enabledPlugins so teammates get it on clone+trust.
Staying up to date (auto-updates)
You shouldn't have to babysit updates. How updates reach you:
- Installed from the community marketplace (
engram@claude-community): updates are automatic — Anthropic-managed marketplaces have auto-update on by default, so new releases land silently at startup (you'll get a/reload-pluginsnudge). - Installed from this repo (
engram@engram): third-party marketplaces default to manual updates. Turn auto-update on once via/plugin→ Marketplaces → engram → Enable auto-update, or add"autoUpdate": trueto the marketplace entry insettings.json(see the team block below). To update by hand instead, run both steps — the marketplace cache lags the repo, so the plugin update alone won't see a new release:
Either way, restart Claude Code afterward — an update is staged, not live, until restart.claude plugin marketplace update engram # 1. pull new releases into the cache claude plugin update engram@engram # 2. then bump the installed plugin - For a team: drop this in your repo's
.claude/settings.jsonand everyone gets engram auto-installed and auto-updated on clone + trust — no manual steps (seeexamples/team-settings.json):{ "extraKnownMarketplaces": { "engram": { "source": { "source": "github", "repo": "prajwalppv/engram" }, "autoUpdate": true } }, "enabledPlugins": { "engram@engram": true } }
Updates are safe across the store-path change: on first run a new version
auto-migrates any legacy store into ~/.engram/store (copy-only, never
destructive), so an update never appears to lose your memory.
Semantic recall (default)
Semantic recall is on by default — local embeddings via fastembed (ONNX, no
PyTorch). The deps come from PyPI and the model from HuggingFace, pulled once on
first use (~160 MB), then it's fully offline. No cloud, no API. To force plain
keyword recall instead, set ENGRAM_SEARCH_BACKEND=text.
Dev
uv sync --extra dev
uv run pytest -q
Configuration (env, prefix ENGRAM_)
| Var | Default | Meaning |
|---|---|---|
ENGRAM_STORE_DIR | ~/.engram/store | Local memory store. |
ENGRAM_SEARCH_BACKEND | semantic | semantic (local embeddings) or text. |
ENGRAM_ROLE | auto | Pin a role (swe/pm/em) or infer. |
ENGRAM_REPO | (cwd) | Pin the repo label. Set this when you edit a project from a different directory (e.g. a plugin), so memories aren't mis-scoped to the cwd's repo. |
ENGRAM_EMBEDDING_MODEL | BAAI/bge-small-en-v1.5 | fastembed model. |
ENGRAM_CAPTURE_ON_STOP | true | Incremental end-of-turn (Stop) capture. Set false to capture only at PreCompact/SessionEnd. |
ENGRAM_CAPTURE_EVERY_TURNS | 13 | Min new user turns before a Stop capture fires (lower = more durable + more frequent distillation; higher = less overhead). PreCompact/SessionEnd flush the remainder regardless. |
ENGRAM_DETECT_PREFERENCES | true | Auto-learn standing preferences from your sessions. |
ENGRAM_DETECT_CONTRADICTIONS | true | At capture, let the LLM mark a new fact as superseding an existing one it makes obsolete (retire-with-history, recoverable). |
ENGRAM_REDACT_PRIVATE | true | Strip <private>…</private> spans before any capture (store, summarizer, index, working memory). |
ENGRAM_MANAGE_CLAUDE_MD | true | Maintain engram's managed preferences block in CLAUDE.md. |
ENGRAM_CLAUDE_MD_PATH | project ./CLAUDE.md | Where the managed block is written (set to ~/.claude/CLAUDE.md for truly global). |
ENGRAM_DETECT_PROCEDURES | true | Auto-capture runbooks (procedural memory) from spelled-out step lists. |
ENGRAM_WORKING_MEMORY | true | Track per-session "where was I" and inject it on resume. |
ENGRAM_WORKING_TTL_HOURS | 18 | Resume window for working memory; older snapshots are pruned. |
ENGRAM_AUTO_MAINTAIN | true | Run safe self-maintenance (bonsai prune + prune-param tuning) automatically at SessionStart (detached, non-blocking). |
ENGRAM_AUTO_PRUNE | true | Include bonsai pruning in auto-maintenance (archived/recoverable, bounded, lifeline-safe). |
ENGRAM_MAINTAIN_INTERVAL_HOURS | 0 | Min hours between maintenance runs. 0 = every SessionStart; raise to throttle on very large stores. |
ENGRAM_AREA | (unset) | Optional cross-repo domain (e.g. python) for the scope ladder. |
Design seams
core/— vendor-neutral, no MCP imports.roles/— the Profile seam applied to people; discoverable via theengram.rolesentry-point group.core/search_backends.py— lazySemantic(fastembed, default) +Textfallback.core/scoping.py+ thehorizonfield — the memory-model seam (horizon × scope), so new horizons or scope levels drop in without touching the core.- A dormant
visibility/exportseam (separate from the livescopeladder) so future opt-in team sharing is a flip, not a rewrite.