
Brainstack
mustafa-bharmal-shipveho/brainstack
Memória auditável para agentes de código com versionamento git e controle humano
Ver no GitHubServidor MCP que fornece memória auditável para agentes de IA: aprende de sessões anteriores, armazena conhecimento em markdown versionado no git, e injeta contexto relevante automaticamente. Implementa gate humano, rastreamento de proveniência e replay exato do que entrou no contexto do agente.
Instalação
npx convez-ai mustafa-bharmal-shipveho/brainstack1 comando no terminal: detecta o formato do repositório (marketplace ou plugin avulso) e instala via Claude Code. Requer Node 18+ e o Claude Code instalado.
Métricas
Casos de uso
- Agentes que precisam reter aprendizados entre sessões
- Auditoria de decisões e contexto usado por IA
- Equipes que querem controlar e revisar conhecimento compartilhado
Veredito

Solução madura e bem-arquitetada para um problema real: agentes esquecem entre sessões. Implementação local-first, sem telemetria, com gates humanos e git como fonte da verdade torna-a confiável para ambientes corporativos. Requer Python 3.10+ e familiaridade com CLI.
README
A tradução para o português deste README ainda está na fila.
brainstack
Agent memory you can audit.


Your coding agents already learn things every session, then forget them by the next one. Brainstack distills those sessions into plain-markdown lessons on your disk, asks you before anything becomes permanent, pushes the right lesson back into your agent on every prompt, before you ask, and can prove it: replay exactly what entered your agent's context, and when. Works with Claude Code, Codex CLI, Cursor, or any MCP-capable client. Your brain is a git repo of markdown you can read, diff, grep, and take with you.
Demo
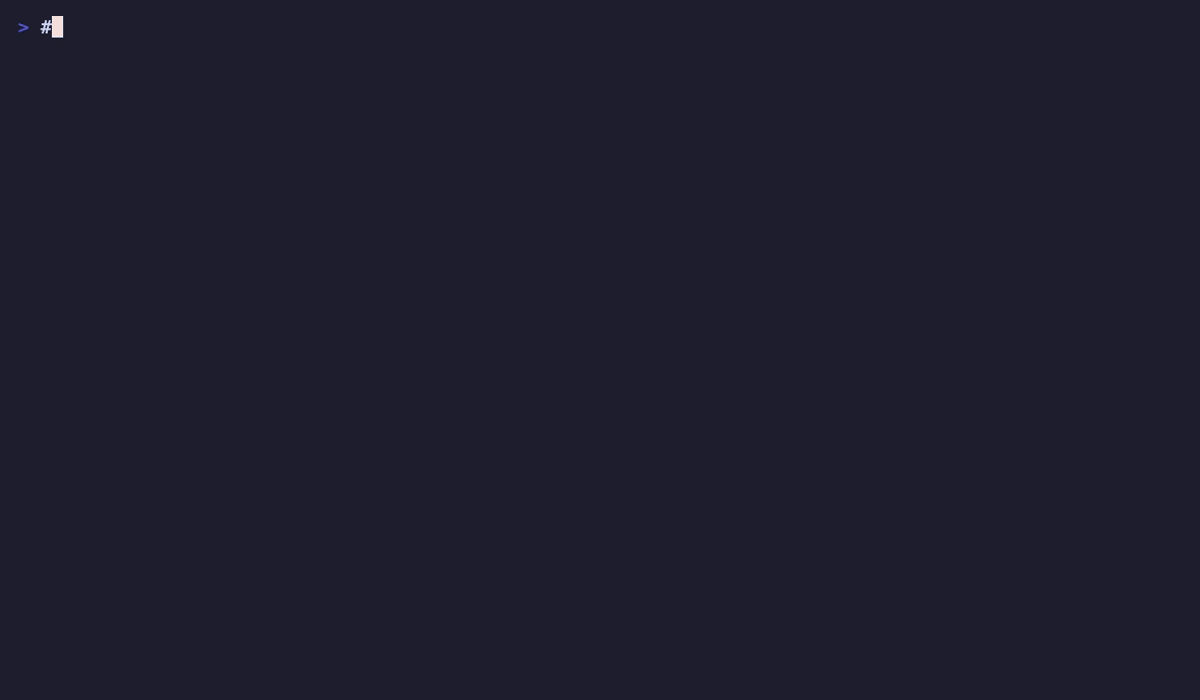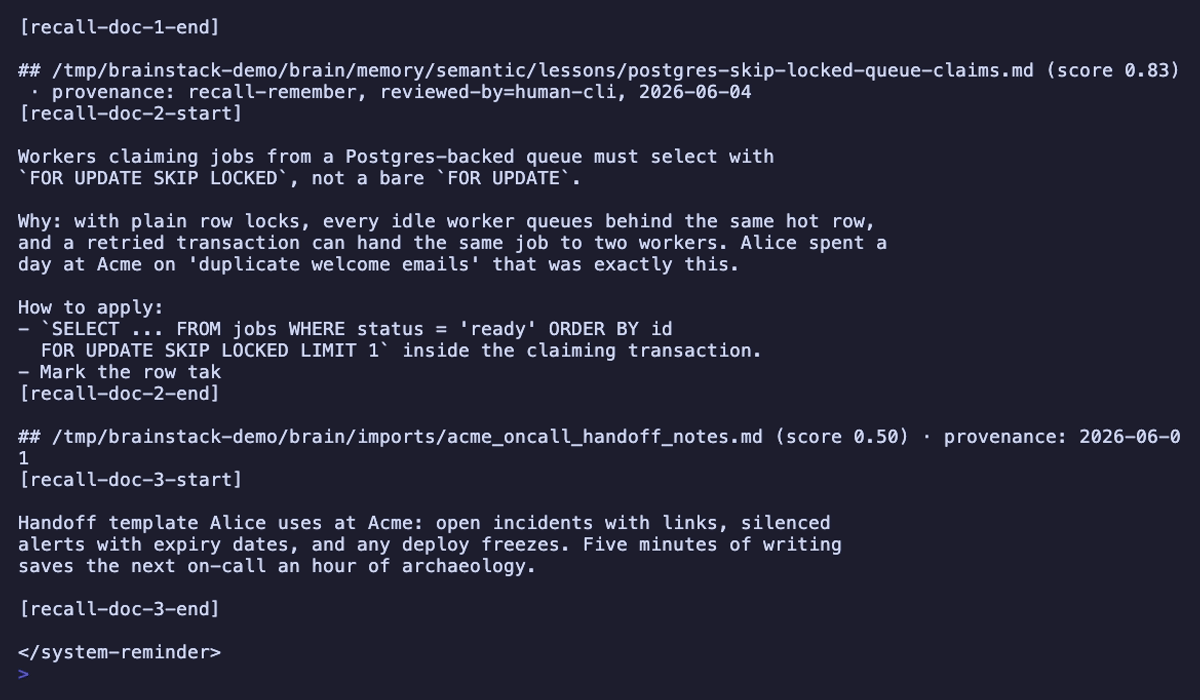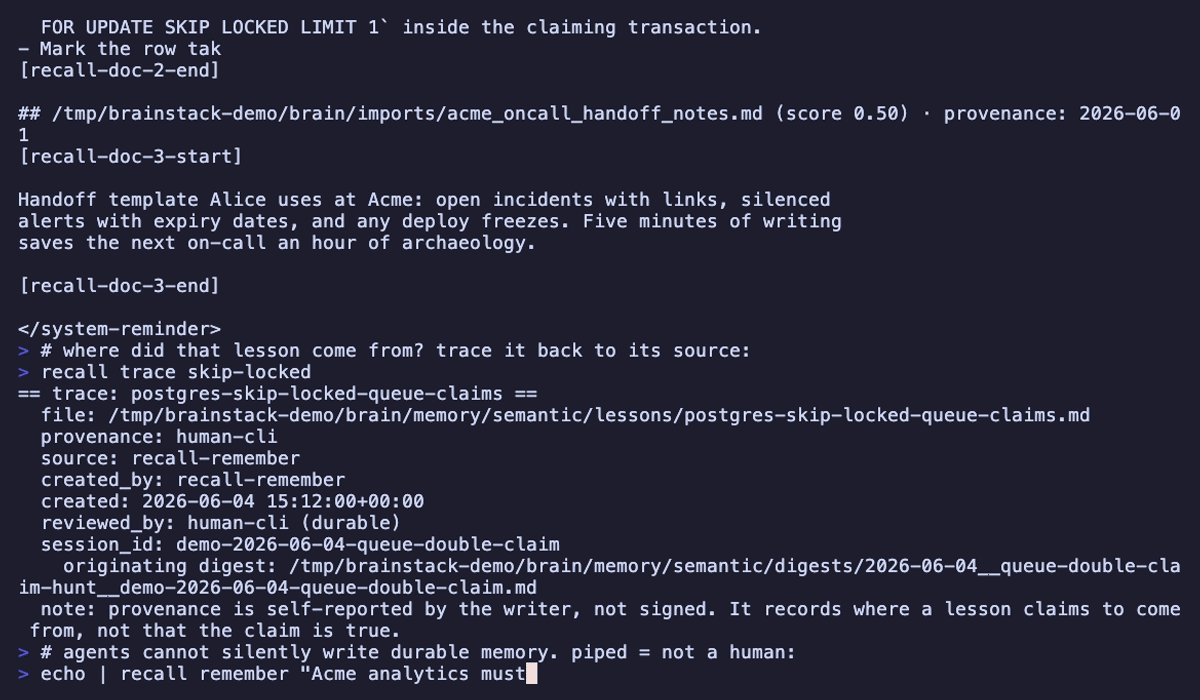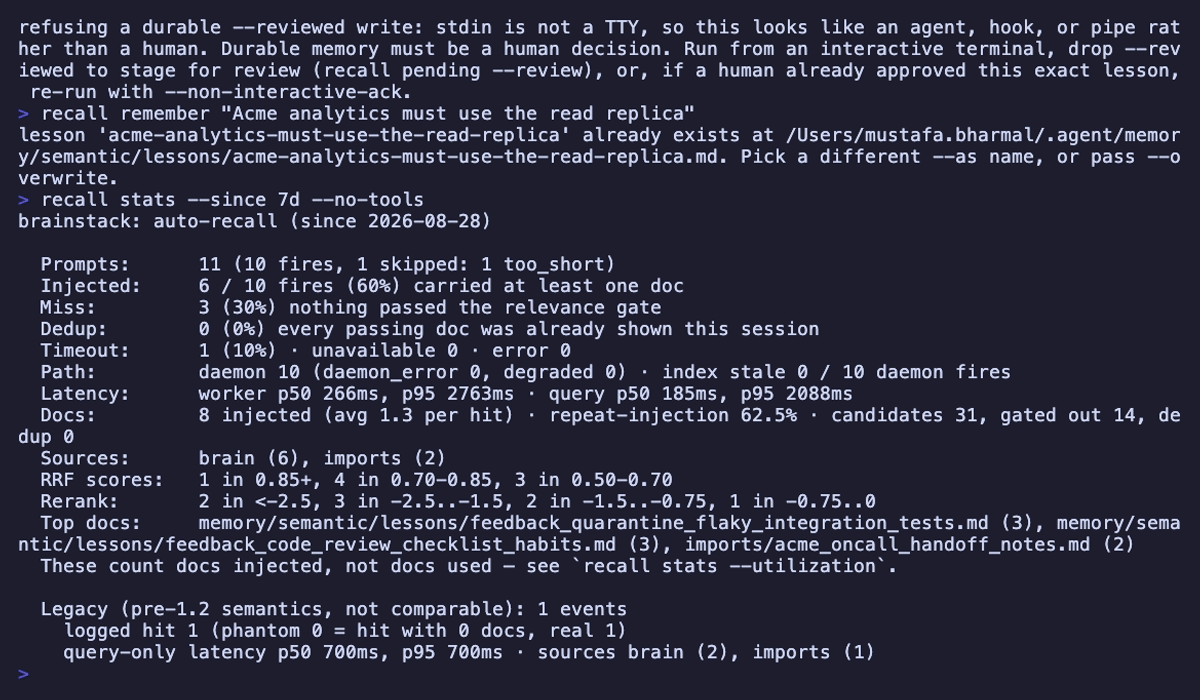
Four beats: the per-prompt hook injects a past lesson before you ask; recall trace walks that lesson back to its provenance and originating session; a piped (non-human) recall remember --reviewed is refused while the default write lands staged for your review; recall stats shows the week's auto-recall ROI. Generated from demo/demo.tape against a fully synthetic brain built by demo/make_demo_brain.py (placeholder names only, safe to publish). Regenerate with make demo (requires vhs).
Why you can trust it
- Apache 2.0, no CLA. Contributors keep their copyright; there is no relicense lever.
- Zero telemetry. The code makes no network calls of its own.
- Local-first. Brain, index, and models live on your disk.
- Exactly three things can leave your machine, each under your control: git pushes to a brain remote you configure (none in the minimal install), a one-time ~210 MB embedding model download on first index, and optional query expansion (
--expand, off by default), which sends your query text, never memory bodies, through your ownclaudeorcodexCLI. - Pushes are secret-scanner gated. Sync refuses to push without
trufflehogorgitleaks. - Durable lessons are human-gated and carry provenance. Dream candidates require your review;
recall rememberstages for review by default.
Quickstart
git clone https://github.com/mustafa-bharmal-shipveho/brainstack.git
cd brainstack
./install.sh --minimal
recall query "what did I learn about flaky integration tests"
--minimal installs the brain and the recall CLI, nothing else. It touches only the clone directory, ~/.agent/, ~/.config/recall/, and a recall symlink in ~/.local/bin/. Nothing in ~/.claude/, no daemons, no shell edits.
The full experience
Want everything turned on (auto-recall on every prompt, recall-first directives, hourly sync + nightly dream, the background session scanner) in one command, no prompts:
git clone https://github.com/mustafa-bharmal-shipveho/brainstack.git
cd brainstack
./install.sh --yes
--yes is the "install all options, don't ask me" path. Prefer to see what it does first? Run ./install.sh with no flags: it prints everything it will touch, including an Install root: line showing where the clone and its Python venv will live, and asks once before doing anything (a non-interactive run without --yes falls back to the minimal install). ./install.sh --dry-run prints that same plan and exits without changing anything. If neither trufflehog nor gitleaks is on PATH, the full install offers to install one.
Turn individual pieces off by adding the opt-out flags from the table below (they compose, e.g. ./install.sh --yes --no-launchd --no-auto-migrate).
What the full install touches:
| Surface | What it does | Opt out |
|---|---|---|
~/.claude/settings.json | Registers auto-recall hooks: recall runs on every Claude Code prompt and injects bounded brain context | --no-auto-recall |
~/.claude/CLAUDE.md, ~/.codex/AGENTS.md, ~/.cursor/.cursorrules | Sentinel-delimited recall-first directive blocks | --no-recall-first |
| Scheduler | launchd agents on macOS / systemd user timers on Linux, for hourly sync + nightly dream | --no-launchd |
| Background session scanner | Continuously rolls newly written agent sessions into the brain | --no-auto-migrate |
| Migrate discovery | Prompts before importing existing Claude / Codex / Cursor memory | --skip-migrate |
~/.local/bin/recall, ~/.agent/, ~/.config/recall/ | CLI symlink, your brain, recall config | Always installed (the minimal install installs these too) |
Back up your brain
A remote is optional. When you want the brain to survive a laptop loss, add one:
./install.sh --brain-remote git@github.com:<you>/<your-private-brain-repo>.git
Hourly sync then commits and pushes ~/.agent/ to that remote. Pushing requires a secret scanner: sync refuses to push without trufflehog or gitleaks on PATH (pass --install-scanner during setup, or brew install trufflehog). Use a private repo; the brain contains personal memory.
Already installed and want to wire a remote by hand? Inside ~/.agent/:
cd ~/.agent
git init && git branch -m main
git remote add origin git@github.com:<you>/<your-private-brain-repo>.git
git add . && git commit -m "Initial brain" && git push -u origin main
Full sync architecture: docs/git-sync.md.
Customize your install
The full install enables everything. Skip any subset by passing flags to ./install.sh:
| Flag | Skips | Reason you might |
|---|---|---|
--minimal | Everything except the brain, the recall CLI, and recall config | Smallest footprint; add pieces later with the --setup-X flags |
--skip-migrate | Interactive scan-and-import of existing Claude / Codex / Cursor memory | Start with an empty brain |
--no-auto-migrate | Background scanner that pulls new agent sessions into the brain | Trigger migrate manually instead |
--no-launchd | Hourly sync + nightly dream scheduler (launchd agents on macOS, systemd user timers on Linux) | You want to script the schedule yourself |
--no-recall-first | Recall-first directive in ~/.claude/CLAUDE.md, ~/.codex/AGENTS.md, ~/.cursor/.cursorrules | You don't use those agents, or wire elsewhere |
--no-auto-recall | Claude Code UserPromptSubmit hook firing recall on every prompt | Want only agent-driven recall, not the unconditional sweep |
--setup-systemd | (Adds systemd user timers explicitly; --remove-systemd tears them down) | Wire Linux scheduling without re-running the full install |
--yes | (Accepts the install plan and migrate-discovery prompts non-interactively) | CI / scripted installs |
--no-prompt | (Decline all migrate prompts; still runs the other defaults) | CI / scripted installs |
Each opt-out is reversible later via the matching --setup-X / --enable-X flag (or --remove-X / --disable-X to undo something later). Run recall doctor any time to see what's enabled.
How it compares
basic-memory is a store your agent has to query. claude-mem captures and recalls automatically, for many agents, but writes durable memory without review. Brainstack distills, asks you first, injects on every prompt, and can replay what the agent knew.
| Capability | brainstack | claude-mem | SuperBrain | basic-memory | Claude Code native memory | Mem0 |
|---|---|---|---|---|---|---|
| Plain markdown you own (git-syncable) | yes | no (database store) | no | yes | partial (local files, no sync story) | no (cloud-default SDK) |
| Human review gate before durable memory | yes | no | no | no | no | no |
| Proactive injection at every prompt | yes (Claude Code today) | partial (automatic, session-scoped) | partial (Claude Code only) | no (agent must query) | partial (session-start full-file load) | no (SDK query) |
| Ranked hybrid retrieval | yes | partial | partial | partial (search, not hybrid) | no | yes |
| Distilled lessons, not transcripts | yes | partial (compressed transcripts) | partial | partial (agent-written notes) | partial | partial (facts, not lessons) |
| Consolidation loop with review | yes | no | no | no | no | no |
| Provenance + context replay | yes | no | no | no | no | no |
| Model/agent agnostic | yes | yes | no (Claude Code only) | yes | no (Claude only) | yes |
| License posture | Apache 2.0, no CLA | Apache 2.0 | check | AGPL-or-check | proprietary | Apache 2.0 + hosted |
Verified against claude-mem v13.4.x, SuperBrain v0.8.0, basic-memory v0.21.6 as of June 2026; this space moves weekly.
No shipping tool today combines all five of: human-gated durable memory, plain-markdown ownership, every-prompt proactive injection, provenance with context replay, and model-agnostic operation.
Does recall actually help?
A reproducible retrieval A/B (make bench, methodology + caveats) on a labeled set with distractor documents and indirectly-worded questions:
| Condition | recall@1 | recall@5 | MRR | answer in top-5 context |
|---|---|---|---|---|
| With recall | 0.905 | 1.000 | 0.940 | 100% |
| Empty brain | 0.000 | 0.000 | 0.000 | 0% |
That is the precondition for usefulness (the right memory is surfaced), not an end-to-end task-success claim. The credible public benchmark is LongMemEval; the harness ingests its format and that run is on the roadmap. Numbers get published whatever they say.
Why not claude-mem?
claude-mem is the category leader and a good default if you want zero-ceremony automatic memory: it is mature, has a real community, and its plugin UX is smooth. Choose brainstack for three things claude-mem does not do: the review gate (nothing becomes durable memory without your sign-off), the readable git-repo brain (markdown you can diff and grep, not an opaque store), and the audit trail (recall runtime replay answers the question automatic memory cannot: did the agent have the right context when it mattered?).
Why not wait for Anthropic?
Claude's memory belongs to Claude; yours should belong to you. A brainstack brain survives switching Claude to Codex to Cursor, survives losing a vendor account, and stays inspectable markdown rather than an opaque store. It keeps the human gate that native auto-memory does not have, and provides replay that no vendor offers. If Anthropic ships all of this for Claude, the same brain still feeds every other agent you run.
What it does
Brainstack has four layers:
| Layer | Purpose |
|---|---|
| Distillation | The nightly dream cycle clusters captured events into reviewable candidate lessons; session digests summarize long sessions into searchable markdown, so recall finds past work, not only raw tool calls. |
| Storage | Plain markdown + JSONL under ~/.agent/: a private git repo you can read, diff, and grep. |
| Retrieval | recall query and the read-only recall-mcp server search memory and imports with hybrid Qdrant + BM25 retrieval; auto-recall injects bounded results into Claude Code on every prompt. |
| Runtime | Context budgets, eviction policy, and replay of exactly what brainstack injected, and when. |
Useful commands:
| Command | Use |
|---|---|
recall query "..." | Search memory and imports. |
recall query --mode {hybrid,bm25} "..." | Force a retrieval mode (RECALL_MODE env works too). Recall auto-falls back to BM25-only when the embedding stack is unavailable. |
recall query --expand "..." | LLM-expanded query for hard semantic prompts. Adds one LLM CLI round-trip (~5-20 s); off by default. |
recall remember "..." | Stage a lesson for review (needs_review by default). |
recall remember --reviewed "..." | Deliberate durable write that skips the staging gate. |
recall forget <query> | Archive a lesson by name/substring match. |
recall trace <lesson> | Walk a lesson's provenance chain: source, who wrote it, session, review status, originating digest. |
recall pending --review | Human review for staged memory candidates. |
recall reindex | Rebuild the retrieval cache after large imports/edits. |
recall stats --since 7d | Inspect auto-recall usage and latency. |
recall doctor | Diagnose wiring: hook interpreter, model cache, retrieval mode, scanner, install root. Run this FIRST when something looks wrong. |
recall runtime replay | Reconstruct what entered the agent's context, from logs. |
Retrieval details and benchmark notes: recall/README.md.
Runtime design: docs/runtime.md.
Review flow
The review gate is the core trust feature: nothing becomes durable semantic memory until you approve it. Two paths feed it:
- The dream cycle stages candidate lessons in
~/.agent/memory/candidates/. recall rememberstages new lessons asneeds_reviewby default.
Both pass through the same human review:
recall pending
recall pending --review
recall remember --reviewed exists for deliberate durable writes that skip staging; use it when you, not an agent, decide a lesson is final.
Optional startup surfaces wire pending-review visibility into Claude Code, Cursor rules, and shell wrappers for AI CLIs listed in ~/.agent/banner/wrapped_tools:
./install.sh --setup-pending-review-all
./install.sh --remove-pending-review-all
Naming map
| Name | What it is |
|---|---|
| brainstack | The project (this repo). |
| recall | The CLI. |
| recall-brain | The Python package. |
~/.agent/ | Your brain: a private git repo of markdown and JSONL. |
Where things live
| Path | What it holds |
|---|---|
| The brainstack clone | Permanent runtime infrastructure: the Python venv (~1.1 GB) lives inside it, and the hooks plus the recall symlink point into it. Pick a permanent location before installing. |
~/.agent/ | Your data: lessons, digests, notes, episodic logs. |
~/.cache/fastembed/ | Embedding models (~210 MB, re-downloadable; XDG_CACHE_HOME and FASTEMBED_CACHE_PATH are respected). |
~/.config/recall/ | recall configuration. |
~/.local/bin/recall | CLI symlink into the clone. |
~/Library/LaunchAgents/ (macOS) or systemd user units (Linux) | Scheduler entries for hourly sync + nightly dream (full install only). |
~/.agent/runtime/logs/ | Runtime telemetry consumed by recall runtime replay. |
Setup details
Most users won't need this section. Read on if you want to understand what's running, opt out of pieces, or troubleshoot.
Requirements detail
git, Python 3.10+, macOS or Linux. Windows is supported via WSL2 (run the installer inside your WSL distro; native Windows is on the roadmap)- A private git remote is optional: only needed to back up the brain
- ~210 MB one-time embedding model download to
~/.cache/fastembed/on the first index. Without it, recall auto-falls back to BM25-only retrieval (--mode/RECALL_MODEcontrol this explicitly) - A secret scanner (
trufflehogorgitleaks) is needed only for git sync; the full install offers to install one - Optional:
claudeorcodexCLI forrecall query --expand(off by default; adds one LLM round-trip, ~5-20 s, for hard semantic queries)
First-run note: the first recall query triggers a one-time reindex. Interactive queries are sub-3 s on a typical brain. Per-feature retrieval details: recall/README.md.
Hourly sync + nightly dream cycle
The full install schedules both automatically, selecting the scheduler for your platform: launchd agents on macOS, systemd user timers on Linux. To wire or tear down later:
./install.sh --setup-launchd       # macOS: expands plist templates + launchctl load
./install.sh --remove-launchd      # macOS: unload + delete plists

./install.sh --setup-systemd       # Linux: writes + enables systemd user timers mirroring the launchd schedule
./install.sh --remove-systemd      # Linux: disable + delete the units
Logs land at ~/.agent/dream.log and ~/.agent/sync.log. Full sync architecture: docs/git-sync.md.
Claude Code runtime hooks
The full install registers auto-recall hooks in ~/.claude/settings.json, with your consent at the plan prompt. Opt out with --no-auto-recall. To wire hooks manually (for example after a minimal install):
recall runtime install-hooks
Hooks are registered with the repo venv's Python interpreter; recall doctor verifies the hook interpreter, model cache, retrieval mode, scanner, and install root. Setup details: docs/claude-code-setup.md.
Bring existing memories
The full install discovers ~/.claude/projects/*/memory, ~/.codex/, and ~/.cursor/ and prompts y/n before importing each. If you skipped that (minimal install, --skip-migrate, --no-prompt) or want to import additional sources later:
./install.sh --migrate                                    # interactive discovery
./install.sh --migrate ~/.claude/projects/<slug>/memory   # specific path
For Claude Code memory directories, migration preserves the original at <source>.bak.<timestamp> before wiring the source into brainstack as a symlink. Cursor and Codex imports are snapshot-style.
The full install also turns on a background scanner that continuously rolls newly written agent sessions into the brain. If you opted out via --no-auto-migrate, enable it later with ./install.sh --setup-auto-migrate.
Optional deeper Claude Code mirroring (transcripts + misc dirs into ~/.agent/imports/, no modifications to source):
./install.sh --setup-claude-extras
Tell your agents to use recall first
The full install wires this for you (skip with --no-recall-first). Recall only helps if the agent calls it: without explicit instructions, hosts (Claude Code, Codex CLI, Cursor) tend to default to grep or web search even when the answer is already in your brain.
To wire this later or tear it down:
./install.sh --setup-recall-first-all      # all three host configs
./install.sh --remove-recall-first-all
This injects a brainstack-managed block into:
~/.claude/CLAUDE.md(Claude Code)~/.codex/AGENTS.md(Codex CLI)~/.cursor/.cursorrules(Cursor)
with a directive telling the agent: for prior-personal-context questions ("have I dealt with X before?", "what did I learn about Y?"), call recall query "..." (or the recall_query MCP tool) FIRST. The block is delimited by <!-- brainstack-recall-first-start --> sentinels and is idempotent: re-running replaces the bracketed section without touching anything else.
Per-host variants if you only want one: --setup-recall-first-claude, --setup-recall-first-codex, --setup-recall-first-cursor (each with a matching --remove-*).
Use it from Cursor or any MCP client
recall-mcp is a read-only MCP server exposing a single recall_query tool. After installing the package, add it to any MCP-capable client:
{ "mcpServers": { "brainstack": { "command": "recall-mcp" } } }
For Cursor, this one-click deeplink writes that config for you (it still asks you to approve):
A Claude Code plugin marketplace manifest ships at .claude-plugin/marketplace.json, and an MCP-registry server.json is included for uvx-based discovery (publishing to the registries is tracked in the roadmap).
Add more sources
Mirror any folder into recall:
./install.sh --add-source ~/Documents/Engineering-Notes --as kb/eng-notes
./install.sh --list-sources
./install.sh --remove-source kb/eng-notes
Mirrored sources land under ~/.agent/imports/ and are included in recall by default. Be deliberate here: mirrored sources sync to your private brain remote unless you add the destination to ~/.agent/.gitignore.
Manual brain edits via CLI
The daily way to use brainstack is through your host agent (Claude Code, Codex CLI, or Cursor), which calls recall automatically. For times when you want CLI access (adding a one-shot note from a terminal, debugging retrieval, scripting against the brain):
recall remember "always run the exact CI command from the repo config"
recall query "what should I remember before changing CI?"
recall forget ci-command
recall pending --review                  # review staged candidates
recall stats --since 24h                 # see auto-recall ROI
recall doctor                            # diagnose missing wiring
Full retrieval design and benchmarks: recall/README.md.
Safety model
Brainstack assumes your memory may contain sensitive tool-call history, and that recalled text is data, not instructions.
- Recalled excerpts are sanitized and fenced, with an untrusted-content preamble and per-document provenance labels.
- Durable lessons are review-gated: dream candidates and
recall rememberlessons both pass throughrecall pending --review. - Write-path redaction applies the builtin credential patterns plus your
redact-private.txtacross all adapters. - A redaction pre-commit hook and sync-time JSONL scrubbing run before any push.
- Scheduled sync refuses to push without
trufflehogorgitleaks. recall-mcpis read-only.- Sentinel locks and atomic writes guard append/rewrite paths; migration keeps backups instead of deleting existing memory directories.
Threat model and redaction policy: docs/redaction-policy.md.
What leaves the machine, what doesn't, and known residual risks: docs/privacy-audit.md.
Vulnerability reporting and the memory-poisoning model: SECURITY.md.
Known boundaries
- Per-prompt auto-injection ships for Claude Code today (it depends on Claude Code's
UserPromptSubmithook surface). Codex CLI and Cursor get recall-first directives plusrecall-mcp; per-client injection adapters are on the roadmap. - Embedded Qdrant is a local cache, not a multi-writer database. Short CLI/MCP use is locked and safe; heavy concurrent agents should use separate
XDG_CACHE_HOMEvalues or a shared recall/Qdrant service. - Broad natural-language queries may return the right neighborhood rather than the exact memory. Treat lower-score results as context, not authority.
- The runtime audits what brainstack injects. It cannot inspect or control a model vendor's private KV cache.
Built on agentic-stack
The consolidation pipeline (dream cycle, clustering, promotion, decay) is vendored from codejunkie99/agentic-stack (Apache 2.0), pinned and attributed in NOTICE and UPSTREAM.md. Original to this project: the recall read side (hybrid retrieval CLI + MCP server), every-prompt proactive injection and the replay runtime, the installer and its hardening, and locking/atomicity fixes to the vendored pipeline.
Architecture
~/.agent/
├── memory/
│   ├── episodic/      # append-only captured events
│   ├── candidates/    # staged lessons awaiting review
│   ├── semantic/      # durable lessons, digests, claims
│   ├── personal/      # profile, notes, references
│   └── MEMORY.md      # generated index
├── imports/           # mirrored external sources
├── tools/             # dream, sync, migration, redaction helpers
├── runtime/           # optional context-runtime logs, populated after runtime use
└── .git/              # private brain repo
More detail:
docs/architecture.mddocs/memory-model.mddocs/dream-cycle.mddocs/operational-notes.mddocs/runtime.mddocs/privacy-audit.mdrecall/README.md
Historical run logs and audit artifacts are preserved under docs/history/.
Upgrade
./upgrade.sh              # default: git pull + refresh brain (one command)
./upgrade.sh --no-pull    # skip the pull (you manage git yourself)
./upgrade.sh does two things:
git pull --ff-only origin mainin the brainstack repo so you're on the latest released code. Use--no-pullif you're already on the version you want, or in a CI/release context that handles git separately.- Refreshes
~/.agent/tools, framework memory modules, and runtime helpers while preserving user data under~/.agent/memory/. Equivalent to./install.sh --upgrade.
Each upgrade writes the new version to ~/.agent/.brainstack-version, so the next upgrade announces what changed (e.g., Upgraded from 0.4.0 → 0.5.0) and points you at the CHANGELOG for details.
Uninstall
Brainstack is safe to trial: uninstall removes every host-side surface it installed and preserves your memory data by default. The brain at ~/.agent/ (every digest, lesson, note you ever wrote) is the one thing the uninstaller never touches without an explicit opt-in.
./uninstall.sh --dry-run    # print the plan, change nothing
./uninstall.sh              # interactive, with confirmation prompt
./uninstall.sh -y           # skip the prompt (non-interactive)
./uninstall.sh --purge-data # ALSO delete ~/.agent + ~/.config/{recall,brainstack}
(./install.sh --uninstall ... is the equivalent; uninstall.sh is a discoverable wrapper around it.)
What gets removed (default)
~/Library/LaunchAgents/com.user.agent-{dream,sync,migrate,claude-extras}.plist(macOS) or the matching systemd user units (Linux)- The brainstack-shell-banner block in
~/.zshrc - brainstack-managed blocks in
~/.claude/CLAUDE.md,~/.codex/AGENTS.md,~/.cursor/.cursorrules - brainstack hook entries in
~/.claude/settings.json - The
recall/recall-mcpsymlinks under~/.local/bin/ - The index cache at
~/.cache/recall/(regenerates on next reindex)
What is preserved
~/.agent/: your memory (digests, lessons, claims, notes, episodic logs)~/.config/recall/: your recall config~/.config/brainstack/: your extractor / project / channel configs~/.cache/fastembed/: downloaded embedding models (delete manually to reclaim ~210 MB)- Your remote brain repo on GitHub: the durable backup
- The brainstack repo clone (delete manually if you want to)
Run ./uninstall.sh --purge-data (explicit opt-in) to also delete ~/.agent/ and the config dirs.
Roadmap
Where this is going, and what is deliberately out of scope: ROADMAP.md.
License
Apache 2.0. See LICENSE and NOTICE.
This is infrastructure shared as-is. Issues and PRs are welcome (CONTRIBUTING.md), but no support obligations are implied.