
meeting-agent
lixiuyin/meeting-agent
A full-stack multimodal meeting intelligence system with layered RAG, long-term memory, and skill-based generation.
Instalação
npx convez-ai lixiuyin/meeting-agent1 comando no terminal: detecta o formato do repositório (marketplace ou plugin avulso) e instala via Claude Code. Requer Node 18+ e o Claude Code instalado.
Métricas
README
A tradução para o português deste README ainda está na fila.
Meeting Agent


A full-stack RAG application that ingests meeting recordings (video/audio), documents (PDF, PPTX, DOCX, XLSX, CSV, TXT), and images (PNG, JPG, WebP, TIFF, BMP), transcribes and parses them, indexes the content into a vector database, and exposes Q&A with conversation memory, knowledge-graph entity tracking, and optional web-search augmentation. Also ships an MCP server for external tool integration.
Demo Videos
Walk-throughs and feature demos are on the project's YouTube channel:
Click a thumbnail to play on YouTube — GitHub-flavored Markdown does not embed live players inline.
| Full Demo | Invoke Skills |
|---|---|
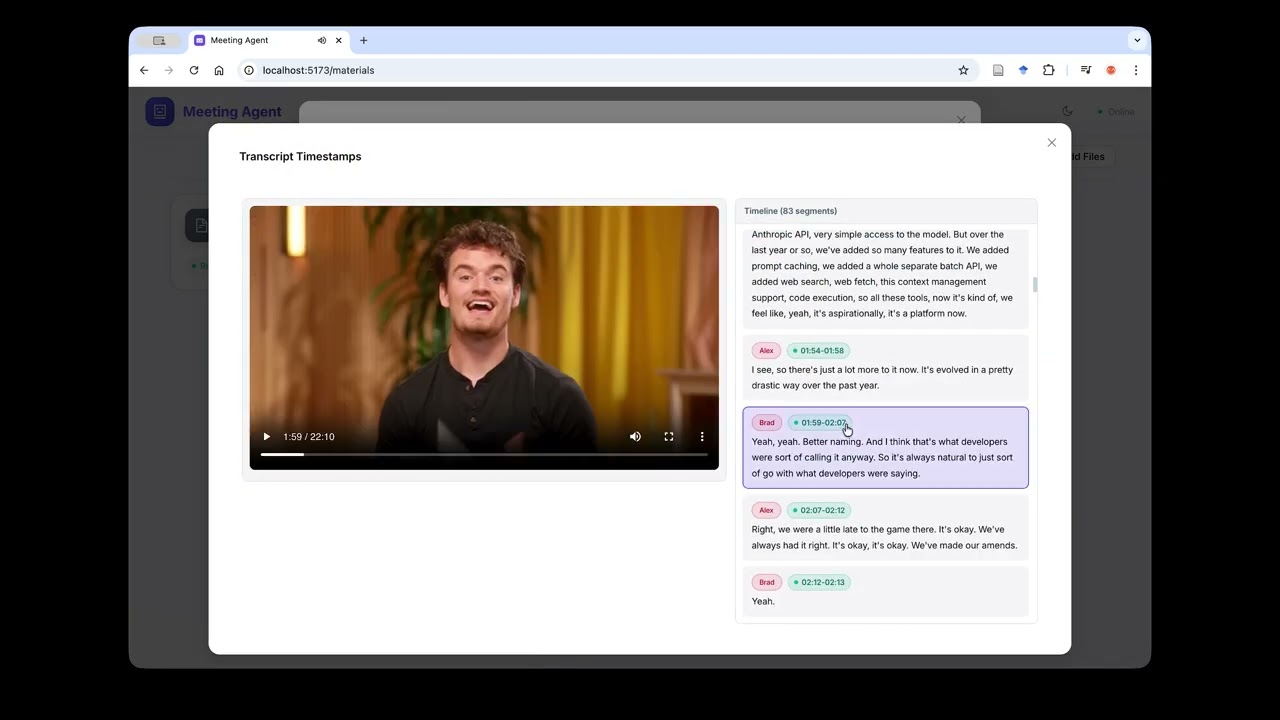 | 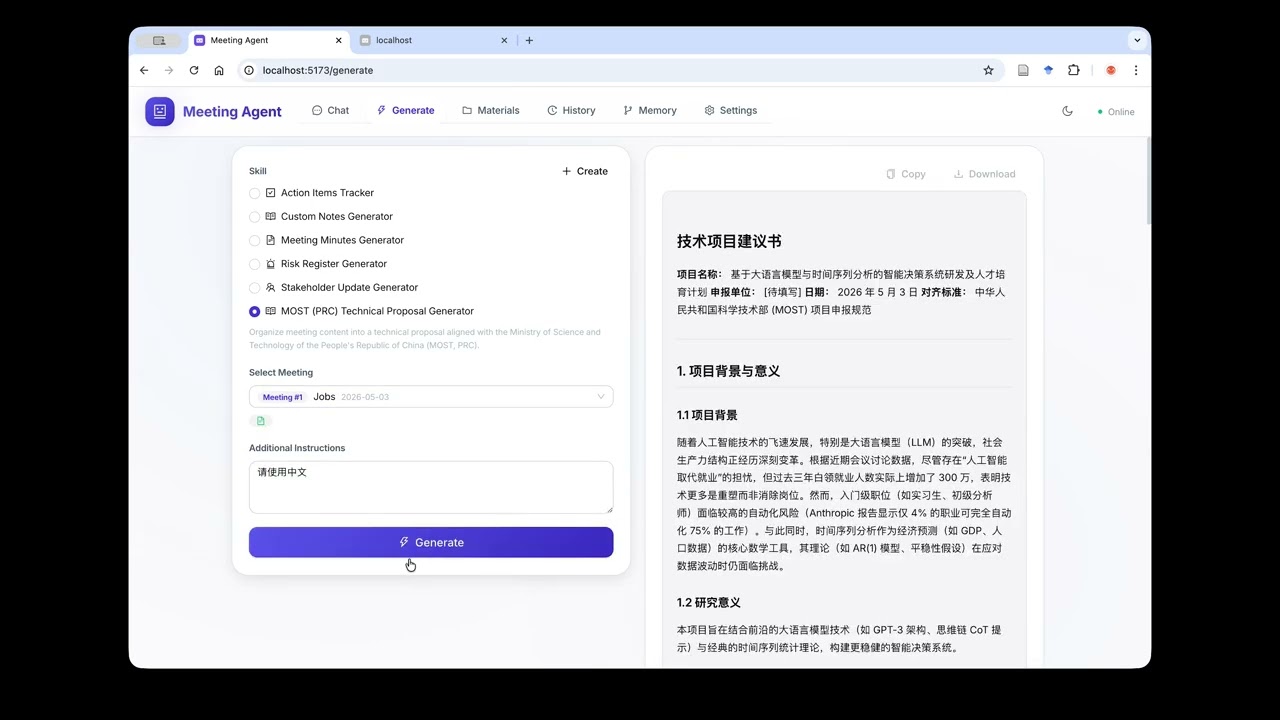 |
| End-to-end overview of upload → ingest → chat with citations | Custom skills registered via the API, fired either by direct invocation or by intent matching from chat |
| Step by Step | Memory & Knowledge Graph |
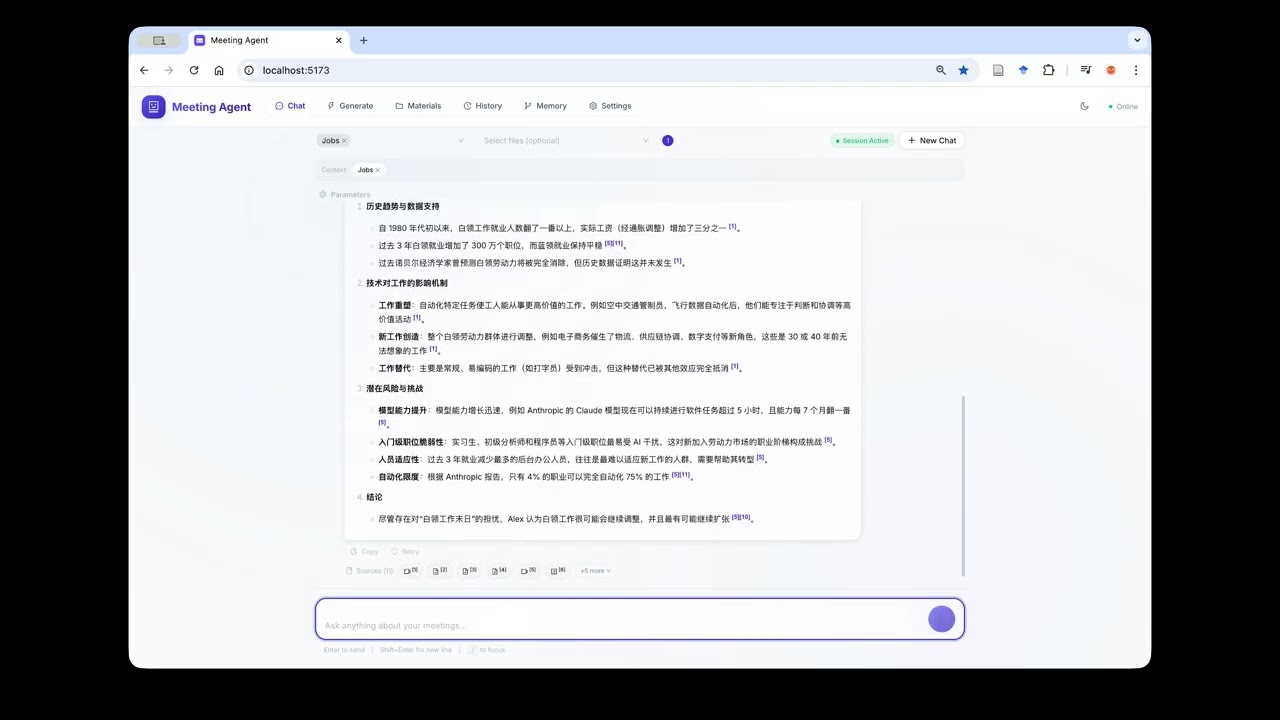 | 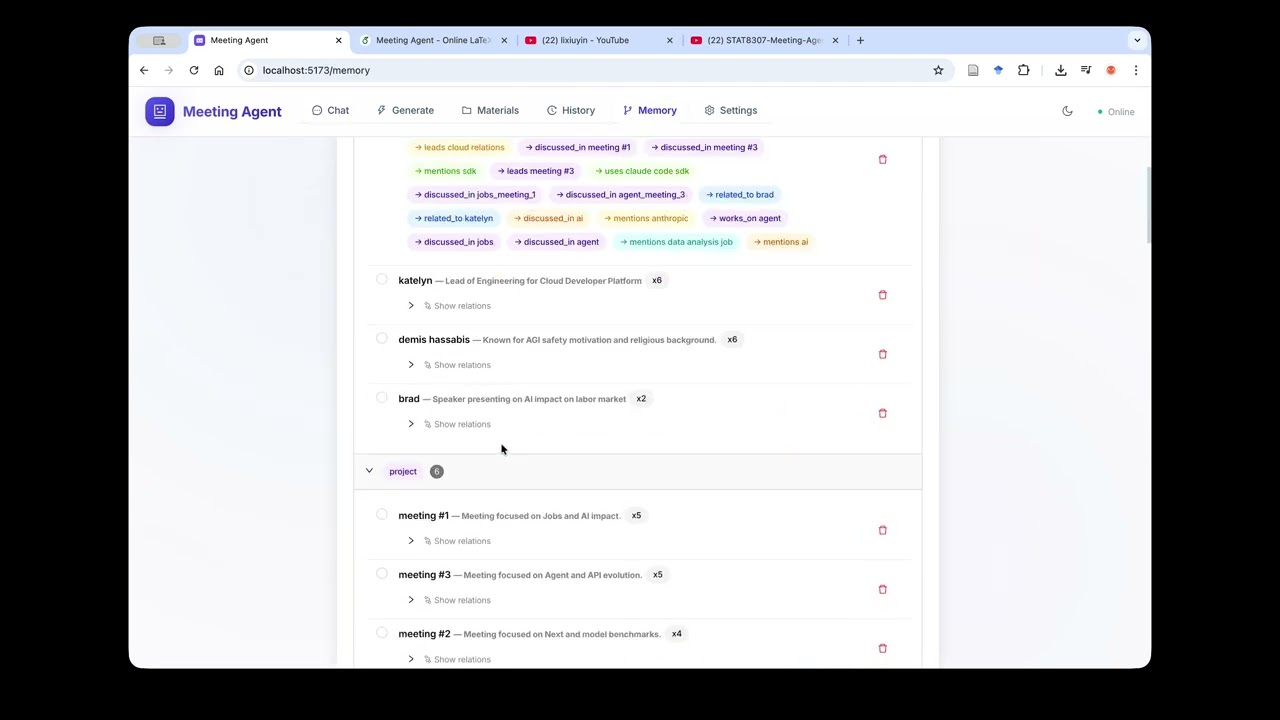 |
| Chat at three scope levels — unscoped (all meetings), meeting-scoped, and file-scoped — showing how retrieval narrows with each pick | Long-term memory, knowledge-graph entities, and cross-session recall |
Highlights
- Multi-modal ingestion — video / audio / PDF / PPTX / DOCX / XLSX / CSV / TXT / images, with magic-byte validation and streaming size limits.
- Cloud-native parsing cascade — content-aware routing across Marker, MinerU, and PaddleOCR APIs with a local PyMuPDF / python-pptx fast path and a guaranteed last-resort fallback so ingestion never hard-fails.
- Speaker-diarized ASR — AssemblyAI with editable speaker → real-name mapping that re-indexes the affected file's vectors and per-file summary.
- Hybrid retrieval — semantic (Chroma) + BM25 lexical with Reciprocal Rank Fusion, fair per-file allocation, anchor-based eviction for session continuity, and Cohere / BGE rerank.
- Unified citations — chunks, file summaries, and meeting summaries share one
[N]numbering, all clickable from the chat UI to jump back to source page / slide / timestamp. - Long-term memory — auto-extracted facts with TTL and decay, knowledge-graph entities + relations with alias merging, and episodic cross-session summaries with semantic search.
- Streaming everywhere — chat, summary generation, and rebuild operations stream tokens via SSE with per-step trace events.
- Multi-provider LLM / embedding — OpenAI, Azure OpenAI, Anthropic, DeepSeek, OpenRouter, Groq, Together, Mistral, Ollama, LM Studio, vLLM, llama.cpp; embeddings additionally support Jina, Cohere, Hugging Face, Google Vertex AI.
- Hardened API — versioned
/api/v1, per-endpoint rate limiting, idempotency keys with AES-GCM-encrypted response storage, HMAC-signed file-download tokens, and structured JSON logs. - MCP server — six tools exposed over stdio (and optional HTTP), so Claude / other agents can drive the system as a backend.
Architecture
┌─────────────────────────────────────────────────────────────────┐
│                       Frontend (React 19)                        │
│   chat · materials · memory · history · generate · settings      │
└──────────────────────────────┬──────────────────────────────────┘
                                │ /api/v1 (proxied via Vite/nginx)
┌──────────────────────────────▼──────────────────────────────────┐
│                   FastAPI · LangChain LCEL                       │
│                                                                  │
│  Upload  →  parse / transcribe  →  chunk  →  embed  →  Chroma   │
│                                              ↓                   │
│                                          BM25 + FTS5             │
│                                                                  │
│  Query   →  scope routing  →  retrieve  →  rerank  →  context   │
│                                                       ↓          │
│                                                      LLM         │
│                                                       ↓          │
│                                            answer + citations    │
│                                                                  │
│  Background: KG entities · memory decay · session summaries      │
└──────────────────────────────────────────────────────────────────┘
Backend — FastAPI 0.115+ · LangChain LCEL · ChromaDB · SQLite (WAL, alembic-managed) · slowapi · pydantic v2. Frontend — React 19 · TypeScript · Vite 6 · Ant Design 6 · react-router v7 · framer-motion. Infra — Docker Compose · Helm chart · Prometheus + Grafana + Loki + Promtail (optional observability stack).
Quick Start
Docker (recommended)
cp backend/.env.example backend/.env
# Edit backend/.env: set LLM_API_KEY (required) and ASSEMBLYAI_API_KEY (for video).
docker compose up --build
Port mapping (host → container): backend 7008 → 8000, frontend 8307 → 80. Override in docker-compose.yaml if needed.
- Frontend: http://localhost:8307
- Backend API: http://localhost:7008
- API docs: http://localhost:7008/docs
- WebSocket:
ws://localhost:7008/api/v1/ws
Manual setup
# Backend (Python 3.12+)
cd backend
uv sync --dev                          # recommended; uses uv.lock for reproducible installs
# pip install -e ".[dev]"              # alternative

# Optional extras (only install if you actually need the provider):
#   uv sync --dev --extra multimodal   # RAGAnything bridge (RAGANYTHING_ENABLED=true)
#   uv sync --dev --extra google       # Vertex AI embeddings
#   uv sync --dev --extra huggingface  # local HF embeddings + BGE reranker
#   uv sync --dev --extra local        # huggingface + llama-cpp-python (fully offline)
#   uv sync --dev --extra observability # Sentry + OpenTelemetry

cp .env.example .env                   # set LLM_API_KEY and ASSEMBLYAI_API_KEY
uv run python -m uvicorn src.main:app --reload    # http://localhost:8000

# Frontend (Node 22+; separate terminal)
cd frontend
npm install
npm run dev                            # http://localhost:5173, proxies /api → :8000
Project-level shortcuts
make dev          # backend + frontend concurrently
make dev-be       # backend only
make dev-fe       # frontend only
make cli          # interactive terminal frontend (scripts.cli_agent)
make lint         # lint everything
make test         # run all tests
make qa           # full QA: lint + tests + Playwright E2E against Docker
make clean        # remove generated files
Pre-commit hooks
pip install pre-commit && pre-commit install
Hooks in .pre-commit-config.yaml: ruff, eslint, prettier, bandit, gitleaks, detect-secrets.
Configuration
Three-tier override (highest priority last):
backend/config/main.yaml— non-secret defaults (model names, RAG knobs, upload limits).backend/.env— secrets and per-environment overrides.- Environment variables — for Docker / CI.
Settings are merged via pydantic-settings; see backend/.env.example for the full surface.
Key settings
| Setting | Default | Description |
|---|---|---|
LLM_BINDING | openai | openai, azure_openai, anthropic, deepseek, openrouter, groq, together, mistral, ollama, lm_studio, vllm, llama_cpp |
LLM_MODEL | gpt-4o-mini | Any chat model the binding supports |
LLM_API_KEY | (required) | API key for the chosen LLM provider |
LLM_BASE_URL / LLM_HOST | (empty) | Custom endpoint for OpenAI-compatible / local providers |
EMBEDDING_BINDING | openai | + jina, cohere, huggingface, google (Vertex AI), and the LLM-shared bindings |
EMBEDDING_MODEL | text-embedding-3-small | Embedding model |
EMBEDDING_DIMENSION | 1536 | Must match the model's vector size |
ASR_PROVIDER | assemblyai | Only assemblyai is supported |
ASSEMBLYAI_API_KEY | (required for AV) | env-only, never in YAML |
OCR_PROVIDER | marker | Routing hint: marker, mineru, paddle |
RAG_RETRIEVER_PROVIDER | native | native, hybrid, multimodal, hybrid_multimodal |
RAGANYTHING_ENABLED | false | Multimodal dual-index branch (requires multimodal extra) |
SEARCH_BINDING | (empty) | Web search: duckduckgo, serpapi, tavily, bing, exa |
MEMORY_AUTO_EXTRACT | true | Auto-extract facts from each Q&A turn |
KNOWLEDGE_GRAPH_ENABLED | true | Index entities + relations into the KG |
ENVIRONMENT | dev | dev, staging, prod (non-dev requires API_KEY) |
API_KEY | (empty) | Empty = dev mode (auth bypassed); non-empty for staging/prod |
LOG_FORMAT | text | Set to json for structured logs |
Helm deployment notes (SQLite)
- Run backend as a single replica (
backend.replicaCount=1) — SQLite cannot share writers. - Provide secrets via Kubernetes Secret and set
backend.secretName. - HPA / PDB templates are intentionally absent for SQLite safety.
Using Dashscope (Qwen)
LLM_MODEL=qwen-plus
LLM_BASE_URL=https://dashscope.aliyuncs.com/compatible-mode/v1
LLM_API_KEY=sk-your-dashscope-key
MCP Server
uv run python -m src.mcp                  # stdio transport
MCP_HTTP_PORT=9000 uv run python -m src.mcp   # HTTP transport (requires API_KEY)
Tools: list_meetings, search_meetings, ask_about_meetings, manage_memory, list_skills, invoke_skill.
API Endpoints
All routes are versioned at /api/v1. Authentication is via the X-API-Key header (empty API_KEY = dev mode). Rate limits are per-endpoint (upload / chat 20 / min, settings 5 / min, reads 60 / min). Errors share a unified ErrorResponse envelope (code, message, request_id, details).
Meetings
| Method | Path | Description |
|---|---|---|
POST | /meetings/upload | Upload a file (creates new meeting if no meeting_id) |
POST | /meetings | Create a new empty meeting |
GET | /meetings | List meetings (filterable by status) |
GET | /meetings/{id} | Meeting detail with file list |
PUT | /meetings/{id} | Update meeting metadata |
DELETE | /meetings/{id} | Delete a meeting and all files |
GET | /meetings/{id}/files | List files for a meeting |
GET | /meetings/{id}/files/{fid} | Download a file (header X-API-Key or ?token=) |
POST | /meetings/file-token | Issue a short-lived global file token |
POST | /meetings/{id}/files/{fid}/signed-url | Issue a file-scoped HMAC-signed URL |
GET | /meetings/assets | Fetch a meeting asset by relative path |
GET | /meetings/{id}/files/{fid}/timeline | File timeline (segments / pages / captions / text) |
GET | /meetings/{id}/files/{fid}/speakers | List speaker mappings |
PUT | /meetings/{id}/files/{fid}/speakers | Update speaker → real-name mappings |
GET | /meetings/{id}/files/{fid}/speakers/{code}/audio | Sample audio clip for a speaker |
DELETE | /meetings/{id}/files/{fid} | Delete a single file from a meeting |
POST | /meetings/{id}/summary | Generate / fetch meeting summary |
POST | /meetings/{id}/summary/stream | Stream meeting summary via SSE |
POST | /meetings/{id}/reprocess | Re-index all files of a meeting |
POST | /meetings/{id}/files/{fid}/reprocess | Re-index a single file |
GET | /meetings/{id}/transcript | Full transcript text |
GET | /meetings/{id}/transcript/timestamps | Transcript with timestamp segments |
GET | /meetings/{id}/export | Export meeting (JSON / Markdown / TXT) |
GET | /meetings/search/content | Full-text search inside transcripts |
Chat
| Method | Path | Description |
|---|---|---|
POST | /chat | RAG Q&A with memory; rag_mode per-query: native / hybrid / multimodal / hybrid_multimodal / auto |
POST | /chat/stream | Streaming answer via SSE (token / sources / trace / done events) |
POST | /chat/search | Semantic + BM25 search only, no LLM |
Sessions
| Method | Path | Description |
|---|---|---|
GET | /sessions | List chat sessions |
GET | /sessions/{id}/messages | Session message history with sources |
DELETE | /sessions/{id} | Delete a session and its messages |
POST | /sessions/{id}/summarize | Generate session summary |
GET | /sessions/{id}/summary | Fetch existing summary |
GET | /sessions/{id}/cite | Citation context for a session |
GET | /sessions/summaries | Cross-session summary list |
POST | /sessions/search | Semantic search across past sessions |
Memory & Knowledge Graph
| Method | Path | Description |
|---|---|---|
GET / POST / PUT / DELETE | /memory | CRUD on long-term memories |
POST | /memory/batch | Batch import |
GET | /memory/export | JSON export |
POST | /memory/search | Semantic search |
POST | /memory/decay | Trigger importance-based decay |
GET | /memory/entities | List KG entities |
GET | /memory/entities/{name} | Entity detail with relations |
DELETE | /memory/entities/{name} | Delete an entity |
POST | /memory/entities/merge | Merge duplicate entities |
Skills
| Method | Path | Description |
|---|---|---|
POST | /skills | Register a custom skill |
GET | /skills | List skills |
POST | /skills/match | Test intent matching (debug) |
POST | /skills/invoke | Invoke a skill directly |
Settings & system
| Method | Path | Description |
|---|---|---|
GET / PUT | /settings | Read / update runtime settings (in-memory) |
GET | /settings/bindings | List available provider bindings |
POST | /settings/rebuild-vectors | Rebuild Chroma index from transcripts |
POST | /settings/rebuild-multimodal | Backfill multimodal (RAGAnything) index |
POST | /settings/reload-config | Reload main.yaml from disk |
DELETE | /settings/account | Wipe all data for the calling user |
GET | /health | Full dependency health check |
GET | /health/live | Liveness probe |
GET | /health/ready | Readiness probe |
GET | /health/traffic | Traffic controller status |
GET | /health/index-consistency | Vector / FTS index consistency |
WS | /ws | Real-time progress / completion notifications |
Development
Backend
cd backend

uv sync --dev
uv run python -m uvicorn src.main:app --reload         # dev server
uv run python -m src.mcp                               # MCP server (stdio)
uv run python -m scripts.cli_agent                     # interactive CLI

uv run ruff check src/ tests/                          # lint
uv run ruff format --check src/ tests/                 # format check
uv run pyright                                         # types

uv run python -m pytest                                # all tests (~1,615 across 175+ files)
uv run python -m pytest tests/chain/                   # one directory
uv run python -m pytest tests/test_api.py::TestMeetingsEndpoint::test_upload_unsupported_format
Markers (defined in pyproject.toml): unit, integration, benchmark, property, chaos.
Test isolation: conftest.py monkey-patches constants.DATA_DIR before any app import, so tests use a temporary database — never the production data/meetings.db. Don't import app modules at module level in conftest.py.
CLI usage reference: backend/docs/cli.md.
Frontend
cd frontend

npm install
npm run dev                    # port 5173, proxies /api → :8000
npm run build                  # production build
npm run lint                   # eslint
npm run lint:fix
npm run format                 # prettier --write
npm run format:check
npm run type-check             # tsc --noEmit
npm run test                   # vitest watch
npm run test:run               # vitest single run
npm run e2e                    # Playwright (all browsers)
npm run e2e:headed             # headed Chromium
npm run mutation               # Stryker mutation testing
Run a single frontend test: npm run test:run -- src/test/App.test.tsx or -- -t "renders welcome".
Benchmarking
cd backend

uv run python -m scripts.benchmark chat --iterations 5     # chat pipeline latency
uv run python -m scripts.benchmark ingest --iterations 3   # ingest pipeline
uv run python -m scripts.benchmark micro                   # component micro-benchmarks
uv run python -m scripts.benchmark rag-all                 # retrieval + answer + snapshots
uv run python -m scripts.benchmark all --iterations 5      # everything
Benchmarks run against temporary databases and synthetic fixtures in tests/fixtures/benchmark/; results land in benchmark-results/. See backend/docs/benchmarking.md for the full guide.
Observability
One-command monitoring stack:
docker compose -f docker-compose.yaml -f docker-compose.observability.yaml up
- Prometheus (port 9090) scrapes the backend
/metricsendpoint. - Grafana (port 3001) — pre-wired dashboards for Prometheus + Loki.
- Loki + Promtail (port 3100) ship structured JSON logs from the backend container.
- Alert rules (
monitoring/prometheus/alerts.yaml) cover request latency, error rate, circuit breaker trips, and disk usage.
Release
Releases are tag-driven:
git tag v0.2.0
git push origin v0.2.0
.github/workflows/release.yml builds and pushes multi-arch backend / frontend images to GHCR, smoke-tests them, runs the full-stack E2E suite, validates the Helm chart, generates a changelog with git-cliff, and creates the GitHub Release. A manual workflow_dispatch rollback trigger is included.
Operations & Governance
- SLOs:
backend/docs/operations/slo.md - SLA:
backend/docs/operations/sla.md - Backup / restore:
backend/docs/operations/backup.md,backend/docs/operations/restore.md - Retention:
backend/docs/operations/retention.md - Migrations:
backend/docs/operations/alembic.md - Incident runbooks:
backend/docs/operations/runbooks/ - Architecture decisions (ADRs): product ADRs in
docs/adr/; stack ADRs inbackend/docs/adr/ - Diagrams (RAG flow, memory layers, architecture):
docs/diagrams/ - Full documentation index:
docs/README.md; backend subsystem docs:backend/docs/README.md