
Local GenAI Lab
jrodolfo/local-genai-lab
Full-stack lab local para chat assistido por tools com orquestração backend
Ver no GitHubLaboratório local full-stack para construir e testar fluxos de chat assistidos por ferramentas, combinando frontend React com backend Spring Boot. Suporta múltiplos provedores de modelos (Ollama, Amazon Bedrock, Hugging Face), RAG para corpus documental local, MCP-backed tools para AWS, sessões persistentes e geração de artefatos estruturados.
Instalação
npx convez-ai jrodolfo/local-genai-lab1 comando no terminal: detecta o formato do repositório (marketplace ou plugin avulso) e instala via Claude Code. Requer Node 18+ e o Claude Code instalado.
Métricas
Casos de uso
- Testar fluxos de chat com integração a ferramentas locais e AWS
- Implementar RAG sobre documentação interna com busca em corpus local
- Desenvolver workflows de geração de relatórios e artefatos estruturados
- Explorar múltiplos provedores de LLM (Ollama, Bedrock, Hugging Face) sem reescrever lógica
Veredito

Projeto robusto e bem arquitetado para quem quer ir além do chatbot trivial. Exige familiaridade com Java/Spring Boot, React e conceitos de orquestração de LLM, mas oferece base sólida para experimentos sérios com RAG, MCP e múltiplos provedores.
README
A tradução para o português deste README ainda está na fila.
Local GenAI Lab


Local-first GenAI lab for building and testing tool-assisted chat workflows. Not just a chatbot UI.
This project combines a React frontend, a Spring Boot orchestration backend, local and managed model providers, persistent session memory, MCP-backed AWS tooling, and an experimental RAG workspace over the project documentation in one full-stack repository.
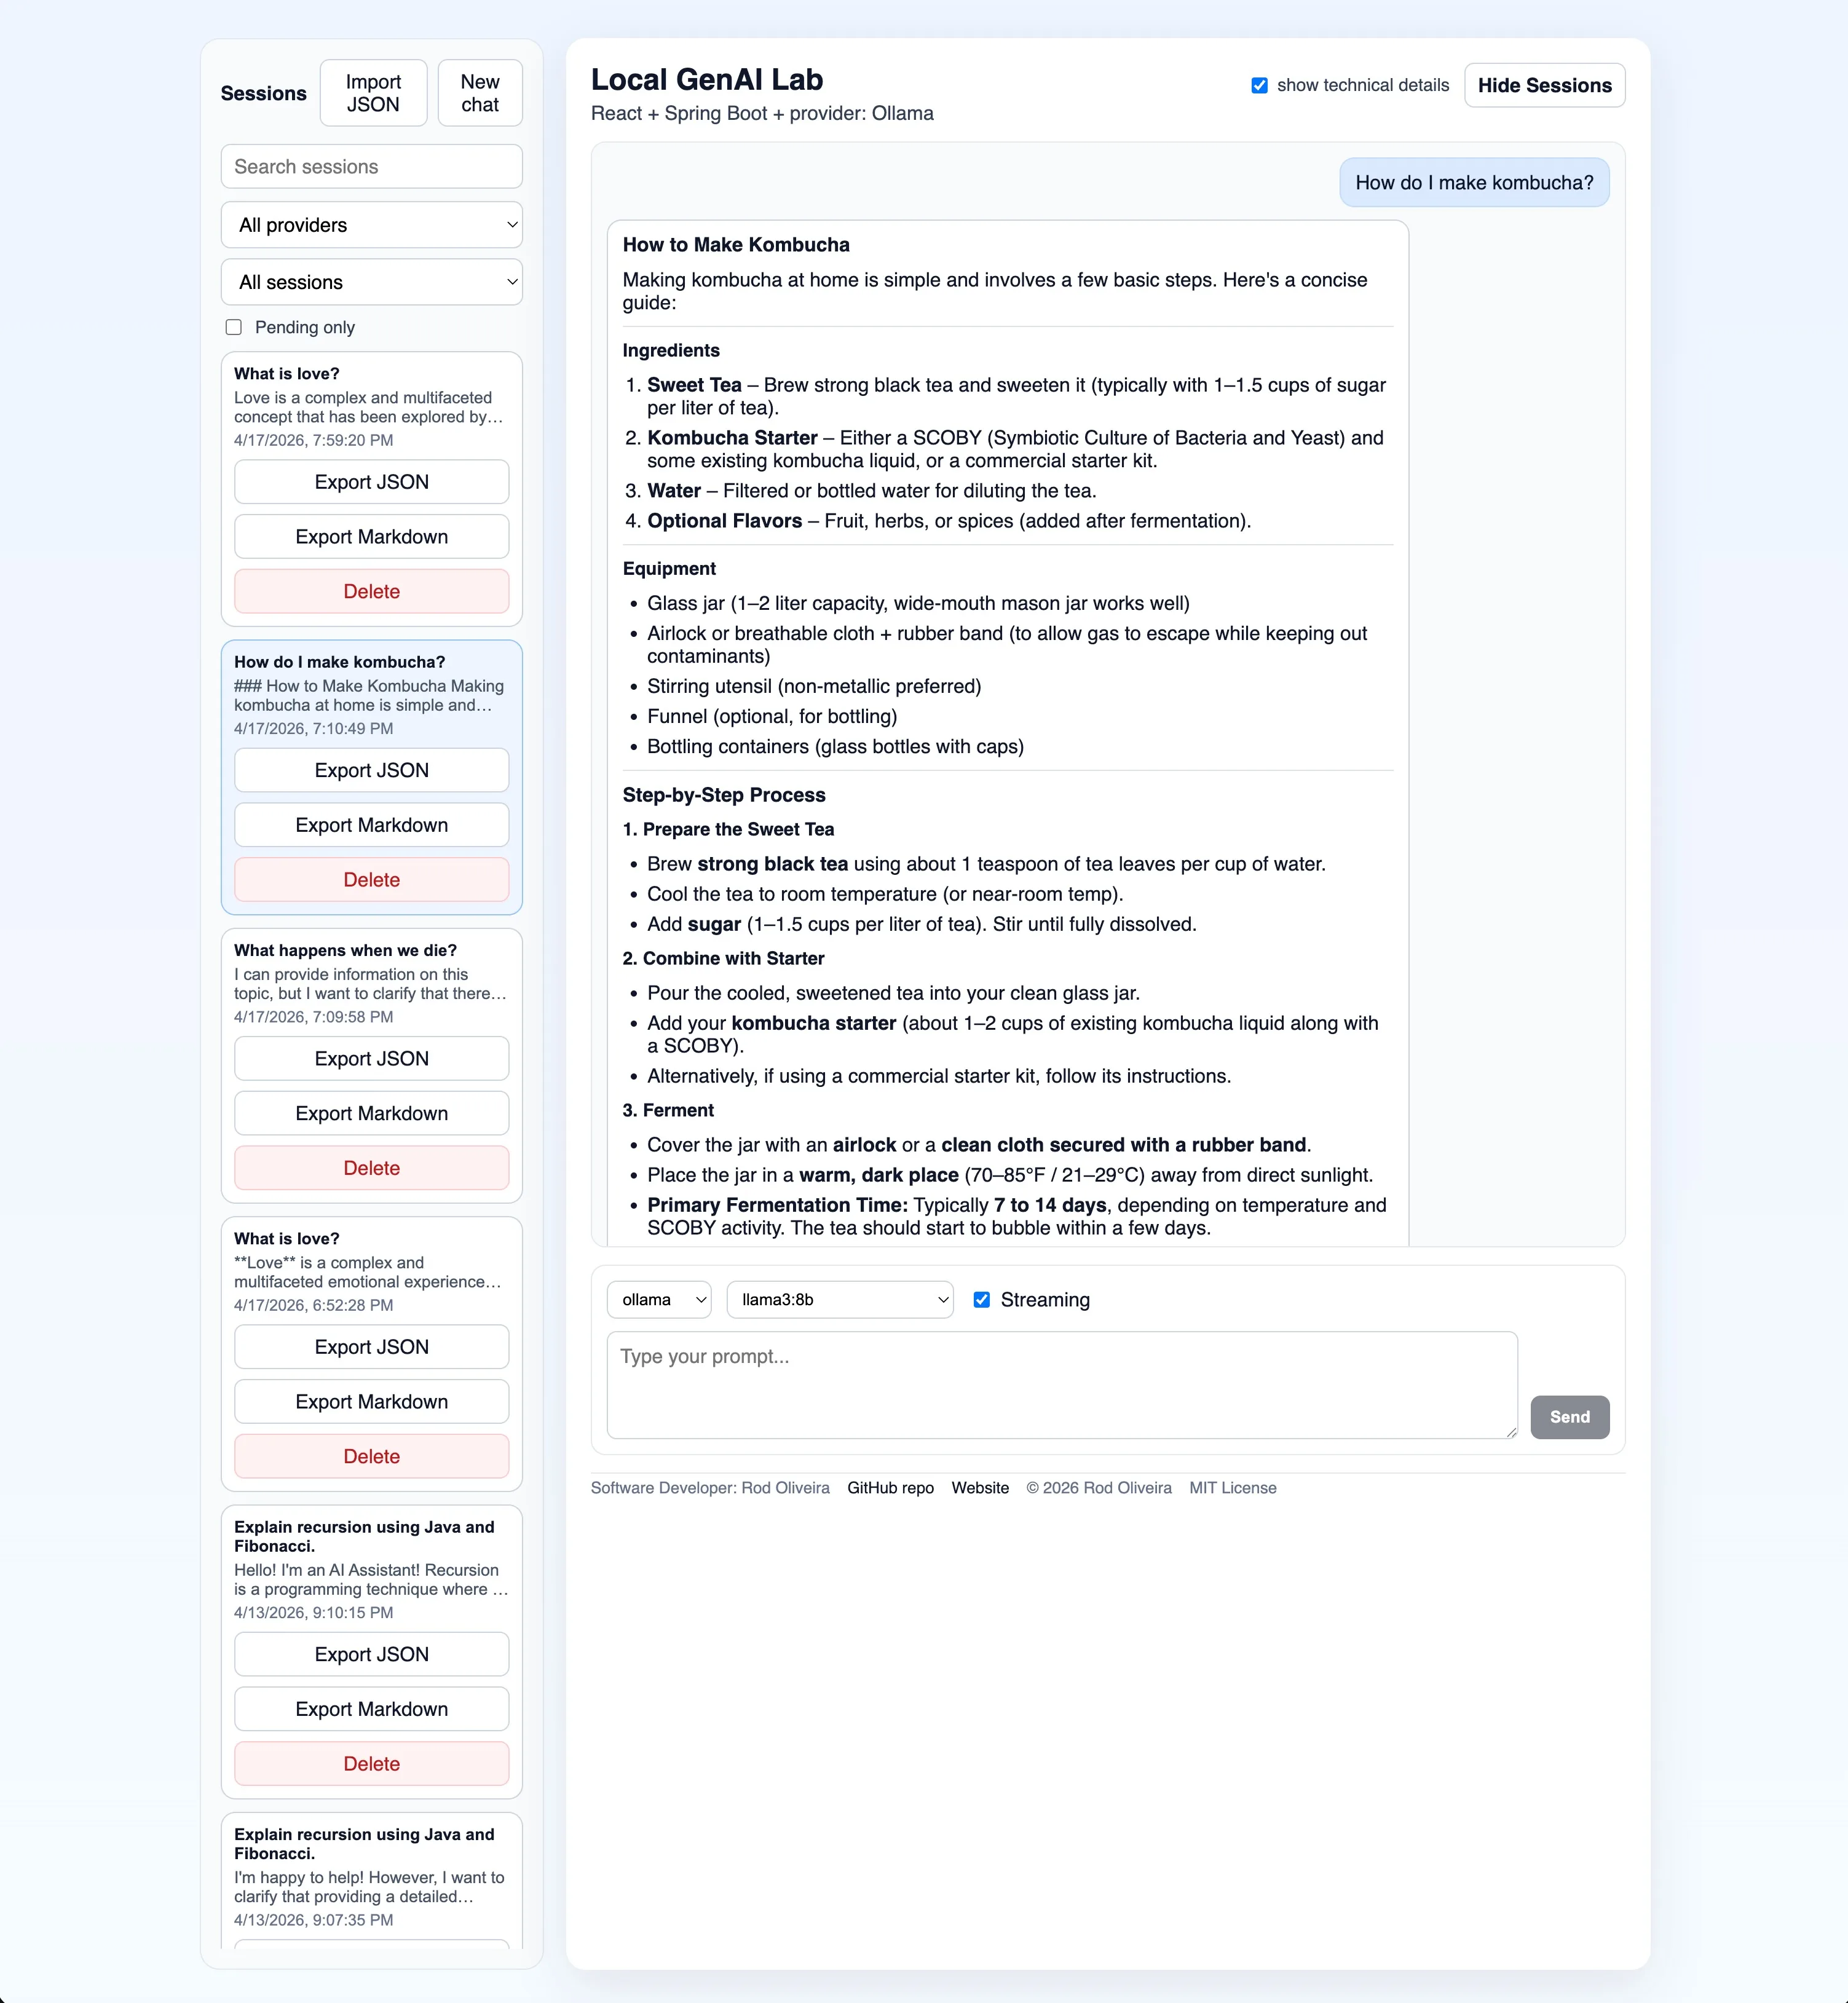
Fastest Path
If you want the shortest path to a running local setup:
cp .env.example .env
./start.sh
Then open:
- frontend:
http://localhost:5173 - backend health:
http://localhost:8080/actuator/health
Notes:
- By default, the backend starts on
http://localhost:8080withAPP_MODEL_PROVIDER=ollama. - If you want Bedrock or Hugging Face available in the provider selector, add their config to
.envfirst. - For the default Ollama path, make sure
llama3:8bis installed locally. - The
RAGworkspace is enabled by default and uses the localdocs/corpus. - The lifecycle scripts store PID files and logs under
.run/. - Use
./status.shormake statusto inspect the local runtime.
Why This Matters
Most LLM demos stop at chat. This project explores how to connect models to real systems.
It focuses on:
- tool-assisted chat with backend-side orchestration instead of direct frontend-to-model calls
- provider abstraction with Ollama by default plus Amazon Bedrock and Hugging Face as optional runtimes
- persistent session memory with resume, search, filter, import, and export flows
- MCP-backed local tool execution for AWS audits, reports, and artifact generation
- a separate RAG workspace for asking questions against the local documentation corpus with cited source chunks
- structured report rendering, artifact preview, streaming responses, and API observability
Architecture
High-level interaction flows:
For the full system-level view, see docs/architecture.md.
React -> Spring Boot
          |-> MCP -> Shell Scripts -> AWS CLI -> Report artifacts
          |-> Prompt enrichment with tool result -> Ollama / Bedrock
In the successful tool-assisted path, the backend:
- receives the user message
- decides a tool is needed
- calls the MCP-backed tool
- gets structured tool output back
- builds an augmented prompt with that tool context
- sends that enriched prompt to Ollama, Bedrock, or Hugging Face
Primary chat path:
React Frontend -> Spring Boot Backend -> Ollama, Bedrock, or Hugging Face
Tool-assisted chat path:
React Frontend -> Spring Boot Backend -> Local MCP Server -> Shell Scripts -> AWS CLI / report artifacts -> Spring Boot Backend prompt enrichment -> Ollama, Bedrock, or Hugging Face
RAG path:
React RAG Workspace -> Spring Boot RAG API -> local docs corpus -> chunk retrieval -> Ollama, Bedrock, or Hugging Face -> answer with cited source chunks
Immediate backend response path:
React Frontend -> Spring Boot Backend -> clarification or tool-failure response
Project Structure
local-genai-lab/
├── start.sh
├── stop.sh
├── restart.sh
├── status.sh
├── build.sh
├── Makefile
├── ops/
│   ├── lib/
│   ├── tests/
│   └── README.md
├── backend/
│   ├── src/
│   ├── pom.xml
│   └── README.md
├── frontend/
│   ├── src/
│   ├── package.json
│   └── README.md
├── scripts/
│   ├── reports/
│   ├── tests/
│   ├── Makefile
│   └── README.md
├── mcp/
│   ├── src/
│   ├── package.json
│   └── README.md
├── docker-compose.yml
└── README.md
Script separation:
- top-level scripts and the root
Makefileare the public local app lifecycle interface ops/contains internal local runtime helpers such as backend-only startup and stack smoke checksscripts/contains MCP/tool-facing shell scripts, report generators, and their shell tests
Prerequisites
- Java 21+
- Maven 3.9+
- Node 20+
- Ollama installed locally for the default provider
- Docker + Docker Compose, optional
- AWS CLI v2 +
jq+ valid AWS credentials, only for AWS shell tools and local MCP-backed report flows
Quick Start
1. Pull a local model
ollama pull llama3:8b
ollama run llama3:8b
Ollama should be reachable at http://localhost:11434.
2. Optional: create a local environment file
cp .env.example .env
Fill in only the providers you want available in the running backend process. The backend helper script will auto-load .env if it exists.
3. Start the app
./start.sh
This starts both:
- the Spring Boot backend
- the Vite frontend dev server
If you want Bedrock or Hugging Face as the default backend provider instead of Ollama, set APP_MODEL_PROVIDER=bedrock or APP_MODEL_PROVIDER=huggingface in .env or the shell before starting the app. Provider configuration details live in docs/providers.md.
If port 8080 is already in use, choose another backend port explicitly:
SERVER_PORT=8081 ./start.sh
The frontend dev proxy follows that override automatically when you start the app this way.
Backend URLs:
- API root:
http://localhost:8080 - OpenAPI:
http://localhost:8080/v3/api-docs - Swagger UI:
http://localhost:8080/swagger-ui/index.html - Health:
http://localhost:8080/actuator/health - Info:
http://localhost:8080/actuator/info
GET /actuator redirects to /actuator/health. Swagger excludes /actuator/** so the generated API docs stay focused on the application API.
4. Stop, restart, or inspect the app
./stop.sh
./restart.sh
./status.sh
./stop.sh stops processes managed by this repo's PID files. ./restart.sh
uses ./stop.sh --all, so it also clears processes occupying the configured
backend and frontend ports before starting the app again.
If you want to build generated artifacts before restarting, run:
./build.sh
./restart.sh
./build.sh builds the backend package, frontend production build, and MCP
server build without starting or stopping the app. Use ./build.sh --skip-tests
for a faster local build when you have already run tests.
Expected build output includes Maven and npm progress plus any JVM/native-access warnings emitted by Java dependencies during tests. Application/controller stack traces from expected negative-path tests should not appear in normal build output. If they do, treat that as test-log noise to investigate rather than as an expected part of the build.
Verification Commands
Use these commands depending on what you need to verify:
make test
make verify
make build
./status.sh
make check-app
make test: normal local pre-commit suite for operational helpers, backend tests, and frontend testsmake verify: broader project verification aligned with CI coverage, including frontend build, MCP tests/build, and MCP tool script lint/testsmake build: build backend, frontend, and MCP artifacts without changing the running app./status.sh: read-only runtime readiness check for local processes, health URLs, RAG mode, and Ollama readinessmake check-app: live-stack smoke check after the app is running
Use make test when you only need verification. Use make build or
./build.sh when you also want fresh generated backend, frontend, and MCP
artifacts before restarting the local app.
For the full testing matrix, see docs/testing.md.
The frontend provider and model selectors now load from the backend's /api/models endpoint. You can switch between supported providers at runtime without restarting the backend. For Ollama, the UI only offers locally installed models. If no local models are installed, the UI shows a clear pull hint instead of failing only after submit.
The provider selector only shows providers configured in the running backend process. The provider status banner is cached briefly to avoid excessive live checks, shows Last checked, and includes a manual Refresh status action when you want to re-fetch the current status explicitly.
For tool-assisted streaming chat, the UI now shows explicit tool lifecycle phases while the request is in flight. Completed assistant replies also show compact tool provenance, and generated summaries, reports, and file lists can be inspected through the artifact inspector panel.
The separate RAG workspace is enabled by default. In phase 1, it queries a fixed local corpus rooted at docs/ and returns answers with cited source chunks. If you want to hide it, start the backend with RAG_ENABLED=false.
Lexical retrieval remains the default. The RAG question form can select
Lexical, Vector - In Memory, or Vector - Qdrant per question. Vector
retrieval embeds the same docs corpus with RAG_EMBEDDING_PROVIDER=ollama and
RAG_EMBEDDING_MODEL=nomic-embed-text; RAG_RETRIEVAL_MODE and
RAG_VECTOR_STORE still define the backend default target at startup.
Evaluation-only RAG docs are excluded from the indexed corpus by default so manual test prompts do not become misleading retrieval sources.
The RAG index is built automatically on the first question. You do not need to
click Rebuild Index before normal first use. Use Rebuild Index after
changing docs, switching retrieval settings, or troubleshooting stale results.
For a plain-language explanation of RAG page terms such as Index, Rebuild Index, Sources, and Technical Details, see
docs/rag-troubleshooting.md#rag-page-mental-model.
If RAG or vector retrieval does not behave as expected, run ./status.sh first. It reports RAG mode, Ollama readiness, whether the configured embedding model is installed, and Qdrant reachability plus collection point count when RAG_VECTOR_STORE=qdrant. Common fixes and the RAG answer Technical Details fields are documented in docs/rag-troubleshooting.md.
Good first RAG test prompts:
How does provider selection work?Why is MCP separate from the backend?How are sessions persisted?What ADR explains the Mermaid architecture diagram?
5. Optional: build the local MCP server
cd mcp
npm install
npm run build
MCP is enabled by default in the backend. To run without it, set MCP_ENABLED=false.
Docker
Keep Ollama running on the host first, then:
docker compose up --build
- frontend:
http://localhost:3000 - backend:
http://localhost:8080
Qdrant is available as an optional local service for the phase-2 RAG vector
database path. It is not required for default startup, lexical RAG, or current
in-memory vector retrieval. When Qdrant vector mode is selected, start.sh and
restart.sh start the qdrant Docker Compose service automatically.
RAG_RETRIEVAL_MODE=vector RAG_VECTOR_STORE=qdrant ./restart.sh
./status.sh
Qdrant readiness and collection point count are visible in status output and
the RAG UI. The first RAG question can build the configured index automatically.
Use Rebuild Index when you want to populate the Qdrant collection before
asking, or after changing docs, retrieval mode, embedding model, or vector
store settings.
Configuration Overview
The most important backend settings are:
APP_MODEL_PROVIDERdefault:ollamaOLLAMA_DEFAULT_MODELdefault:llama3:8bBEDROCK_REGIONdefault:us-east-2BEDROCK_MODEL_IDdefault: emptyHUGGINGFACE_BASE_URLdefault:https://router.huggingface.co/v1/chat/completionsHUGGINGFACE_DEFAULT_MODELdefault: emptyHUGGINGFACE_MODELSdefault: emptyMCP_ENABLEDdefault:trueRAG_ENABLEDdefault:trueRAG_CORPUS_ROOTdefault:docsRAG_TOP_Kdefault:4RAG_RETRIEVAL_MODEdefault:lexicalRAG_VECTOR_STOREdefault:in-memoryRAG_QDRANT_URLdefault:http://localhost:6333RAG_QDRANT_COLLECTIONdefault:local_genai_lab_docsRAG_EMBEDDING_PROVIDERdefault:ollamaRAG_EMBEDDING_MODELdefault:nomic-embed-textRAG_EXCLUDED_SOURCE_PATHSdefault:rag-evaluation-guide.md,rag-retrieval-evaluation-template.mdAPP_TOOLS_ROUTING_MODEdefault:hybridAPP_STORAGE_SESSIONS_DIRECTORYdefault:data/sessionsAPP_STORAGE_REPORTS_DIRECTORYdefault:scripts/reports
The storage defaults are resolved from the project root so they stay stable whether the backend starts from backend/ or the repository root.
You can also point APP_STORAGE_REPORTS_DIRECTORY to an absolute path outside the repository if you want report artifacts stored elsewhere.
Provider switching details and helper startup scripts live in docs/providers.md.
Main Features
Chat and Providers
- normal and streaming chat endpoints
- Ollama as the default provider
- Amazon Bedrock as an optional provider
- Hugging Face as an optional hosted provider with a configured candidate list that the backend validates dynamically
- provider metadata in responses and saved session history
- typed JSON SSE events for streaming chat
- provider-aware model discovery for the frontend selector
- runtime provider switching across providers configured in the current backend process
Observed model behavior:
- successful tool execution still flows through the selected model by design
- the backend enriches the prompt with grounded tool output instead of bypassing the model
- different models may still phrase the final answer differently after receiving the same tool context
- that variance is intentional in this lab because it helps compare model behavior under grounded prompts
Sessions
- local JSON-backed conversation memory
- generated session titles and summaries
- session sidebar with search and filters
- JSON and Markdown export
- JSON import with collision-safe session ids
- backend-managed opaque session ids with strict validation
- separate chat and RAG session modes so RAG answers and citations can be reopened without rerunning retrieval
RAG Workspace
- enabled by default with
RAG_ENABLED=true - isolated from the normal chat, MCP, and tool-routing flow
- fixed phase-1 corpus rooted at
docs/ - evaluation-only RAG docs are excluded from indexing by default
- in-memory lexical retrieval by default behind a replaceable backend abstraction
- lexical retrieval is intentional as a zero-dependency baseline; see docs/rag-evaluation-guide.md for the lexical vs vector comparison
- experimental in-memory vector retrieval is available with
RAG_RETRIEVAL_MODE=vector - repeatable lexical vs vector observations can be recorded with docs/rag-retrieval-evaluation-template.md
- RAG readiness and common vector-mode fixes are documented in docs/rag-troubleshooting.md
- phase-2 vector database design notes, including the future Qdrant path, are documented in docs/rag-phase-2-vector-retrieval-design.md
- the RAG status card reports both retrieval mode (
Lexical) and store (In-memory) - each RAG answer can show compact technical details for retrieval target, top K, embedding metadata, and backend timing
- answers generated by the selected provider and returned with cited source chunks
- RAG conversations persist as local JSON sessions with saved answers and citations
- no uploads, external vector database, or agent routing in phase 1
Tools and Artifacts
- local MCP-backed AWS audit and reporting flows
- LLM-assisted tool routing with fallback
- multi-turn clarification for missing tool inputs
- structured report cards in the UI
- read-only artifact preview and file listing under
scripts/reports/
Artifact API note:
- the configured reports directory may be inside or outside the repository
- artifact endpoints accept only paths relative to that configured reports directory
- absolute artifact paths are rejected intentionally so the backend keeps a strict read-only boundary
Shell Scripts
The shell tooling lives under scripts/. Useful entrypoints:
make help
make test
make verify
make check-app
cd scripts
make help
make test
make audit
make s3-cloudwatch BUCKET=example.com
Documentation Map
- docs/architecture.md: system overview, request flows, provider architecture, tool orchestration, storage, and design decisions
- docs/rag-evaluation-guide.md: manual evaluation guide for the phase-1 RAG workspace
- docs/rag-retrieval-evaluation-template.md: template for recording lexical vs vector retrieval comparisons
- docs/rag-troubleshooting.md: RAG operational checks, Ollama readiness, vector-mode fixes, and lexical fallback guidance
- docs/rag-phase-2-vector-retrieval-design.md: design note for moving from in-memory vector retrieval to a Qdrant-backed vector database while keeping lexical retrieval available
- docs/rag-phase-2-qdrant-implementation-checklist.md: implementation checklist for the smallest opt-in Qdrant RAG slice
- docs/architecture-walkthrough.md: concise walkthrough of the system design, tradeoffs, and common design questions
- docs/adr/: accepted architecture decision records, including the phase-2 RAG vector retrieval direction
- docs/testing.md: automated suites, manual smoke tests, and current non-automated areas
- docs/troubleshooting.md: common local runtime problems and practical fixes
- backend/README.md: backend API, provider config, MCP integration, Actuator, sessions, Bedrock notes
- frontend/README.md: frontend-specific details
- ops/README.md: local runtime helpers and lifecycle support files
- scripts/README.md: shell tooling, report formats, smoke checks
- mcp/README.md: local MCP server details
- docs/providers.md: switching between Ollama and Bedrock
Current Scope
- single-user, local-first GenAI lab for hands-on learning and AWS Generative AI Developer Professional exam preparation
- optimized for correctness, inspectability, and local workflow clarity rather than multi-user scale
- intended to run on a developer machine with local Ollama, optional Bedrock access, and optional MCP-backed AWS tooling
Known Limitations
- not designed as a multi-tenant or internet-facing production service
- MCP tool execution currently uses short-lived local subprocesses, which is acceptable for this local lab but not tuned for shared high-concurrency use
- backend health/readiness is backend-only; whole-stack local checks belong to
ops/check-app.sh - artifact access is intentionally read-only and bounded to the configured reports directory
- Bedrock and AWS tool flows depend on your local AWS credentials and runtime environment being configured correctly
- some operational choices favor simple local behavior over production-style resilience, especially around local process orchestration and developer-machine assumptions
Notes for Heavier Models
codellama:70bis optional and not the recommended first-run default- larger local models can be much slower and more memory intensive
- if you use a heavier model, you may need to raise backend read timeouts
Contact
- Software Developer: Rod Oliveira
- GitHub: https://github.com/jrodolfo
- Webpage: https://jrodolfo.net
License
- MIT License
- Copyright (c) 2026 Rod Oliveira
- See LICENSE