
Claude Context OS
conorbronsdon/claude-context-os
Sistema de contexto versionado com memória persistente para Claude
Ver no GitHubUm sistema operacional para seu contexto no Claude que mantém arquivos versionados, memória auto-curadora e um loop de sessão /start→/end. Funciona tanto em Claude Code quanto em claude.ai, sincronizando contexto entre múltiplas interfaces sem duplicação.
Instalação
npx convez-ai conorbronsdon/claude-context-os1 comando no terminal: detecta o formato do repositório (marketplace ou plugin avulso) e instala via Claude Code. Requer Node 18+ e o Claude Code instalado.
Métricas
Casos de uso
- Manter contexto de projeto sincronizado entre Claude Code e claude.ai
- Criar workflows persistentes com memória auto-curadora que cresce ao longo do tempo
- Gerenciar estado de sessão e prioridades com histórico de versão
Veredito

Solução robusta para quem trabalha com Claude em múltiplos contextos e precisa manter state sincronizado. A arquitetura de /start→/end com auto-memory é inovadora, mas requer disciplina para manutenção de arquivos markdown.
README
A tradução para o português deste README ainda está na fila.
claude-context-os
An operating system for your Claude context — version-controlled files, a self-curating memory, and a /start → work → /end session loop, shared across Claude Code and claude.ai.


Most people paste their context into Claude's project instructions and forget about it. It goes stale. They lose track of what's there. When something changes — a new job, a new project, a new workflow — updating it means hunting through UI fields with no version history. And if you use Claude in multiple places, you're maintaining the same context in multiple places.
This repo flips that. Your context lives in files. Claude Code reads them directly; claude.ai projects read the same files as uploaded knowledge. Update a file once, and every interface you use stays current. Build a skill once — like the avoid-ai-writing skill included here — and it works as a slash command in Claude Code and as uploaded context in any claude.ai project.
It also gives Claude a persistent, file-based auto-memory that grows over time (typed entries for user/feedback/project/reference) plus a /dream curator that runs autonomous passes over the memory dir — rot detection, contradiction surfacing, pattern capture — and produces reviewable proposals before anything writes back. See docs/auto-memory.md and docs/dream-architecture.md.
See it work
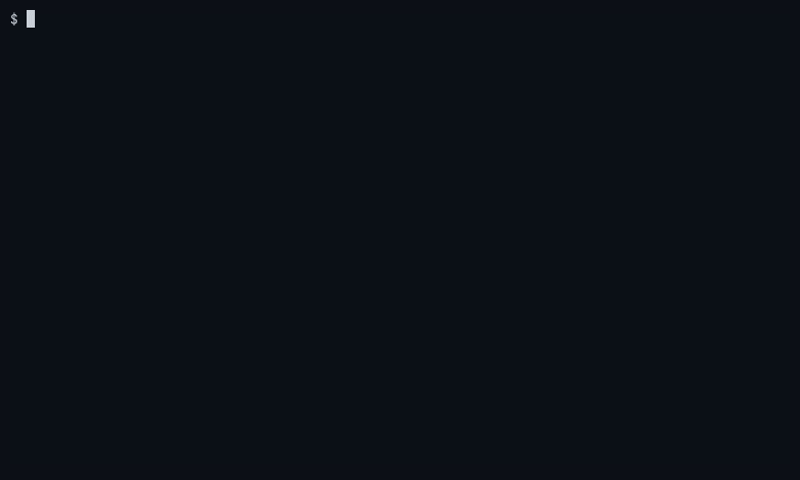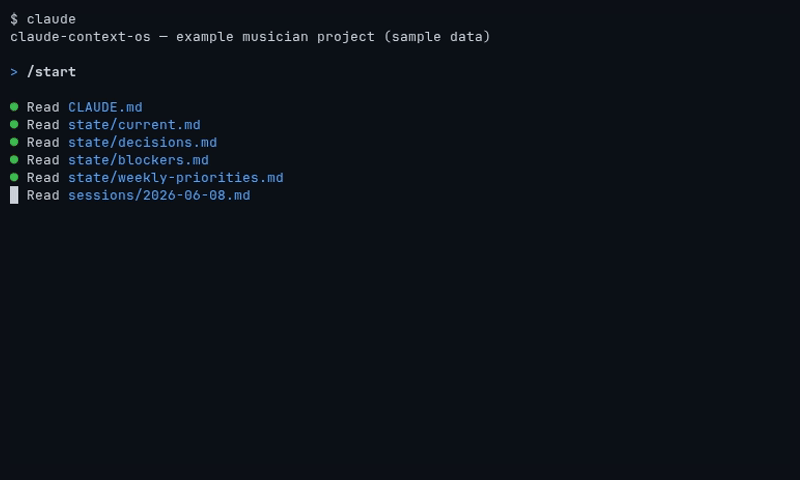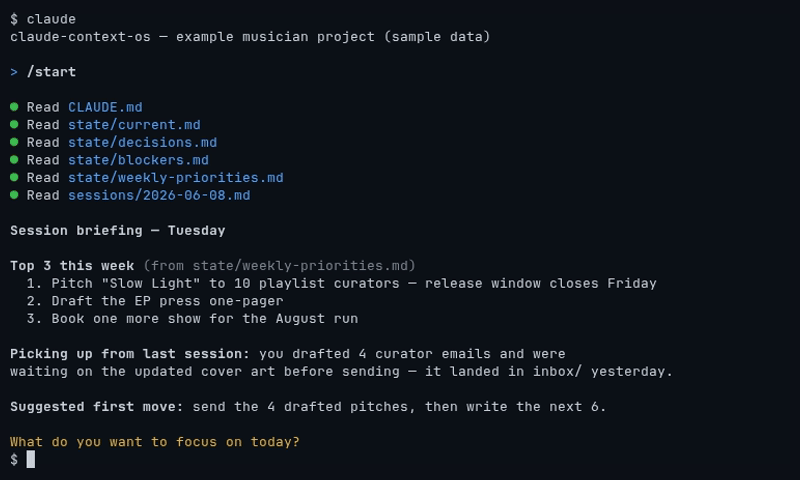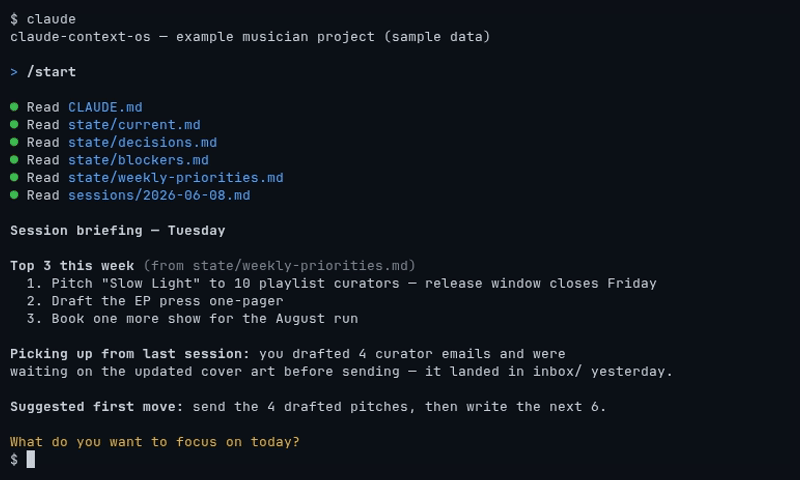
/setup interviews you and fills in your files. After that, /start reads your state, priorities, and projects and hands you a session plan instead of a blank prompt. For a filled-in version of the included example musician project, it reads like:
Session briefing — Tuesday
Top 3 this week (from
state/weekly-priorities.md)
- Pitch "Slow Light" to 10 playlist curators — release window closes Friday
- Draft the EP press one-pager
- Book one more show for the August run
Picking up from last session: you drafted 4 curator emails and were waiting on the updated cover art before sending — it landed in
inbox/yesterday.Suggested first move: send the 4 drafted pitches, then write the next 6.
Every line came from plain markdown in the repo — not a chat you rebuild from memory each morning. Run /end and it writes the session to sessions/ and updates state/, so tomorrow's /start knows exactly where you left off.
Quick start
git clone https://github.com/conorbronsdon/claude-context-os.git my-context
cd my-context
bash scripts/setup.sh
The setup script walks you through the basics: sets your name, swaps the git remote to your own repo, installs hooks, and offers to launch Claude Code. If you don't have Claude Code yet:
npm install -g @anthropic-ai/claude-code
Once you're in Claude Code, run:
/setup
Claude interviews you and builds your context files — identity, first project, weekly priorities. Takes about 10 minutes. No manual editing required.
Using claude.ai instead? Open SETUP-PROMPTS.md and paste the prompts there — same questions, same results, you just copy the output into files manually.
Note: you can give your claude.ai session this repo as project context after it's set up, and easily sync it
After setup
Run your first session:
cd /path/to/my-context
claude
/start
/start loads your state and gives you a briefing. At the end of your session, run /end to log what happened. That's the core loop — /start → work → /end.
Start small. Don't port your whole working life on day one. Run the core loop for a week, add one project, build one skill when you hit a task you repeat. The structure scales when you're ready — it doesn't demand everything up front.
| Command | When | What it does |
|---|---|---|
/setup | First time | Interactive onboarding — builds all your context files |
/start | Beginning of session | Loads state, pulls live data, gives you a briefing |
/update | Mid-session | Quick checkpoint — saves progress without closing |
/end | End of session | Logs what happened, updates state, and proposes auto-memory updates |
/today | Start of day | Lighter heartbeat — staleness check, calendar, priorities |
/capture | When inbox has items | Triages raw notes from inbox/ into the right files |
/context | Any time | Finds relevant context files by topic keyword |
/reconcile | After parallel work | Detects drift between sessions, SSOT violations |
/recover | After a crash | Scans orphaned worktrees and stale branches, offers safe cleanup |
/content-shipped | After publishing | Logs a published piece to content/log.md |
/clean-ai-writing | Before sharing anything | Loads the avoid-ai-writing skill and applies it to any content you specify |
/dream | Weekly-ish | Runs an autonomous curator pass over the memory dir (default: rot detection) |
/dream-apply | After /dream | Walks the proposal artifact, accept/reject/edit per item |
/skill-creator | Adding new skills | Generates the SKILL.md, command file, and CLAUDE.md additions from a plain-language description |
What's in the repo
CLAUDE.md                         # Root context — loaded on every session
ROUTING.md                        # Context routing for tasks without a slash command
TODO.md                           # Task backlog
SETUP-PROMPTS.md                  # Setup prompts for claude.ai users
identity/                         # Your bio, background, goals
projects/                         # Project context and skills (with worked example)
writing/skills/                   # Writing skills (avoid-ai-writing included)
state/                            # Session state, priorities, decisions, blockers
sessions/                         # Per-day session logs (created by /end)
inbox/                            # Drop zone for raw notes (triaged by /capture)
content/log.md                    # Published content log
commands/                         # Slash command definitions (including /setup, /dream, /skill-creator)
skills/                           # Cross-cutting / meta skills (e.g., skill-creator)
scripts/                          # Setup, validation, repo map generation
scripts/dream/                    # Curator prompts + how-to for the /dream substrate
docs/                             # Architecture guides — auto-memory, dream, migration, safety
references/                       # Integration setup (Google Workspace, Notion)
.claude/hooks/                    # Session start + SSOT guard + parallel-session guards
.github/                          # CI validation + PR template

# Auto-memory lives outside the repo (per-machine, often confidential):
~/.claude/projects/<encoded-cwd>/memory/
  MEMORY.md                       # Index loaded into every conversation
  <topic>.md                      # Detail files loaded on demand
  .dreams/<ISO>/                  # Curator proposal artifacts
Skills work everywhere
A skill is a markdown file that tells Claude how to do a recurring task. Build it once and it works as a slash command in Claude Code and as uploaded knowledge in claude.ai.
The avoid-ai-writing skill is included as a working example. In Claude Code: /clean-ai-writing. In claude.ai: upload writing/skills/avoid-ai-writing/SKILL.md as project knowledge and ask Claude to apply it. The easiest way to do this is by using Claude projects to give it this repo, for consistent context with all of your skills included.
To build your own:
- Run
/skill-creatorand describe what the skill should do — it generates the SKILL.md, the command file, and the CLAUDE.md additions for you to review. - Or do it manually: read
docs/agent-template.md, createprojects/<your-project>/skills/<your-skill-name>/SKILL.md, add a command file incommands/, add a row toCLAUDE.md, then runscripts/validate-skills.sh.
New here? docs/first-skill.md walks you through building your first skill by hand in five minutes — copy one, change three things, run it. See projects/README.md for conventions and the example musician project for the full pattern.
Auto-memory
Claude Code auto-loads ~/.claude/projects/<encoded-cwd>/memory/MEMORY.md at the start of every conversation in this project. claude-context-os ships a spec (docs/auto-memory.md) for what to save (and what NOT to save) across four typed memory categories:
- user — role, expertise, preferences
- feedback — guidance about how to work, both corrections and validated approaches
- project — in-flight work, decisions, the why behind them
- reference — pointers to external systems (trackers, dashboards, channels)
MEMORY.md is an index. Detail files load on demand. Cap the index at ~100 lines.
docs/memory-template.md is the seed file. Copy it to the memory dir on first setup.
/dream — autonomous curator
Memory accumulates faster than humans review it. /dream runs an autonomous curator pass over the memory dir (default curator: rot detection — flags project memories that no longer match your state files or recent commits) and writes a reviewable proposal artifact. /dream-apply walks the artifact and applies accepted items, all under git on the memory dir so any pass is one git revert away.
See docs/dream-architecture.md for the full design (curator catalog, proposal schema, scope guards).
Running multiple Claude sessions
Running more than one Claude Code session against the same repo simultaneously will eventually corrupt your tree — silent branch-switches, one session's git add landing in another session's commit, files committed to the wrong branch. The fix is git worktree: one checkout per session.
The repo ships two hooks that enforce this pattern:
worktree-guard.sh(PreToolUse) — blocksEdit/Writeto a guarded repo's primary checkout when ≥2 Claude sessions are running. Worktrees are still free. Emergency override:touch .allow-shared-editat the repo root.branch-hygiene.sh(SessionStart) — surfaces non-default HEAD on guarded repos so a silent branch-switch is noticed before any edits land.
Both hooks no-op until you list a repo basename in .claude/hooks/guarded-repos.txt. See .claude/hooks/README.md for setup.
Optional integrations
Google Workspace MCP — lets Claude read your calendar, email, Drive, and Sheets mid-session:
npm install -g @googleworkspace/cli
gws auth setup
The .mcp.json is already configured. See references/gws-mcp-setup.md for details.
claude.ai sync — upload CLAUDE.md, ROUTING.md, and relevant skill files to claude.ai projects as knowledge. See docs/claude-projects-sync.md for the workflow.
Validation
bash scripts/validate-skills.sh
bash scripts/check-links.sh
validate-skills.sh checks for: missing frontmatter, CLAUDE.md over 100 lines, committed secrets, stale files (90+ days). check-links.sh walks every inline link in tracked markdown and fails on any local target that doesn't resolve — so a renamed or moved file can't silently break a cross-reference. Both run in CI on every push and PR (.github/workflows/validate.yml), need nothing but bash, and pass before you commit.
Key conventions
- Single source of truth: Each fact lives in one file. Others reference, never duplicate.
- CLAUDE.md stays small: Under 100 lines. Detail goes in skills and ROUTING.md.
- Staleness dates:
**Last Updated:**near the top of context files. Validation flags 90+ days. - TODO.md vs. current.md: TODO is the full backlog;
state/current.mdis the top-of-mind view.
Migrating from existing Claude projects
See docs/migration-guide.md — includes an audit prompt, evaluation criteria, and restructuring guide.
Contributing
This is a template — the most useful contributions are structural: better examples, cleaner conventions, and skills others can adapt. Open an issue if you have a pattern worth adding.
Used by
- Conor Bronsdon — Modular, Chain of Thought podcast
Using this template? Open a PR adding yourself.
Disclaimer
All views, opinions, and statements expressed on this account are solely my own and are made in my personal capacity. They do not reflect, and should not be construed as reflecting, the views, positions, or policies of Modular. This account is not affiliated with, authorized by, or endorsed by Modular in any way.
License
MIT — see LICENSE. Fork it, adapt it, make it yours; no attribution required.