
MetaCortex
chrishonson/Metacortex
Memória remota persistente com busca vetorial para agentes e clientes MCP
Ver no GitHubServidor MCP de memória persistente e remota baseado em Firestore com busca vetorial. Permite que clientes de chat (ChatGPT, Claude) armazenem e recuperem memórias duráveis de forma semântica, sem gerenciar infraestrutura — tudo rodando em Firebase Cloud Functions.
Instalação
npx convez-ai chrishonson/Metacortex1 comando no terminal: detecta o formato do repositório (marketplace ou plugin avulso) e instala via Claude Code. Requer Node 18+ e o Claude Code instalado.
Métricas
Casos de uso
- Recuperar conhecimento acumulado em conversas de longo prazo
- Salvar decisões arquiteturais e contexto técnico entre sessões
- Busca semântica em base de memórias compartilhadas entre múltiplos clientes
Veredito

Solução sofisticada para arquitetar memória compartilhada em ecossistemas multi-cliente MCP. Requer Firebase Blaze e bom entendimento de vetores/Firestore, mas resolve um problema real de persistência para agentes autônomos.
README
A tradução para o português deste README ainda está na fila.
MetaCortex
MetaCortex is a serverless MCP memory service backed by Firestore vector search and deployed through Firebase Cloud Functions 2nd Gen.
Why Metacortex?
Persistent memory across any MCP client (ChatGPT web, Claude, etc.) with zero infrastructure management.
[!TIP] Memory Layer: MetaCortex provides the hosted memory service, while autonomous agents such as OpenClaw use it as a shared remote memory backend. See the full Architecture & Use Cases for details.
The practical target is a remote MCP server that chat clients such as ChatGPT web or Claude web can use for:
- searching what the project already knows
- saving new durable memories from chat
- fetching the full stored memory behind a search result
How It Works
1. Chat clients use a narrow memory contract
MetaCortex gives browser clients a three-tool memory contract. The first write comes through remember_context, which stores canonical text and lifecycle metadata on the server side.
2. Retrieval stays on the same remote backend
The same scoped MCP contract makes retrieval available later through search_context and fetch_context. ChatGPT and Claude both follow the same server-side retrieval flow, each with its own token and origin allowlist.
3. Firestore stores durable memory records plus vectors
Every saved memory lands in Firestore with searchable metadata and the corresponding vector embedding. That keeps the retrieval layer serverless while still exposing durable semantic search.
4. Scoped client profiles keep browser access safe
Browser clients never connect to the admin surface directly. Each client profile gets its own endpoint, token, origin allowlist, and allowed tool list so public chat surfaces only see the read/write tools they actually need.
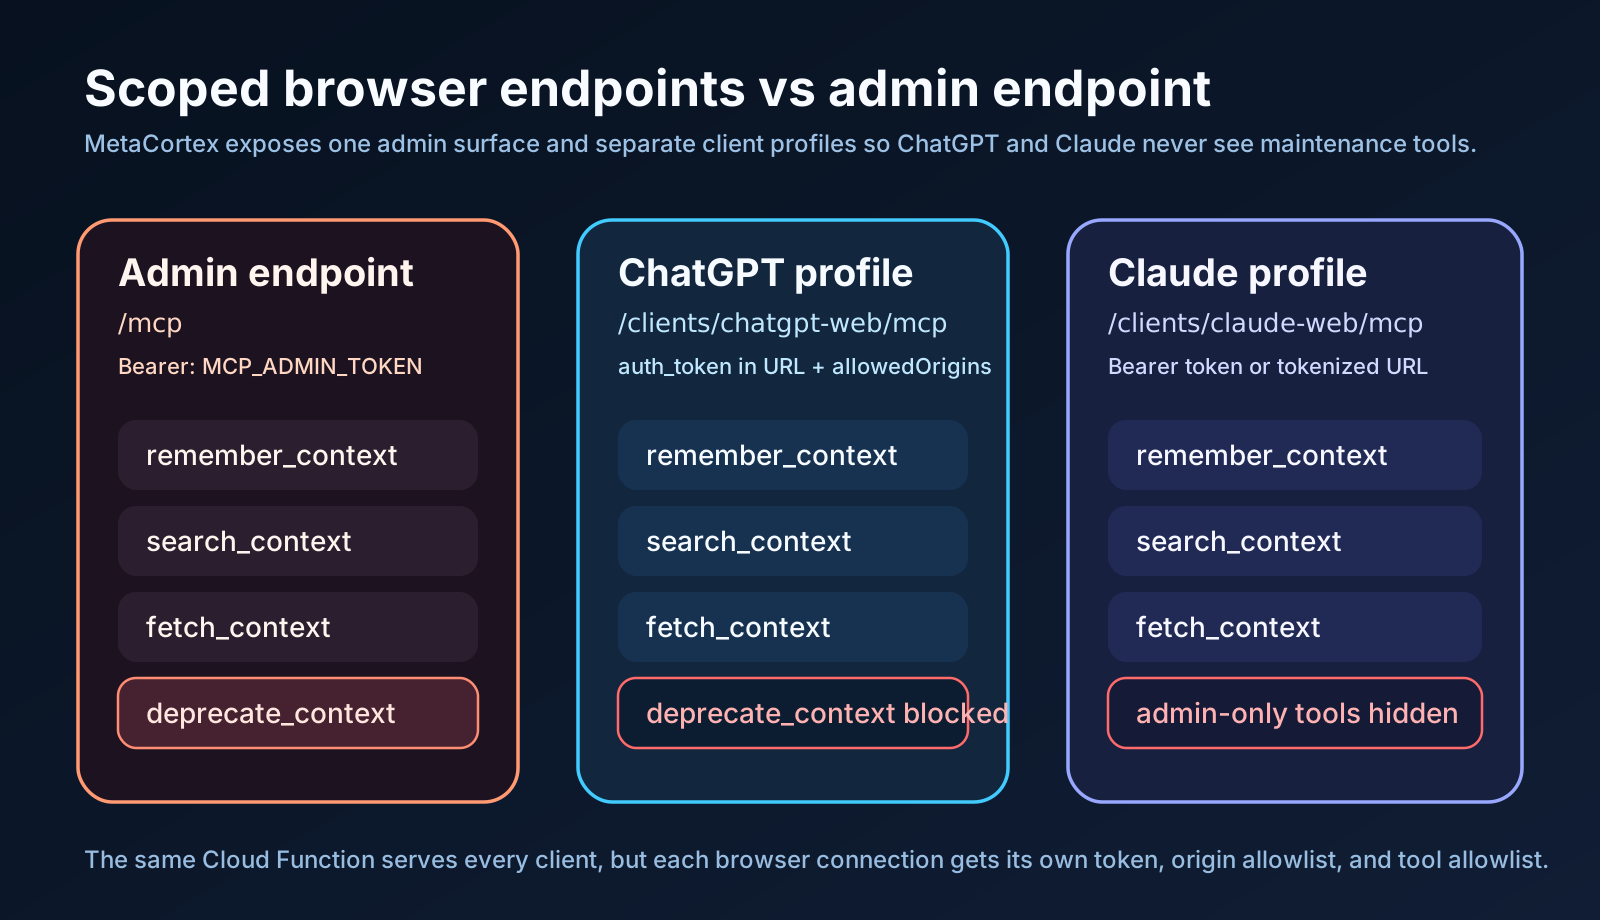
Important constraint
As of March 10, 2026, Cloud Functions production deployment requires the Firebase Blaze plan. The original Spark-only production target from the initial spec is not compatible with current Firebase Functions deployment rules, though low-traffic usage can still remain close to zero cost within Blaze no-cost quotas.
Primary use cases
This project is set up for these workflows:
- A chat client asks, "What do we already know about auth/session handling?"
The model calls
search_context. - The search results include stable
idvalues and external artifact refs when available. The model can callfetch_contextwith that sameidfor the one result it wants in full. - A user says, "Remember that we use Ktor for shared Android and iOS networking."
The model calls
remember_context. - A user shares a screenshot and says to save it for later retrieval.
The model calls
remember_contextwith image input plusartifact_refsif the real asset lives in storage.
Tool strategy
The current MCP surface is intentionally split between:
- a 3-tool client-facing contract for browser-hosted chat clients
- a smaller admin-only maintenance surface documented later in this README
That means the server currently exposes 5 MCP tools total, but normal browser clients should only see 3 of them.
Client-facing tools
This is the public/browser contract:
remember_contextThe single write tool for normal chat use. The client supplies the memory text, optional topic, optionaldraft=truefor rough notes, optional image input, and optionalartifact_refs. The server fills in sensible defaults.search_contextVector search over stored memories. Results include stableidvalues and artifact refs when available.fetch_contextFetch one memory byidafterremember_contextorsearch_context.
Why remember_context Is The Write Tool
remember_context keeps the public write surface simple:
topicis the public label and maps to the storedmodule_nameinternally- normal writes store canonical memory as
active draft=truestores draft material aswip
Explicit lifecycle overrides and cleanup flows are part of the admin maintenance surface described later in this README.
Metadata model
The main public metadata field is topic. Stored records also carry lifecycle metadata such as branch_state, but that is primarily for admin cleanup and filtering and is documented later in Admin Cleanup And Consolidation.
topic
Public topic or subsystem label for MCP clients. Internally this is stored as module_name.
Examples:
authbillingkmp-networkingui-settings
If omitted, the server defaults it to general.
Images
This project supports image-backed memories, but it does not store raw image bytes for later download.
What happens today:
- the image is normalized into retrieval text by Gemini
- that text is embedded and stored
- optional
artifact_refscan point to the real asset, for examplegs://bucket/path.png - search results and fetched records return those artifact refs when they exist
That means the practical image flow is:
- save a screenshot with
remember_context - store the real asset elsewhere
- include its
artifact_refs - let semantic search find the memory
- let the client follow the returned artifact ref to the actual screenshot
Endpoints
- Default Streamable HTTP MCP endpoint:
/metaCortexMcp/mcp - Client-scoped Streamable HTTP MCP endpoint:
/metaCortexMcp/clients/<clientId>/mcp
Security model:
- the default
/mcpendpoint is the admin endpoint clients/<clientId>endpoints let you expose smaller toolsets to specific consumersMCP_ALLOWED_ORIGINSapplies only to the default admin endpoint- browser CORS should be configured per client profile through
MCP_CLIENT_PROFILES_JSON[].allowedOrigins - leave
MCP_ALLOWED_ORIGINSempty unless you intentionally want browser access to the admin endpoint
Recommended browser read/write toolset:
remember_contextsearch_contextfetch_context
This 3-tool browser contract is the intended v1 public surface.
Browser Client Setup
For browser-hosted MCP clients, register the scoped endpoint, not the admin endpoint:
- ChatGPT web URL:
https://<FUNCTION_BASE_URL>/clients/chatgpt-web/mcp?auth_token=<YOUR_CHATGPT_TOKEN> - Claude web URL:
https://<FUNCTION_BASE_URL>/clients/claude-web/mcp - bearer token: the
tokenvalue from the matching client profile - allowed browser origins: the matching profile's
allowedOrigins
Do not register https://<FUNCTION_BASE_URL>/mcp with ChatGPT web or Claude web. That endpoint is the admin surface and uses MCP_ADMIN_TOKEN.
Use separate client profiles per browser client:
chatgpt-webwithallowedOrigins=["https://chatgpt.com"]claude-webwithallowedOrigins=["https://claude.ai"]
For agent-based clients such as OpenClaw, use a dedicated non-browser scoped profile instead of the admin endpoint. A recommended operating model is documented in docs/OPENCLAW_MEMORY_OPS.md.
Connecting to ChatGPT
ChatGPT's current MCP UI does not support configuring custom Authorization: Bearer headers. To work around this security limitation, MetaCortex supports passing the token securely via the URL.
- Open ChatGPT Web or Desktop.
- Open Settings -> Connected Apps (or MCP Settings).
- Click "Add new App" or "Connect MCP Server".
- Set Auth Type to No Authentication.
- Set the MCP URL to your tokenized endpoint:
https://<FUNCTION_BASE_URL>/clients/chatgpt-web/mcp?auth_token=<YOUR_CHATGPT_TOKEN>
MetaCortex will validate the token from the URL and reject unauthenticated requests even though ChatGPT is configured for "No Auth".
Connecting to Claude
Depending on your Claude client (e.g., experimental web extensions or custom UIs), you can configure the connection in two ways:
Option 1: Standard Headers (Preferred)
- MCP URL:
https://<FUNCTION_BASE_URL>/clients/claude-web/mcp - Auth Type: Bearer Token / Service Token
- Token:
Bearer <YOUR_CLAUDE_TOKEN>
Option 2: Tokenized URL (If headers are unsupported)
- Auth Type: No Authentication
- MCP URL:
https://<FUNCTION_BASE_URL>/clients/claude-web/mcp?auth_token=<YOUR_CLAUDE_TOKEN>
Tool Contract
The v1 client-facing tools return one TextContent block whose text is a single JSON object.
remember_context
Minimal text memory:
{
  "content": "We use Ktor for shared Android and iOS networking.",
  "topic": "kmp-networking"
}
Typical result:
{
  "item": {
    "id": "abc123",
    "content": "We use Ktor for shared Android and iOS networking.",
    "metadata": {
      "topic": "kmp-networking",
      "branch_state": "active",
      "modality": "text",
      "created_at": "2026-03-14T12:00:00.000Z",
      "updated_at": "2026-03-14T12:00:00.000Z"
    }
  },
  "write_status": "created"
}
Use item.id directly with fetch_context.
Image-backed memory with an external asset reference:
{
  "content": "Settings screen screenshot for the Compose UI.",
  "topic": "ui-settings",
  "artifact_refs": ["gs://your-bucket/settings-screen.png"],
  "image_base64": "<base64 image bytes>",
  "image_mime_type": "image/png"
}
search_context
Example input:
{
  "query": "shared networking for android and ios",
  "filter_topic": "kmp-networking",
  "filter_state": "active"
}
Typical result:
{
  "matches": [
    {
      "id": "abc123",
      "summary": "We use Ktor for shared Android and iOS networking.",
      "score": 0.92,
      "metadata": {
        "topic": "kmp-networking",
        "branch_state": "active",
        "modality": "text",
        "created_at": "2026-03-14T12:00:00.000Z",
        "updated_at": "2026-03-14T12:00:00.000Z"
      }
    }
  ],
  "applied_filters": {
    "filter_topic": "kmp-networking",
    "filter_state": "active"
  }
}
If an item has external refs, they appear in metadata.artifact_refs.
If nothing matches, the result is:
{
  "matches": [],
  "applied_filters": {
    "filter_topic": null,
    "filter_state": "active"
  }
}
fetch_context
Preferred input: pass the same id returned by remember_context or search_context. document_id is accepted as a compatibility alias for older connector wrappers.
Example input:
{
  "id": "abc123"
}
Compatibility alias:
{
  "document_id": "abc123"
}
Typical result:
{
  "item": {
    "id": "abc123",
    "content": "We use Ktor for shared Android and iOS networking.",
    "metadata": {
      "topic": "kmp-networking",
      "branch_state": "active",
      "modality": "text",
      "created_at": "2026-03-14T12:00:00.000Z",
      "updated_at": "2026-03-14T12:00:00.000Z"
    }
  }
}
Search Behavior
search_context does one exact metadata filter step and one vector step:
filter_stateis always applied before nearest-neighbor searchfilter_topic, when present, is an exact match on the stored topic label- vector search then runs Firestore
findNearest()with cosine distance - the result count is
limitwhen provided, otherwiseSEARCH_RESULT_LIMIT - the default state is
activeunless the client profile allows and requests another state
fetch_context can still fail with 403 if the document exists but its branch_state is outside that client profile's allowedFilterStates.
Write Constraints
Write behavior that matters in production:
- request bodies are limited to
1mb, including base64 image data contentorimage_base64is requiredimage_mime_typeis required wheneverimage_base64is provided- images are normalized into retrieval text and embedded as text; raw image bytes are not stored for download
- if you want the real asset later, store it elsewhere and include
artifact_refs - exact duplicate writes within the current idempotency window are replay-safe and reuse the existing memory
id - duplicate suppression is intentionally light and based on the normalized write fingerprint, not semantic similarity
remember_context defaults:
- omitted
topicbecomesgeneral - omitted
draftand omitted lifecycle overrides storebranch_state=active draft=truestoresbranch_state=wip
Explicit lifecycle overrides are part of the admin maintenance surface described later in this README.
Admin Cleanup And Consolidation
This section is for operators using the admin endpoint. Browser-hosted clients can usually ignore it.
Admin-only maintenance surface:
deprecate_contextSoft-delete obsolete memories by settingbranch_state=deprecatedand recordingsuperseded_by.consolidate_contextMerge multiple related memories into one canonical active memory via LLM. By default merges all WIP memories for a topic. Passsource_idsto consolidate specific memories regardless of their current state. All source memories are deprecated and linked to the merged result.
Lifecycle states:
activeCanonical memory that normal search should return.wipDraft memory awaiting consolidation.mergedIncorporated memory that is no longer the main active record.deprecatedObsolete memory kept only for history and audit.
Recommended usage:
- Browser clients save durable memories with
remember_context. - Agent clients such as OpenClaw should use a dedicated scoped client profile with
remember_context,search_context, andfetch_contextonly. - Use
draft=trueonly for provisional notes that should not appear in normal active search. - Use
consolidate_contextto merge a batch of WIP drafts or fragmented active memories into one canonical record. - Admin flows can set explicit
branch_statewhen they need non-default lifecycle control. - After writing the canonical replacement, admins can mark obsolete records with the admin-only
deprecate_contexttool.
Current lifecycle behavior:
remember_contextdefaults toactive, supportsdraft=trueforwip, and also accepts explicitbranch_statefor advanced writesdraftandbranch_stateare mutually exclusivedeprecate_contextdoes not delete data; it setsbranch_state=deprecatedand recordssuperseded_byconsolidate_contextcalls Gemini to merge N source memories into one, stores the result asactive, and deprecates all sources withsuperseded_bypointing to the merged idmergedexists as a searchable historical state for explicit admin writes- client profiles can restrict visible lifecycle states through
allowedFilterStates
Observability
After deployment, there are three places to look:
memory_vectorsin Firestore shows the current memory corpusmemory_eventsin Firestore shows client-attributed tool usage over time- Cloud Logging shows request failures and structured tool-event logs
memory_events records one document per tool call and one document per ingress rejection. Events include:
client_idevent_typestatustimestampexpires_atlatency_ms- a compact
requestsummary - either a compact
responsesummary, anerror, or a request rejection reason
Examples:
-
public tool payloads use
idfor fetchable memory identifiers -
remember_contextevents record the writtenid,topic,branch_state, andmodality -
search_contextevents record the requested filters,result_count, and returnedresult_ids -
fetch_contextevents record whichidwas read -
deprecate_contextevents recordid,superseding_id, andprevious_state -
rejected browser/admin requests record
reason=origin_not_allowedorreason=unauthorizedTraceability is by client profile id, so: -
admin endpoint traffic is attributed to
client_id=default -
ChatGPT web traffic is attributed to
client_id=chatgpt-web -
Claude web traffic is attributed to
client_id=claude-web
What is intentionally not stored in observability events:
- full memory bodies
- full image bytes
- raw image downloads
Search events do include a short query_preview, but the observability collection is designed to track behavior, not duplicate the corpus.
Retention is handled with Firestore TTL policies:
memory_events.expires_attargets 90-day audit retentionmemory_vectors_write_fingerprints.expires_attargets 30-day fingerprint retention- fingerprint documents keep numeric
dedupe_expires_atfor the short duplicate-write window
Quick start
-
Install dependencies:
npm --prefix functions install -
Create local env vars:
cp functions/.env.example functions/.envFor browser-hosted clients, set a scoped client profile in
functions/.envorfunctions/.env.prod:MCP_CLIENT_PROFILES_JSON=[{"id":"chatgpt-web","token":"replace-chatgpt-token","allowedTools":["remember_context","search_context","fetch_context"],"allowedFilterStates":["active"],"allowedOrigins":["https://chatgpt.com"]},{"id":"claude-web","token":"replace-claude-token","allowedTools":["remember_context","search_context","fetch_context"],"allowedFilterStates":["active"],"allowedOrigins":["https://claude.ai"]}] -
Run verification:
npm --prefix functions test npm --prefix functions run build -
Start emulators:
npm --prefix functions run serve -
Optional MCP smoke test:
cd functions
MCP_BASE_URL="http://127.0.0.1:5001/demo-open-brain/us-central1/metaCortexMcp/mcp" \
MCP_ADMIN_TOKEN="replace-me" \
MCP_SMOKE_MODE="admin-read-write" \
npm run smoke
Browser-client flow:
cd functions
MCP_BASE_URL="http://127.0.0.1:5001/demo-open-brain/us-central1/metaCortexMcp/clients/chatgpt-web/mcp" \
MCP_ADMIN_TOKEN="replace-chatgpt-token" \
MCP_SMOKE_MODE="browser-read-write" \
npm run smoke
Repeat with
/clients/claude-web/mcpand the Claude token to verify Claude separately.
Deployment
Deployment playbook: docs/DEPLOYMENT.md
For the next production deployment session, start with:
cd /Users/nick/git/metacortex
./scripts/deploy-session-preflight.sh