
vaportrail
B33BMO/vaportrail
Gravador local para sessões de agentes de IA — busca, replay e stats
Ver no GitHubFlight recorder local-first que lê e indexa transcrições de sessões de agentes IA de código (Claude Code, Codex CLI, opencode, Gemini CLI, Aider). Transforma pilhas de transcripts em histórico pesquisável e reexecutável, sem dependências externas ou telemetria.
Instalação
npx convez-ai B33BMO/vaportrail1 comando no terminal: detecta o formato do repositório (marketplace ou plugin avulso) e instala via Claude Code. Requer Node 18+ e o Claude Code instalado.
Métricas
Casos de uso
- Auditar e revisar o que agentes IA fizeram em seu repositório
- Buscar soluções anteriores por padrão (JWT, autenticação, etc)
- Analisar padrões de uso: arquivos mais modificados, consumo de tokens, modelos favoritos
- Reexecutar ou estudar sessões específicas de forma interativa
Veredito

Ferramenta essencial para quem usa agentes de IA em produção e precisa auditoria real das ações. Zero setup, lê nativamente de cinco formatos diferentes, mantém tudo local — ideal para equipes que querem governança sem overhead.
README
A tradução para o português deste README ainda está na fila.
vaportrail
Your agents leave trails. vaportrail reads them.
A local-first flight recorder for AI coding agent sessions. Every Claude Code, Codex CLI, opencode, Gemini CLI, and Aider session leaves a detailed transcript on disk — what you asked, what the agent did, every file it touched, every command it ran, every token it burned. vaportrail reads all five formats and turns that pile of transcripts into one searchable, replayable history.
Zero runtime dependencies. Nothing leaves your machine. One command to try it:
npx vaportrail
Why
AI agents now do a meaningful share of the work in your repos, but their history is write-only: gigabytes of transcripts nobody can read. vaportrail answers the questions that data was always able to answer:
- What did the agent actually do last Tuesday? →
vaportrail show <id> - Where did we solve this exact problem before? →
vaportrail search "jwt refresh" - Which files do agents churn on the most? What does a month of usage look like? →
vaportrail stats
Commands
vaportrail / vaportrail list
Recent sessions across every project — id, age, project, AI-generated title, prompt count, tool calls, output tokens, model.
vaportrail show <id>
Replay a session as a timeline: your prompts, the agent's narration, and every tool call with what it operated on.
vaportrail · session cca29f96…
title    Build SSH over WebSocket with agent enrollment
project  ~/wssh (main)
when     2026-06-02 22:14 → 2026-06-03 00:04 (1h 49m)
activity 16 prompts · 183 turns · 168 tool calls · opus-4-8

22:14:30  ❯ So.. I have a cool ass idea. So... SSH.. but over websocket…
22:14:47  ⚒ Bash ls -la /Users/b/wssh && command -v go node python3…
22:15:40  ✦ Hell yes — this is a great idea, and it's very buildable…
22:17:03  ⚒ Write /Users/b/wssh/go.mod
22:17:15  ⚒ Write /Users/b/wssh/main.go
...
Use --full for untruncated text.
vaportrail search <query>
Full-text search across your entire agent history — prompts and responses, with --regex for patterns and --tools to also match commands and file paths.
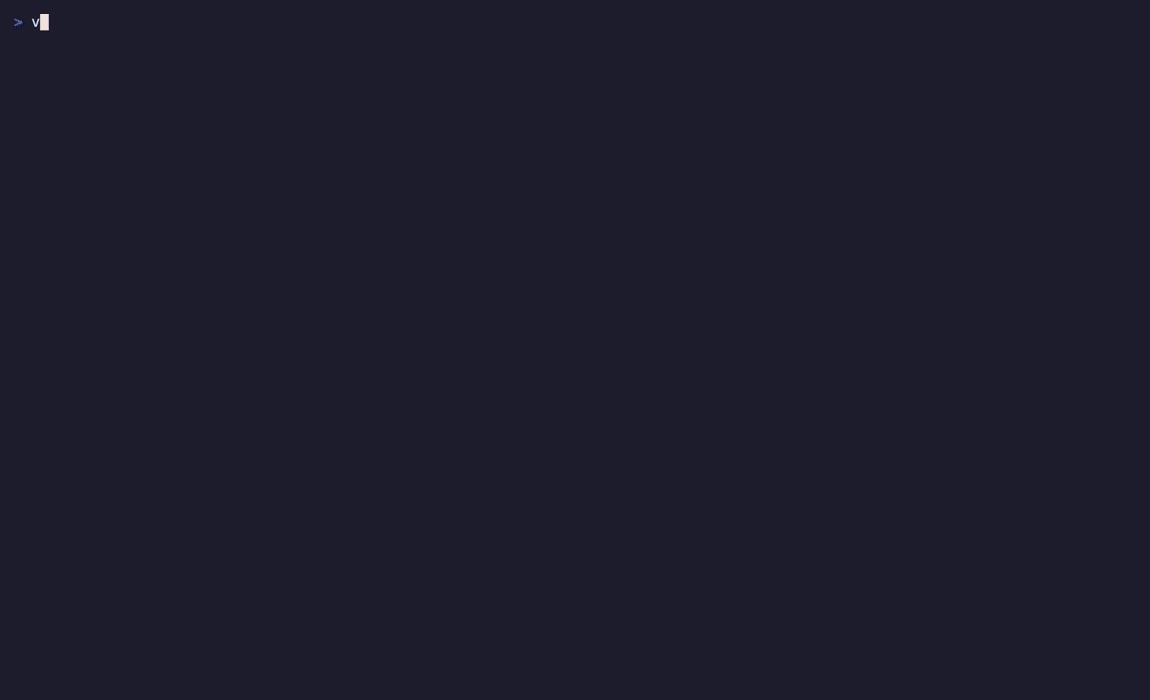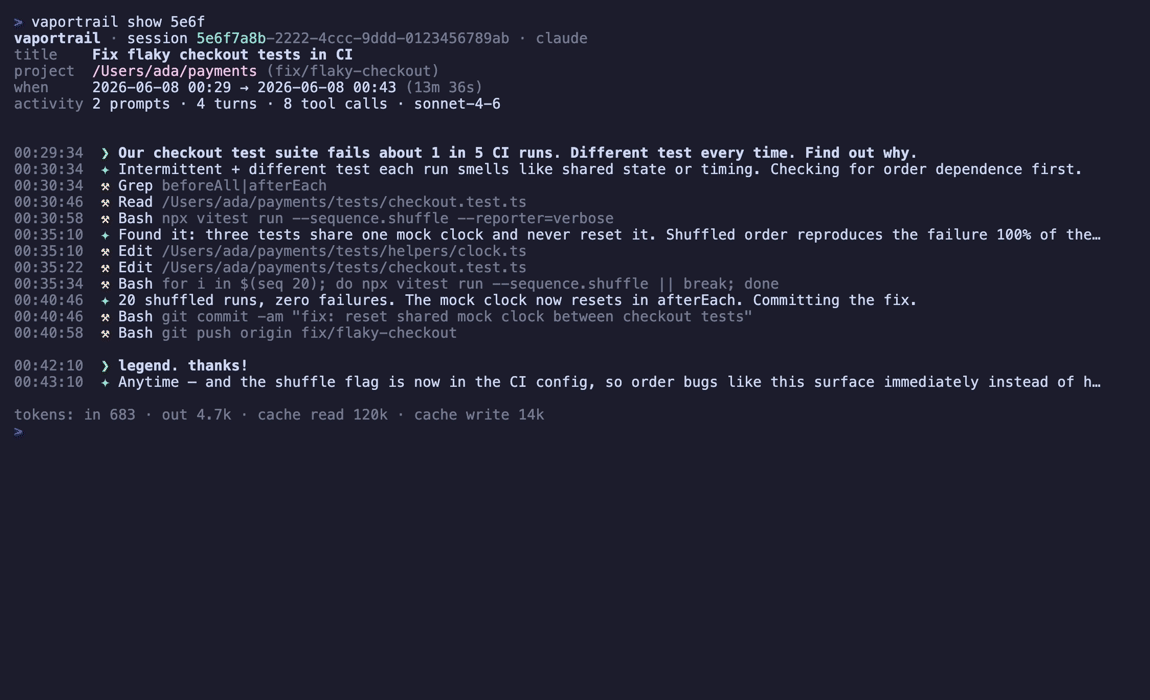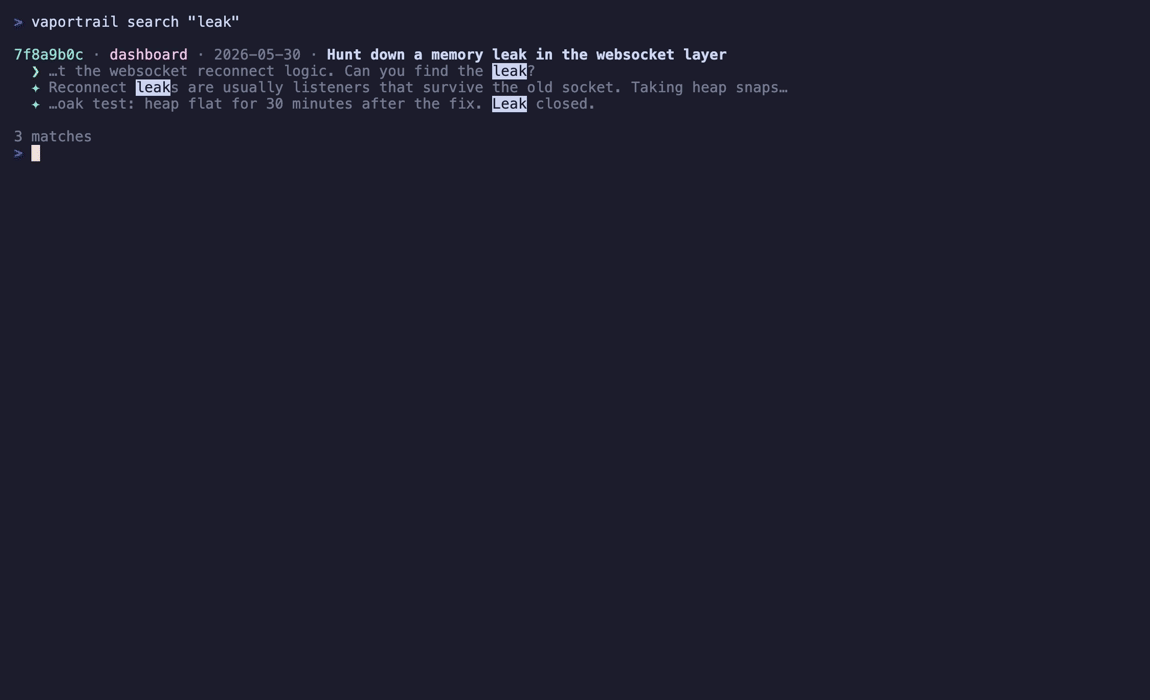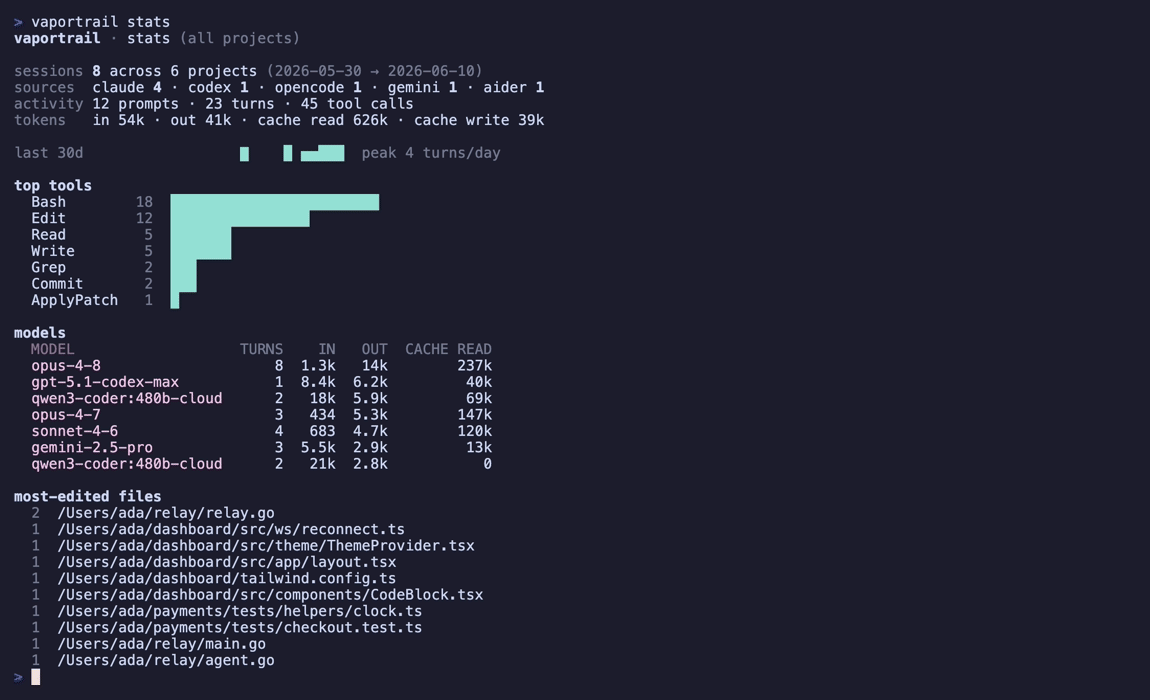
vaportrail stats
The big picture: sessions, prompts, turns, token totals (with cache split), a 30-day activity sparkline, a tool-usage leaderboard, per-model token tables, and the files your agents edit the most.
Options
| flag | meaning |
|---|---|
-s, --source <s> | agents to read: claude, codex, opencode (comma list; default all) |
-p, --project <s> | only sessions whose project path contains <s> (. = current dir) |
-n, --limit <n> | max rows / matches |
-a, --all | no limit |
-j, --json | machine-readable output for every command |
-d, --dir <path> | transcript root override (combine with -s for non-claude layouts) |
--agents | include subagent transcripts |
How it works
vaportrail reads each agent's native on-disk format — no hooks, no wrappers, no telemetry:
| agent | where it reads from |
|---|---|
| Claude Code | ~/.claude/projects/**/*.jsonl (honors CLAUDE_CONFIG_DIR) |
| Codex CLI | ~/.codex/sessions/**/rollout-*.jsonl (honors CODEX_HOME) |
| opencode | ~/.local/share/opencode/storage/ (honors XDG_DATA_HOME) |
| Gemini CLI | ~/.gemini/tmp/<hash>/chats/*.json — project hashes are reversed by hashing likely paths, with tool-call args as fallback |
| Aider | .aider.chat.history.md in ~ and project dirs up to two levels below it (markdown, parsed per embedded session) |
Everything is normalized into one session model: token usage is deduplicated where formats repeat it across entries, subagent work is separated from your own prompts, tool names are normalized across agents (shell_command and bash both count as Bash), and bookkeeping noise is filtered out. ~100 MB of history parses in about a second. Read-only: vaportrail never modifies a transcript.
Roadmap
- Codex CLI and opencode transcript formats
- Gemini CLI and Aider
- Cursor CLI (sessions live in SQLite; needs
node:sqlite) -
vaportrail export <id>— session → markdown / shareable gist - Cost estimates per session/model
- Local web UI (
vaportrail ui) with cross-session analytics - Watch mode — live tail of a running session
License
MIT © Brandon Bischoff