
Metric Mandate
aplaceforallmystuff/metric-mandate-claude
Defina métricas rigorosas ou não comece seu projeto de IA
Ver no GitHubSkill para Claude que força a definição de critérios de sucesso mensuráveis antes de iniciar projetos de IA. Guia através de 5 questões críticas (métrica específica, baseline atual, melhoria mínima, data de medição e critério de parada) e stress-testa a métrica contra gaming — evitando projetos que derivam indefinidamente sem definição clara de fracasso.
Instalação
npx convez-ai aplaceforallmystuff/metric-mandate-claude1 comando no terminal: detecta o formato do repositório (marketplace ou plugin avulso) e instala via Claude Code. Requer Node 18+ e o Claude Code instalado.
Métricas
Casos de uso
- Planejamento de projetos de IA com objetivos mensuráveis
- Avaliação de viabilidade antes de iniciar desenvolvimento
- Prevenção de projetos que derivam sem sucesso definido
Veredito

Ferramenta valiosa para equipes que querem rigor métrico, mas exigente demais para exploração inicial. Recomendado para quem precisa justificar investimentos em IA com objetivos claros e mensuráveis.
README
A tradução para o português deste README ainda está na fila.
The Metric Mandate - Claude Code Skill

An installable Claude Code skill that forces you to define measurable success criteria for AI projects before you start building.
What This Does
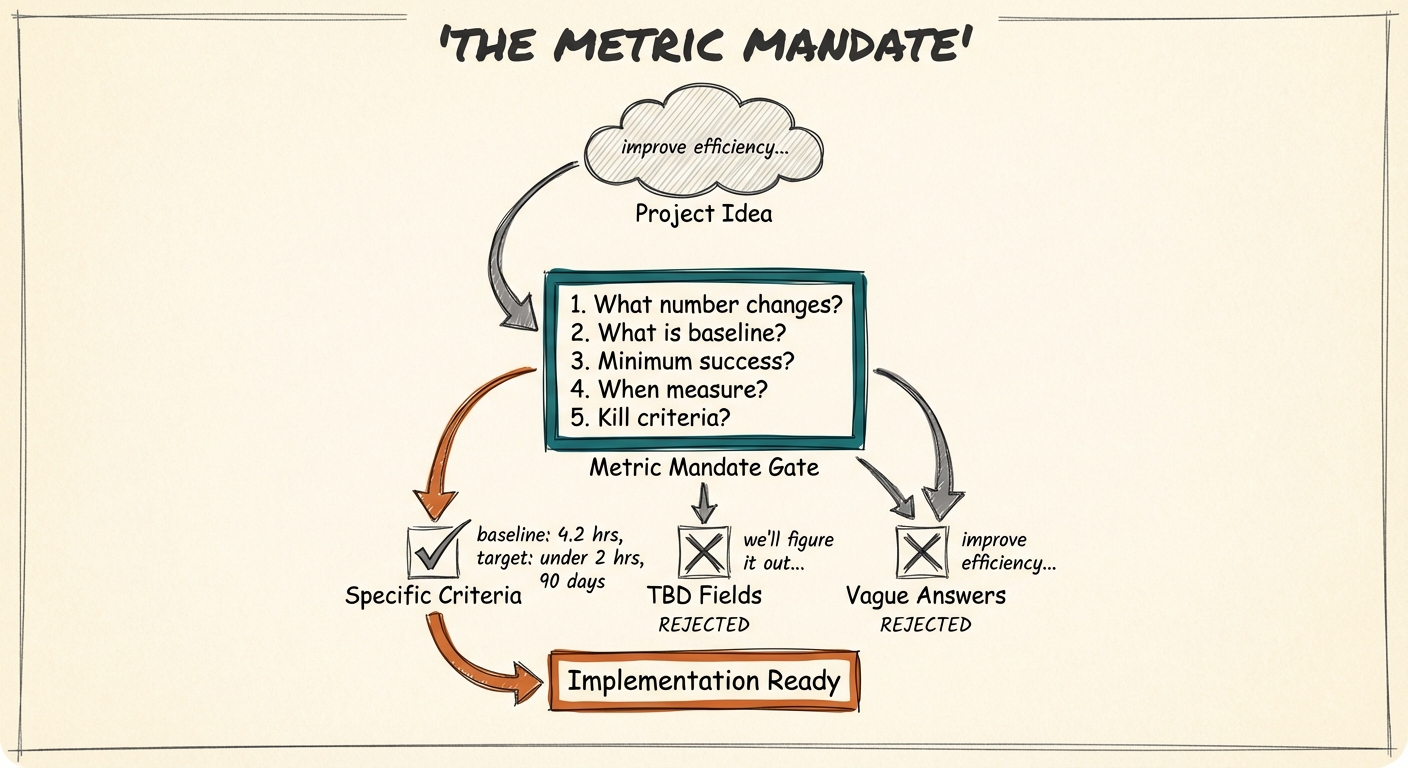
Before any AI project moves past the idea stage, you need to answer 5 critical questions:
- What specific number will change?
- What is that number today? (baseline)
- What's the minimum improvement that justifies the investment?
- When will you measure?
- What result means you stop? (kill criteria)
Then it stress-tests your metric: "How would someone hit this number without actually solving the problem?" If the answer is easy, you need a companion metric. If it's hard, your metric is robust.
This skill guides you through all 5 questions, rejects vague answers, and runs a gameability check before declaring you ready.
Why This Matters
Projects without clear metrics can't fail. There's no definition of failure. So they drift indefinitely, consuming budget while delivering "learnings" instead of results.
Six months later, someone asks "Did the AI project work?" and the honest answer is "We don't know, because we never defined what 'working' meant."
The Metric Mandate prevents that.
Installation
For Claude Code Users
cd ~/.claude/skills
git clone https://github.com/aplaceforallmystuff/metric-mandate-claude metric-mandate
Then invoke with /metric-mandate in any Claude Code session.
For Claude Desktop Users (Projects)
- Download this repository
- Copy the contents of
skill.md - In Claude.ai, create a new Project
- Add
skill.mdcontents to "Custom Instructions" - Start a conversation describing your AI project
Usage
- Invoke the skill:
/metric-mandateor mention you have an AI project idea - Describe your AI project when prompted
- Answer each of the 5 questions as the skill guides you
- The skill will reject vague responses and push for specifics
- After all 5 questions, the skill stress-tests your metric for gameability
- When complete, you'll get a summary table with all criteria and gameability status
Example Transformation
Before (vague): "We want to use AI to improve our customer service."
After (specific): "We want to reduce average ticket resolution time from 4.2 hours to under 2 hours within 90 days. If we're not below 3 hours by day 60, we'll reassess the approach. Current baseline measured from Q4 2024 data across 12,000 tickets. Gaming vector: agents closing tickets prematurely — mitigated by maintaining CSAT at or above 3.8/5."
What Makes This Different
Most AI project planning tools accept vague goals. This one doesn't. It's deliberately rigid because:
- Projects without clear metrics can't fail (which means they can't succeed either)
- Vague goals lead to "sort of done" results
- If you can't answer these 5 questions with specific numbers, you're not ready to build
- Specific metrics can still be gamed — the gameability check catches this before you start
The discomfort you feel defining kill criteria? That's the point. If you won't commit to when you'd stop, you probably shouldn't start. And if you can easily describe how to hit your metric without solving the problem, you've picked the wrong metric.
Files
skill.md- The Claude Code skill definition (core functionality)README.md- This fileLICENSE- MIT Licenseexamples/- Sample conversations and outputsdocs/images/- Architecture diagram
Related Tools
- ChatGPT version: metric-mandate-chatgpt - Copy-paste prompt for ChatGPT users
Origin Story
This framework comes from the Signal Over Noise newsletter article: "The Metric Mandate: Why 'Improve Efficiency' Isn't a Goal"
Written by Jim Christian, an AI consultant and strategist based in Valencia, Spain.
Contributing
Found a way to improve the skill? Open a PR or issue.
License
MIT License - See LICENSE file for details.
Free to use, share, and adapt with attribution.
Author
Jim Christian
- Newsletter: Signal Over Noise
- Website: jimchristian.net
- Open Source: signalovernoise.at/open-source
Part of the Signal Over Noise open-source collection - practical tools for AI implementation without the hype.